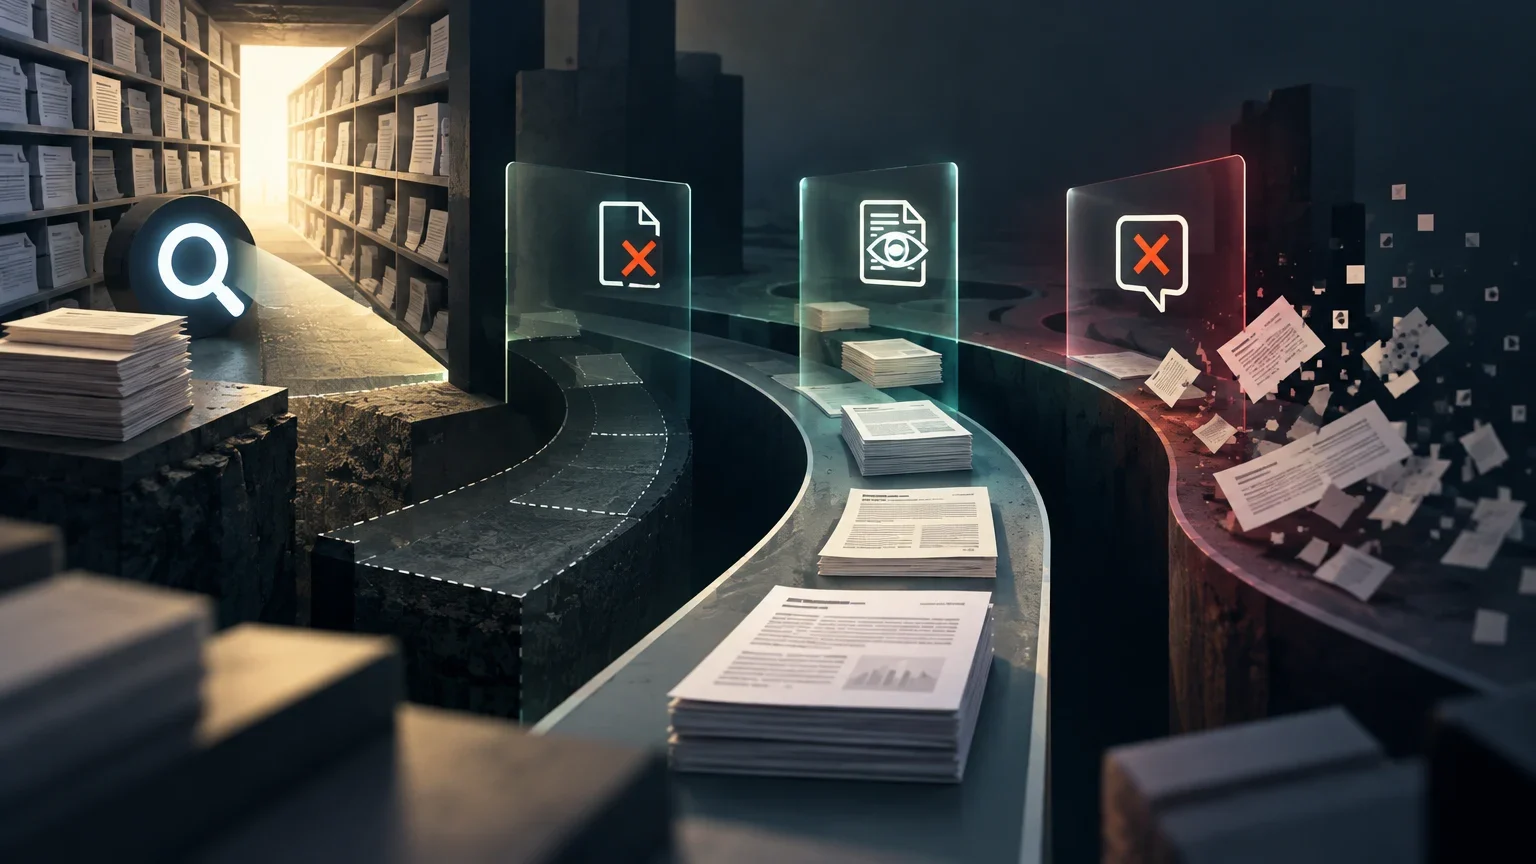
The limits of evaluating only the final answer
Traditional evaluations of scientific-search agents focus on the accuracy of the final answer. But a single accuracy score combines different kinds of failure: an agent may not find the target paper, may find it without inspecting it, or may inspect it and still produce an incorrect answer.
That lack of visibility makes systems harder to improve because it does not identify where the error occurred. A preprint by Hongmin Li and Wanli Zhao proposes an audit method that records intermediate events during inference, allowing failures to be classified in more detail. The central idea is to examine not just what an agent answered, but also what it encountered and what it attempted to do along the way.
Decision checkpoints during the search
The study introduces “decision checkpoints” that record observations and tool actions during inference, without using benchmark labels while the agent is running. The records are used to determine whether the agent was exposed to the target paper and whether it attempted to inspect it.
After inference, the target identities and evaluator labels are joined to the recorded events to assign outcome categories. This makes differences visible question by question and separates target exposure and inspection from both aggregate accuracy and total tool use. The method is designed to classify events in the search process rather than to rely on the final answer as the sole measure of what happened.
How the audit works
Events are recorded while the agent runs, then classified after its actions have been matched to the target and evaluator labels.
- 01Record the agent’s observations and tool actions during inference, without providing benchmark labels during that process.
- 02Join the recorded events to target identities and evaluator labels after inference.
- 03Assign outcome categories based on the recorded events.
Experimental conditions and reported comparisons
The experiment covered 540 answerable questions from AutoResearchBench Deep, across five conditions, in a fixed environment enriched with target documents. That setting is important to interpreting the results: the reported numbers describe these questions and this experimental configuration, not scientific search in general.
Within this setup, keyword search achieved 24.6% accuracy, compared with 17.8% for raw search. The study also reports that read-first recorded 27.4% more evidence-search calls than keyword search. These figures describe different aspects of performance: accuracy measures accepted answers, while evidence-search calls count recorded tool activity.
Selected results reported in the preprint
The accuracy figures and evidence-search comparison come from the study’s fixed, target-enriched experimental environment.
| Condition or comparison | Reported result | What the result measures |
|---|---|---|
| Keyword search | 24.6% accuracy | Accuracy on the 540 answerable questions. |
| Raw search | 17.8% accuracy | Accuracy in the same reported experimental setting. |
| Read-first compared with keyword search | 27.4% more recorded evidence-search calls | Recorded tool activity, not an accuracy increase. |
Separating retrieval, inspection, and answer failures
The event categories show why a single accuracy score can conceal different patterns. Compared with raw search, keyword search had fewer incorrect answers in which the target had been neither exposed nor inspected. At the same time, keyword search had more incorrect answers in which the target had been exposed but left uninspected. Those categories distinguish failing to encounter the paper from encountering it without attempting to inspect it.
Recorded attempts to inspect the target occurred on 199 questions under read-first and 191 under keyword search. Both conditions achieved 24.6% accuracy. In this experiment, therefore, more recorded inspection attempts did not correspond to higher aggregate accuracy. The comparison does not establish why the answers were wrong in individual cases, nor does it show that inspection is generally ineffective; it shows that inspection attempts and accepted answers are separate measurements.
Why these results do not establish general reliability
The findings come from a fixed environment enriched with target documents. That configuration may differ from open-ended scientific search, where relevant papers are not deliberately supplied as targets and the available material can be broader or less predictable. The preprint’s abstract does not provide enough detail to specify exactly how the enriched environment was constructed or to quantify the biases it may introduce.
The work is a preprint, submitted on September 29, 2026. The available source establishes that it was posted as an arXiv preprint; it does not establish peer review or independent replication. Its reported results should therefore be read as findings from one study and one stated experimental setup, not as evidence that AI search agents are reliable—or unreliable—in every scientific-search context.
Open questions
- The supplied abstract does not specify the exact AI models, tools, or configurations used in each of the five conditions.
- The abstract does not explain in detail how the target-enriched environment was constructed or quantify the biases it may introduce.
- The supplied source does not establish whether public data or traces are available to reproduce the failure categories.
- The source identifies the work as a preprint but does not establish peer review or independent replication.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction