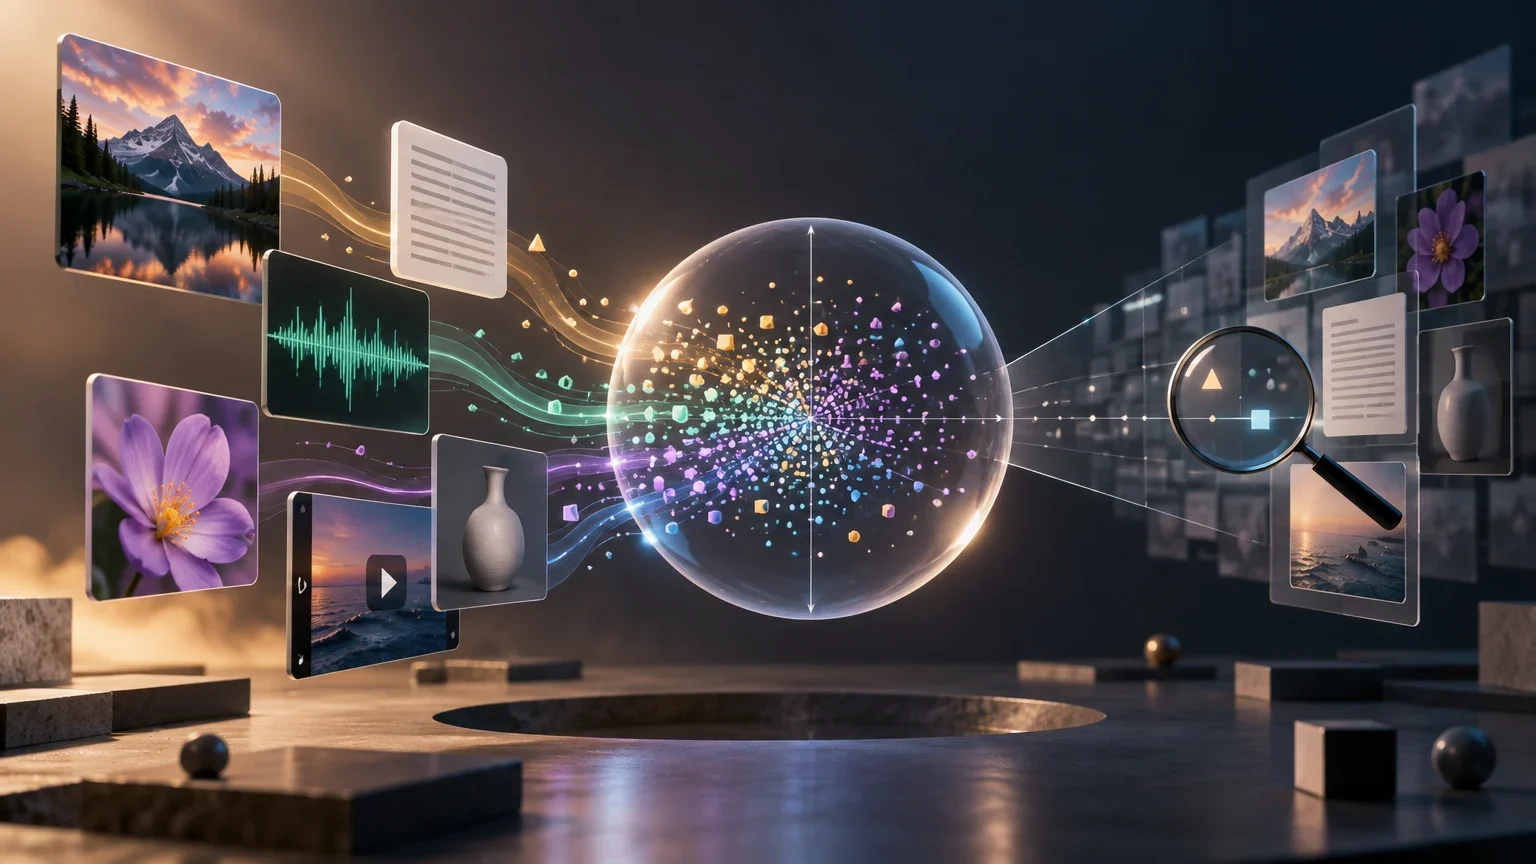
What can be said about Gemini Embedding 2
The official sources provided describe Gemini Embedding 2 as a multimodal embedding model. The Gemini API documentation says it accepts text, images, video, audio, and documents; Google’s blog describes it as mapping those modalities into a shared embedding space. The Gemini Enterprise Agent Platform documentation also identifies it as an embedding generation model and mentions multimodal inputs. Taken together, these pages support a description of capabilities that Google attributes to the product.
That support has an important limit: documenting that a model accepts certain input types does not prove that it retrieves relevant information more accurately in every application. Nor does it establish how the model performs on a particular corpus, whether representations of different modalities are useful for a specific task, or how much it costs to run that task. Those are separate questions and require different evidence.
It is therefore useful to distinguish three levels. First, the provider’s published specification, which describes supported modalities and stated purpose. Second, the provider’s performance claims, which need to be interpreted in light of their test conditions. Third, results a team obtains on its own data and queries. The sources provided mainly support a description of the first level and help frame questions about the other two; they are not enough to answer those questions independently.
What a shared space means—and what it does not
The phrase “shared embedding space” suggests that the model can produce representations that make it possible to work with content from different modalities within a common framework. That description is relevant to applications that want to connect, for example, a text query with content that is not expressed solely as text. It is a functional possibility worth evaluating; it is not a guarantee that every combination of modalities will work equally well.
The information summarized in the available sources does not specify the vector dimensions, input limits, transformations applied to each modality, or the conditions under which their representations are compared. Nor does it establish that any file or combination of modalities can be submitted without restrictions. Those details should be checked in the current documentation for the channel a team intends to use and tested with representative inputs.
Practical value depends on the task. In retrieval, generating vectors is not enough: the system must return relevant results for the queries its users actually make. In a multimodal use case, queries and retrieved items may also differ in format. An aggregate result can therefore conceal differences between text, images, audio, video, or documents. A test that measures only one modality does not automatically support conclusions about the others.
Separate specification, hypothesis, and evidence
| Question | What the available sources support | What remains to be verified |
|---|---|---|
| What types of content does it accept? | Google describes inputs including text, images, video, audio, and documents. | The specific formats, limits, and conditions for each type. |
| Does it represent different modalities within a shared framework? | Google presents the model as mapping them into a unified embedding space. | How that capability works in each task and combination of modalities. |
| Does it improve retrieval in a particular system? | The multimodal specification does not answer this question on its own. | Results using representative corpora, queries, relevance judgments, and comparators. |
Performance claims need context
The proposed scope of this article calls for examining a Google claim about improvements in accuracy and retrieval across millions of records. The verifiable material provided does not include the complete protocol, metrics, data composition, or comparison models needed to interpret that claim as independent quantitative evidence. It should therefore be presented as a manufacturer statement, not as a result that can already be generalized to a third-party application.
The stated scale does not, by itself, resolve the methodological questions. To interpret a performance figure, it is necessary to know what was measured, how relevance was defined, and what configuration was used. It also matters whether the result concerns a text-only task or a combination of modalities, and whether the evaluated scenario resembles the one a team is considering. The sources available for this article do not provide enough information to settle those questions.
A public quantitative evaluation would be useful only if the exact model can be identified, its configuration inspected, and the protocol reproduced to a reasonable extent. The existence of a reproducible score should not be inferred simply because an official page describes the model or a provider publication reports an improvement. Without those details, the responsible conclusion is limited: Google attributes multimodal capabilities to the model, but the supplied material does not by itself establish how much it will improve any particular retrieval task.
Access: confirm the channel and exact model
The official sources provided include Gemini API documentation, a Gemini API models page, and Gemini Enterprise Agent Platform documentation. The latter identifies Gemini Embedding 2 within that channel. This evidence supports saying that the model appears in Agent Platform documentation; it is not enough to claim that every channel has identical availability, interface, identifier, terms, or limits.
Before integrating a test, a team should check the current documentation to determine which channel is available for its use case, which name or identifier to invoke, and what restrictions apply. It should also confirm that the instructions it consults refer to the exact product and model, rather than carrying details from Gemini API over to Agent Platform, or vice versa, without checking. The models documentation can guide that review, but it does not replace operational confirmation for the selected channel.
The sources provided do not allow us to specify a model identifier, context limit, vector dimensions, or a complete list of technical restrictions here. Those values should not be invented or treated as common across channels. If a decision depends on them, they should be recorded as open questions and resolved by consulting current official pages and, where appropriate, running a controlled test.
Access checks before testing
- 01Choose the product and channel to evaluate; do not assume Gemini API and Agent Platform are interchangeable.
- 02Confirm in the current documentation that the exact model is listed for that channel, and record its published identifier.
- 03Check supported inputs, limits, formatting requirements, and terms that apply to the intended account and deployment.
- 04Record the date and documentation consulted so the test results can be interpreted alongside the configuration used.
Pricing: do not turn a secondary-source figure into an official rate
One secondary source included in the materials displays a price of USD 0.20 per million tokens and associates it with the model. Its search result does not establish that this is an official Google rate, that it is current for every channel, or that it covers multimodal inputs. The supplied information itself notes that the figure refers to text. It is therefore not appropriate to present it as a confirmed general cost for Gemini Embedding 2.
Google maintains official pricing pages for Gemini API and Agent Platform. The information provided confirms that these pages exist, but does not provide a passage establishing a specific rate for Gemini Embedding 2. The general Gemini API pricing page is not enough to attribute a price to this model; nor can a rate for one channel automatically be transferred to another. Verification must be performed for the exact model, product, and modality.
The billing unit should also be checked before estimating the cost of a multimodal application. The sources summarized here provide no basis for claiming that text, images, audio, video, and documents are billed in the same way. An operational budget should separate expected volume by modality and note which official pricing treatment has been confirmed for each. If a rate cannot be verified for a component, the estimate should mark it as unresolved rather than fill the gap with a secondary-source figure.
How to treat pricing references
| Reference | What can be concluded | What should not be concluded |
|---|---|---|
| Secondary source: USD 0.20 per million text tokens | The secondary source publishes that figure for text. | That it is a current official rate or applies to every modality and channel. |
| Official Gemini API pricing page | It is an official source to consult for pricing in that channel. | That the supplied excerpt confirms a specific price for Gemini Embedding 2. |
| Official Agent Platform pricing page | It is relevant for checking costs in that channel. | That the available evidence mentions or confirms a specific rate for this model. |
Security and data handling: what has not been established
The sources provided describe capabilities and access or pricing pages. The available excerpts do not contain enough specific information about retention, input handling, data controls, or the use of information sent to Gemini Embedding 2. It is therefore not possible to assess those conditions from this material. The absence of those details in the excerpts does not prove that no such documentation exists; it means that no evidence has been supplied to support a conclusion about them.
Nor should security assurances be inferred from the model’s support for multiple modalities, its appearance in Google documentation, or its stated suitability for retrieval and analytics tasks. Those descriptions concern capabilities or stated uses; on their own, they do not address the data-handling obligations that apply to an organization.
Before sending real content, a team should review the contractual and technical documentation for the chosen channel, along with its own obligations concerning the data. If retention, access, or use terms cannot be confirmed, an initial test could use controlled or non-sensitive data, provided that approach is compatible with the evaluation’s purpose. This is an operational precaution, not a claim that the model has any particular policy.
How to design an in-house test without prejudging the result
A useful evaluation should answer a specific product question, not merely confirm that the model generates embeddings. A team can select queries and corpus items representative of its real tasks, define in advance what counts as a relevant result, and compare the outputs with an appropriate baseline. If the intended use includes more than one modality, results should be analyzed separately as well as in any aggregate measure.
The test set should reflect the cases that matter most: frequent queries, difficult cases, and examples of each modality the system is expected to index or search. The protocol should keep comparison conditions constant where possible and record the model version or identifier, access channel, and configuration. This makes it easier to attribute an observed difference to the change being tested rather than to an unnoticed variation in the procedure.
In addition to relevance, an operational decision may depend on latency, estimated cost, limits, and ease of integration. No results for these variables have been provided, so they need to be measured or verified in the team’s own context. The following steps are a proposed evaluation, not a description of tests already carried out or a promise of improvement.
A minimum evaluation protocol
- 01Define the task and success criteria before running the test; for example, specify which results count as relevant for each query.
- 02Build a representative sample of the corpus and queries, with reviewed relevance judgments and modality-specific breakdowns where necessary.
- 03Compare Gemini Embedding 2 with an appropriate baseline under documented conditions, without changing several parts of the system at once.
- 04Record the channel, model identifier, configuration, processed volume, and access conditions used.
- 05Measure relevance, latency, and observed or estimated cost separately; explicitly identify metrics that cannot be obtained.
- 06Review errors and edge cases. Decide whether the result justifies a larger test rather than extrapolating it automatically to other corpora or modalities.
Conclusion: stated capability, decision still open
The available sources support describing Gemini Embedding 2 as a model that Google presents as generating embeddings from multiple modalities and representing them in a shared space. That specification makes it reasonable for search and document-management teams to consider evaluating it when their use case requires connecting heterogeneous content. It does not, however, demonstrate that the model is superior to an alternative on a particular corpus, nor does it allow the total cost or data-handling conditions to be predicted.
The claim about improvements in accuracy and retrieval should remain a manufacturer statement unless sufficient details about the protocol, metrics, and comparators are available. The USD 0.20 per million tokens figure comes from a secondary source and is not confirmed as an official rate applicable to all modalities. Agent Platform documentation confirms that the model appears in that channel, but access and the conditions for the chosen channel should be checked before integrating a test. The supplied sources are also insufficient to assess retention, input handling, or data use.
The most defensible decision is neither to accept nor reject the model based on a general claim, but to turn the unknowns into checks. Confirm capabilities and limits for the exact channel, obtain official pricing for the intended use, review data documentation, and run an in-house test using criteria set in advance. This allows a team to proceed without confusing a specification with a result. Until then, performance, multimodal cost, and security conditions should remain explicitly unresolved.
Open questions
- There are not enough details to verify the protocol, datasets, metrics, or comparators behind the claim of improvements across millions of records.
- No current official rate for Gemini Embedding 2 is confirmed for either Gemini API or Agent Platform.
- The available sources do not establish how different modalities are billed or whether costs are comparable across channels.
- Input limits, vector dimensions, the exact model identifier, and complete technical restrictions are not provided.
- The available excerpts do not adequately describe retention, data handling, controls, or the use of inputs.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction