What We Know—and What the Documentation Does Not Yet Demonstrate
The question this benchmark addresses is not whether an image looks attractive, or whether the model can produce a convincing edit in a single example. It is more specific: when someone requests several changes over successive turns, are the requested changes made while elements the model was not asked to touch remain stable? We also want to know whether errors from one edit carry over to the next and accumulate.
Google presents Nano Banana 2 in developer-facing documentation and describes capabilities related to image generation, image editing, and iteration. That description helps establish the model’s stated purpose, but it is not an independent measurement of how well it preserves details across multiple turns. The available sources do not provide quantitative results for this specific task or a protocol from which a performance level could be inferred.
What follows, therefore, is a proposed evaluation—not a report of results. It does not assign the model a success rate, declare it better or worse than an alternative, or assume that an edit automatically preserves the state of the previous one. Before running the test, the team will need to confirm exactly which version can be accessed, through which interface, and with what controls.
The Benchmark’s Operational Question
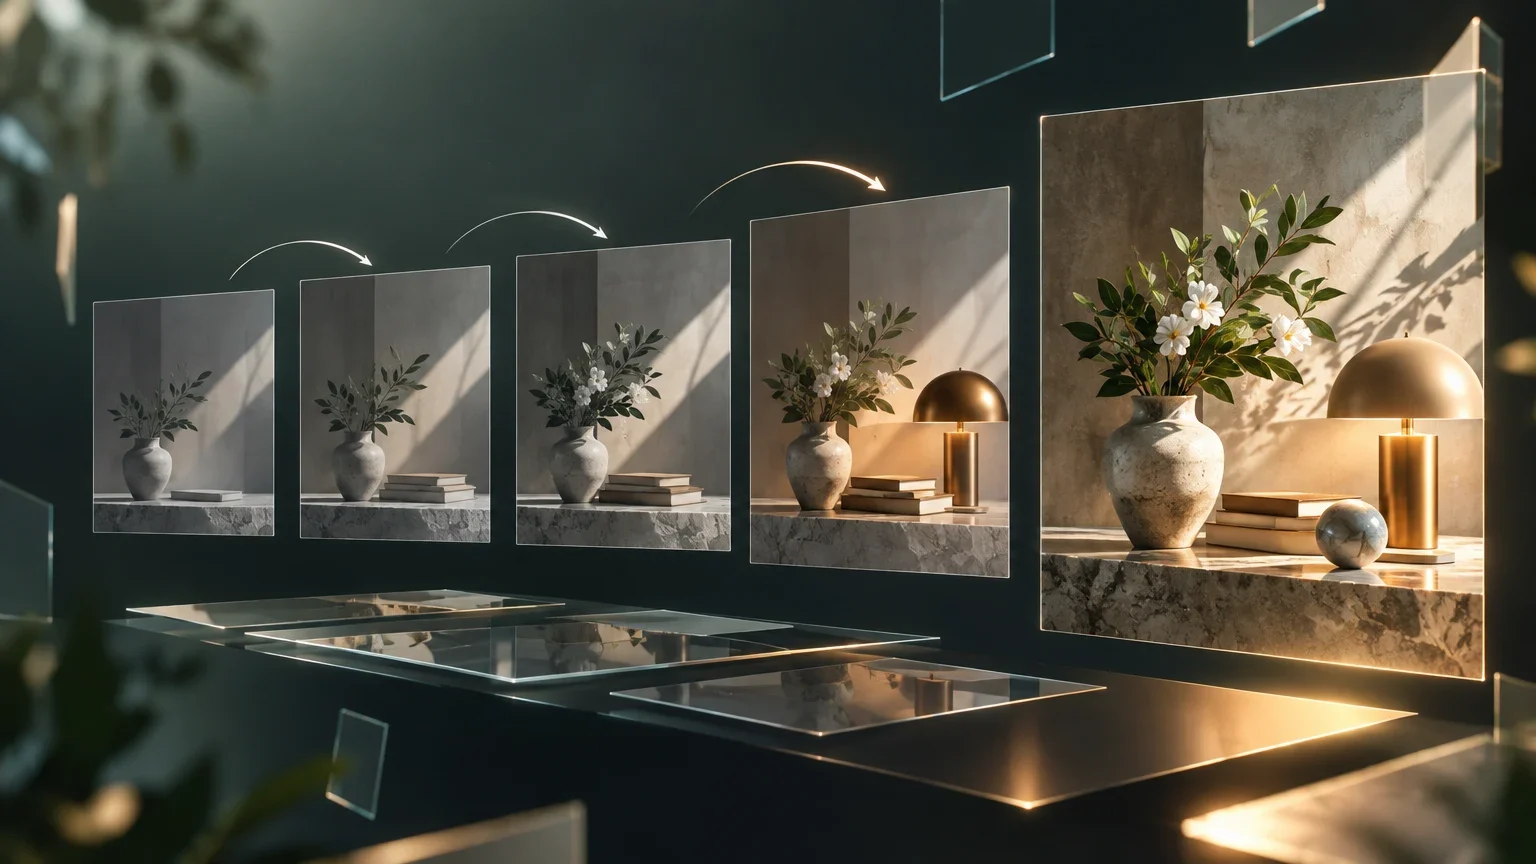
The use case starts with an image and requests changes in sequence. For example, first change the color of a jacket, then replace the background, and finally add an object to a table. At each step, the test should check both the requested change and the preservation of elements unrelated to it: face, pose, garments not mentioned, objects, framing, and relevant features of the background.
The evaluation must separate two obligations. The first is compliance: did the requested change appear in that turn? The second is preservation: did the elements designated as controls remain stable enough? An output can satisfy one obligation and fail the other. If the only score is overall resemblance or visual appeal, such failures may go unnoticed.
The test should also record whether an output introduces defects that affect later turns. A deformed hand in the first turn may remain deformed after subsequent instructions about other elements. The benchmark should not automatically attribute that defect to the latest instruction: it needs to retain images from every stage and score the full sequence.
What to Score Separately
| Dimension | Question | Example of a failure |
|---|---|---|
| Requested change | Was the requested change made in this turn? | The instruction asks for the jacket color to change, but it stays the same. |
| Preservation | Were the elements designated as unchanged kept intact? | The pose or face changes as well. |
| Sequence consistency | Does the result remain compatible with the initial image and previous turns? | An edit replaces details that had already been accepted. |
| Accumulated errors | Do defects appear or persist across turns? | An object is duplicated, and the duplication remains in later outputs. |
Task Design and Image Selection
The test set should include a range of initial images, featuring people, objects, indoor and outdoor scenes, and different levels of complexity. Variety alone does not establish representativeness; it helps determine whether observed behavior depends on content type. Any conclusions must be limited to the categories and conditions actually evaluated.
For each image, prepare an instruction sequence and a list of target and control elements in advance. Targets are the elements the model is asked to change. Controls are the elements the instruction should leave untouched. A task sheet can specify what must change, what must be preserved, which collateral changes matter, and what ambiguities might lead evaluators to disagree.
Instructions should be specific, but not so rigid that the benchmark becomes a check for one exact answer. For example, changing a mug to a blue mug may allow variation in shape and texture; keeping the number of people the same or maintaining a lamp’s approximate position may be more objective criteria. Define acceptance criteria and exclusions before querying the model.
The case selection should also avoid relying only on easy or visually striking examples. Report how images were collected, how many tasks were excluded, and why. If materials have usage restrictions or include personal data, document their provenance and any relevant safeguards. The available sources do not establish what training data the model used or whether it overlaps with a particular evaluation set; that uncertainty should remain explicit.
Execution Conditions and Comparison
Before running any cases, the team should identify the exact model and version offered through the chosen access channel. A name displayed on a page or in an interface is not enough if it does not reliably distinguish Nano Banana 2 from other image models. Record the test date, interface or API, available parameters, image format and size, and any system instructions that affect editing.
How state is handled between turns is a crucial condition. The interface might retain conversational context, or the person running the test might need to send the resulting image again at every step. These are not interchangeable conditions: in the latter case, the model receives a new input image on each turn. The protocol must state what happens and retain the instructions and images sent and received.
As a reference condition, the iterative workflow can be compared with a single-pass condition: combine the planned changes into one instruction and perform one edit. The comparison is informative only if both workflows use the same model, initial images, input quality, parameters, and generation opportunities, to the extent that the access channel allows. If these conditions differ, disclose the differences and avoid attributing the outcome solely to the number of turns.
The comparison will not always be perfectly equivalent. A combined instruction may be longer or more ambiguous than the successive instructions, while a sequence may allow corrections that a single pass does not. These differences are part of the practical question, but they must be described precisely. If access does not allow a comparable condition, the team can run the iterative test and present it as such, without claiming to have demonstrated an advantage over a single pass.
Minimum Preparation Before Testing
- 01Confirm the identity of the model and the available version.
- 02Record the access channel, date, and all exposed parameters.
- 03Determine whether state is retained in the conversation or the image must be resent on every turn.
- 04Freeze the images, instructions, target elements, controls, and exclusion rules.
- 05Set in advance how many runs to perform per case and how to handle failures.
Metrics, Human Review, and Results
The primary result should not be compressed into one score without explaining what it combines. At a minimum, report separately whether each requested change was fulfilled, whether each control was preserved, how consistent the output remained with the initial image, and which errors were new or persisted. The percentage of criteria passed can be calculated, but counts and examples of failures should also be presented so that aggregation does not hide important cases.
Human evaluation is appropriate because some criteria—such as preserving a person’s appearance—may require visual judgment. To reduce bias, write the rubric before inspecting the outputs. Where feasible, evaluators should not know which condition produced each image. If several people evaluate the outputs, report their level of agreement and how disagreements were resolved. An informal impression should not be presented as a reproducible measurement.
Automatic metrics can help compare images or detect changes, but they should not replace checking whether the instruction’s intent was fulfilled. The team will need to specify which tools were used and what they measure. High overall similarity, for example, could coexist with an incorrect change to a small detail; a large overall difference may be expected when the requested change is a background replacement.
To describe variation across runs, repeat cases under documented conditions whenever the access channel allows new generations. Set the number of repetitions before interpreting results, and publish it alongside failures, invalid outputs, and any incidents. Do not select only the best output for each case: that measures performance after selecting results, not the reliability of a typical run.
Proposed Scoring Rubric
| Criterion | Suggested scale | What to record |
|---|---|---|
| Requested change | Pass / partial / fail | Whether the change is present and to what degree, using a task-specific criterion. |
| Control preservation | Preserved / altered / not assessable | The observed element and the type of alteration. |
| Consistency across turns | No regression / minor regression / major regression | Which previously accepted element changed and in which turn. |
| Output validity | Valid / technical failure / not scoreable | The reason for exclusion or failure, without removing it from the count. |
Reproducibility, Limitations, and the Scope of Conclusions
A reproducible report should publish the task list, exact instructions, the provenance or description of the images, available parameters, number of runs, and scoring rubric. It should also show failed results and explain exclusions. When images cannot be shared because of licensing, privacy, or other restrictions, explain that limitation and provide enough description to show how the cases were assembled.
The available background studies do not resolve this evaluation by themselves. A study of Nano Banana Pro across different vision tasks concerns another model and another test design; its conclusions cannot be transferred to Nano Banana 2 or conversational editing across turns. Similarly, a benchmark of Nano Banana 2 Lite is not a direct comparison of the exact model proposed here. An image-restoration evaluation of Nano Banana 2 may provide context on a related task, but it does not necessarily measure preservation of elements after successive instructions.
If the protocol is run, conclusions should be limited to the versions, conditions, images, and tasks tested. A good result on a small number of scenes does not establish reliability for all visual editing, other access channels, or professional uses with different requirements. Nor does it support conclusions about tasks that were not included. If there is no verifiable way to identify the model or record the conditions, describe the test as exploratory rather than fully reproducible.
Practical Criteria Before Making a Decision
For a team considering turn-based editing in a workflow, the decision should be based on tasks close to its own use case, not only on demonstration images selected by the provider. Prioritize elements whose alteration would have important consequences—such as identity, text, logos, product objects, or scene components—and define what level of collateral change is acceptable.
Before interpreting any score, check four things: that the tested model is unambiguously identified; that it is clear how state is passed between turns; that requested changes and elements to preserve are scored separately; and that the report includes variation, errors, and limitations. If any of these are missing, the resulting evidence will be weaker, and that uncertainty should inform the decision.
The available documentation justifies asking the evaluation question, but it does not answer it in advance. The next step is not to declare a winner, but to run a controlled test, retain the complete record, and publish results that distinguish a successful edit from a genuinely stable sequence.
Open questions
- The available documentation does not establish a verifiable quantitative metric here for preserving details during successive edits.
- It must be confirmed which access channel unambiguously identifies Nano Banana 2 and which exact version it runs.
- It has not been verified whether the access channel retains state between turns or requires the edited image to be resent.
- There is not enough information to specify concrete parameters, a number of runs, or technical access conditions.
- The supplied sources do not establish whether images in any test set overlap with training data.
- The supplied studies of Nano Banana Pro, Nano Banana 2 Lite, and image restoration are not direct results for the proposed task of turn-based visual editing.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction