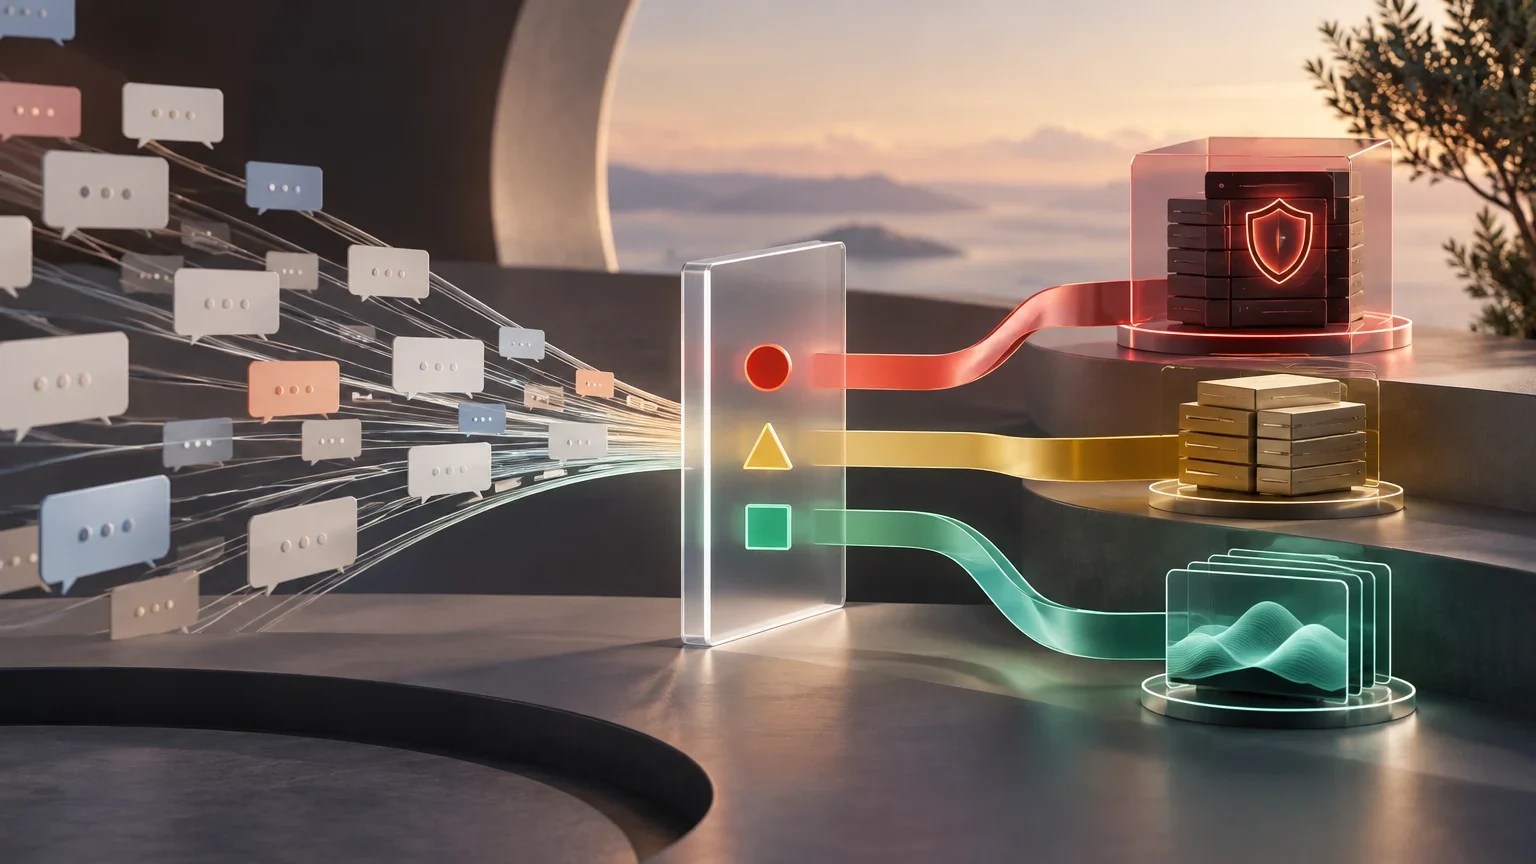
The Challenge of High-Volume Customer Service
Customer service is characterized by a high volume of repetitive interactions and an error margin that varies drastically depending on the type of query. Operations teams face the challenge of balancing operational efficiency with response quality, a challenge that conversational artificial intelligence addresses through natural language processing and machine learning.
According to data from the IBM Institute for Business Value, executives anticipate a 53% increase in the use of AI to drive personalized self-service and a 47% improvement in self-service call resolution by 2027. This trend indicates a shift toward automation, but it requires an architecture that does not apply the same technology to all cases, but rather adapts it to the nature of the interaction.
The operational tension between efficiency and quality is further complicated by the fact that the error margin is not uniform across the service spectrum. While a minor delay in a transactional query might be tolerable, a factual error in an informational response can erode trust in the entire platform. This asymmetry in risk profiles necessitates a granular approach to automation, where the technology stack is not merely a tool for speed, but a mechanism for risk containment. The shift toward AI-driven self-service, as projected by industry data, is therefore not just about reducing headcount, but about reallocating human cognitive resources to areas where empathy and complex judgment are irreplaceable, while offloading the deterministic and repetitive tasks to systems that can execute them with near-perfect consistency and speed.
Furthermore, the integration of natural language processing and machine learning into these high-volume environments requires a robust feedback loop. The system must continuously learn from the interactions that it fails to resolve or that are flagged by human supervisors. This iterative process ensures that the classification of interactions remains accurate over time, adapting to changes in customer language, product offerings, or regulatory requirements. Without this adaptive capability, the initial efficiency gains would quickly diminish as the system becomes outdated relative to the evolving nature of customer inquiries. Thus, the architecture must be designed not as a static deployment, but as a dynamic ecosystem that evolves with the operational data it processes.
Interaction Classification: Transactional, Informational, and Resolutory
To apply the decision protocol, it is first necessary to categorize interactions into three functional blocks. Transactional interactions involve a specific and deterministic action, such as a password reset, order status check, or payment confirmation. Their logic is binary and does not admit ambiguity.
Informational interactions seek an answer based on a knowledge base, such as a return policy or product specifications. Here, the user's intent may vary, but the response must be factual and verifiable. Resolutory interactions are the most complex: invoice disputes, complaints about poor service, or compensation requests. They require empathy, context, and negotiation capacity, where the cost of an error is high in terms of reputation and economics.
The distinction between these three functional blocks is critical because it dictates the underlying computational requirements and the acceptable level of ambiguity. Transactional interactions, by their nature, are closed systems where the input maps directly to a specific output or action. There is no room for interpretation in a password reset; the system either verifies the identity and executes the reset, or it does not. This binary logic allows for the use of lightweight, deterministic algorithms that can process thousands of requests per second with minimal latency and computational overhead. The primary risk in this category is not hallucination, but rather system availability and the accuracy of the underlying data integrity checks.
In contrast, informational interactions operate in a semi-open space where the user's intent may be phrased in various ways, but the answer must remain strictly within the bounds of the established knowledge base. The challenge here is retrieval precision: ensuring that the system pulls the most relevant and up-to-date information without conflating it with unrelated data. Resolutory interactions, however, exist in a fully open space where the conversation is driven by emotional context, historical data, and the need for negotiation. These interactions cannot be fully automated because they require the ability to interpret nuance, detect frustration, and offer tailored solutions that may involve exceptions to standard policies. The cost of error in this category is not just a failed transaction, but a potential loss of customer loyalty and a reputational hit that can have long-term financial implications.
Typology of Support Interactions
Classification of queries according to their nature and technical complexity.
| Interaction Type | Concrete Example | Nature of Response | Error Cost |
|---|---|---|---|
| Transactional | Password reset | Deterministic action (yes/no) | Low (retry possible) |
| Informational | Return policy | Knowledge extraction | Medium (customer confusion) |
| Resolutory | Invoice dispute | Negotiation and empathy | High (dissatisfaction and churn) |
Decision Protocol: Technical Architecture Assignment
The protocol assigns the most efficient technology to each type of interaction. For transactional tasks, deterministic rules are the optimal option. They are fast, cheap, and do not fail if the logic is well-defined. A traditional rule-based chatbot or an Interactive Voice Response (IVR) system enhanced with AI can manage these flows without the need for complex models.
For informational tasks, a supervised classification model or a Retrieval-Augmented Generation (RAG) system is more suitable. These systems analyze the user's intent and retrieve the correct answer from a knowledge base, reducing the risk of inventing information. For resolutory tasks, generative LLMs or AI agents are necessary to handle the unpredictability of the conversation, but they must operate under strict human supervision.
The assignment of deterministic rules to transactional tasks is based on the principle of computational economy. These rules are essentially hard-coded logic paths that do not require the heavy processing power of neural networks. By using traditional rule-based chatbots or enhanced IVR systems, organizations can ensure that these high-frequency, low-complexity tasks are handled with the lowest possible cost per interaction. This approach also minimizes the risk of unintended consequences, as the behavior of the system is fully predictable and auditable. If a rule is defined, the system will execute it exactly as specified, eliminating the variability that comes with probabilistic models.
For informational tasks, the use of supervised classification or RAG systems introduces a layer of semantic understanding that is necessary to handle the variability in user language. These systems do not generate new information but rather retrieve and present existing knowledge, which significantly reduces the risk of hallucination. The RAG architecture, in particular, allows for the dynamic updating of the knowledge base without the need to retrain the entire model, making it a flexible solution for environments where product specifications or policies change frequently. For resolutory tasks, the deployment of generative LLMs or AI agents is necessary to handle the complexity and unpredictability of the conversation. However, these systems must be constrained by strict guardrails and human oversight to ensure that they do not make commitments or decisions that exceed their authorized scope.
Technology Assignment Flow
Steps to determine the architecture based on the type of query.
- 01Identify the user's main intent (transactional, informational, or resolutory).
- 02If transactional, route to deterministic rules or process automation.
- 03If informational, consult the knowledge base via classification or RAG.
- 04If resolutory, activate a generative LLM with access to context and action tools.
- 05Evaluate the regulatory risk level of the action proposed by the AI.
Break-Even Point Calculation and Error Cost
The decision to automate depends not only on technology but on the economics of error. The break-even point is reached when the cost of human review per ticket exceeds the sum of the AI inference cost and the expected cost of undetected errors. In transactional interactions, the error cost is low, justifying full automation. In resolutory interactions, the cost of an error (customer loss, compensation) is high, requiring human assistance or prior review.
To estimate this point, teams must measure the average cost of human review (agent time per ticket) and compare it with the model's inference cost. If a classification model has 95% accuracy and the cost of reviewing the remaining 5% is lower than the cost of LLM inference for 100% of cases, the hybrid architecture is more efficient.
The economic analysis of automation must go beyond simple cost-per-ticket comparisons and consider the total cost of ownership, including the cost of error management. In transactional interactions, the low cost of error justifies a high degree of automation because the consequences of a mistake are easily reversible. A failed password reset can be retried, and the customer can be guided through the process again without significant friction. However, in resolutory interactions, the cost of an error is often irreversible and can lead to customer churn, regulatory penalties, or reputational damage. Therefore, the break-even point for automation in these areas is much higher, requiring a higher level of human involvement to mitigate risk.
The hybrid architecture model, where a classification model handles the majority of cases and a human or a more complex AI model handles the exceptions, offers a balanced approach. By measuring the accuracy of the classification model and the cost of human review, organizations can optimize the ratio of automated to assisted interactions. If the cost of reviewing the 5% of cases that the model is uncertain about is lower than the cost of running a complex LLM for all cases, the hybrid model is more efficient. This approach allows organizations to leverage the speed and cost-effectiveness of automation for the majority of interactions while maintaining the quality and risk management capabilities of human oversight for the most complex cases.
Regulatory Limits and Human Supervision
The implementation of AI in customer service is subject to the European Union's AI Act. Risk classification does not depend on the technology, but on the purpose and impact. A chatbot that only answers frequently asked questions is limited risk, but a system that evaluates agent performance or automatically decides refunds can be classified as high risk, triggering obligations for competent human supervision and technical documentation.
European Commission guidelines establish that systems intended to monitor or evaluate people's work fall under Annex III high risk. Therefore, human supervision is not optional in certain flows: there must be a designated person with the authority to pause the system and review decisions. Additionally, Article 50 requires that the user knows they are interacting with an AI, a transparency obligation that must be verified in the chatbot configuration.
The regulatory landscape for AI in customer service is evolving rapidly, with the European Union's AI Act setting a new standard for risk classification and compliance. The Act distinguishes between different levels of risk based on the purpose and impact of the AI system, rather than the technology itself. This means that a simple chatbot that answers frequently asked questions is considered a limited risk, while a system that evaluates agent performance or makes automated decisions on refunds is classified as high risk. This distinction has significant implications for how organizations design and deploy their AI systems, as high-risk systems are subject to stricter requirements for human supervision, technical documentation, and risk assessment.
The obligation for human supervision in high-risk flows is not merely a bureaucratic requirement but a critical component of risk management. By designating a person with the authority to pause the system and review decisions, organizations can ensure that the AI operates within acceptable bounds and that any errors or biases are identified and corrected promptly. Additionally, the transparency requirement under Article 50, which mandates that users are informed they are interacting with an AI, is essential for building trust and ensuring compliance. This obligation must be clearly communicated in the user interface and verified in the system configuration to avoid potential legal and reputational risks.
Regulatory Risk Levels in Customer Service
Classification according to the AI Act and associated obligations.
| AI System | Risk Level | Main Obligation |
|---|---|---|
| First-line chatbot | Limited | AI notice to user (Art. 50) |
| Ticket triage and routing | Minimal | Inventory and GDPR compliance |
| Agent evaluation scorecards | High | Human supervision, FRIA, and technical file |
Open questions
- The exact inference cost per token varies by provider and model, so the break-even point must be calculated with the company's internal data.
- The specific application of the AI Act to certain 'agent assist' flows may vary depending on the interpretation of national authorities until the publication of final guidelines.
- The acceptable error rate for a transactional interaction is not standardized and depends on each organization's risk tolerance.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction