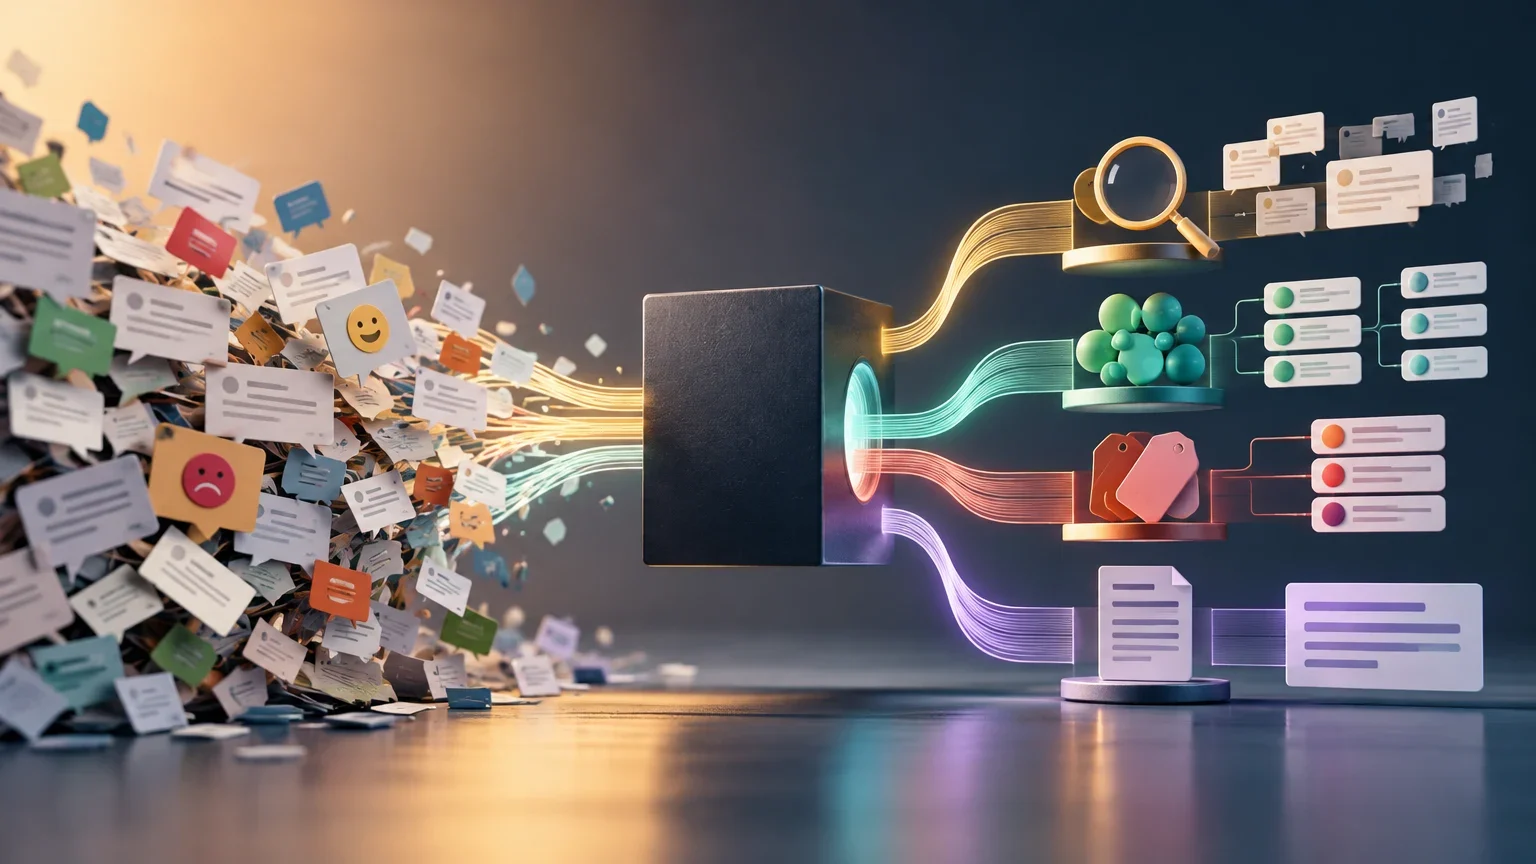
Start by defining the problem: four different tasks
The first step in choosing a customer-feedback analysis method is to pin down what you need to do with the data. Finding a specific comment is not the same as discovering recurring patterns or drafting an executive summary. Treating these as interchangeable can lead to an expensive solution for a simple need—or a basic method that falls short of a more complex one.
There are four common tasks: find relevant comments through search; discover themes through exploratory grouping; measure known categories through classification; and draft a synthesis through assisted generation. Each calls for a different technical approach, with different implications for cost, accuracy, and upkeep. Begin with the result the team needs, not with a tool or model that happens to be available.
How the four feedback-analysis tasks differ
A comparison of each task’s goal, typical input, and expected output.
| Task | Main goal | Typical input | Expected output |
|---|---|---|---|
| Search | Find specific comments | A keyword or semantic query | A list of relevant comments |
| Discovery | Identify themes without predefined labels | An unlabelled text corpus | Groups of similar comments |
| Classification | Assign known categories | Text and a defined taxonomy | Labels for each comment |
| Generation | Draft a synthesis | A full or filtered corpus | A narrative summary |
Understand the corpus and its constraints
Before comparing techniques, take stock of the dataset. Customer feedback is rarely uniform: it may come from surveys, support tickets, public reviews, or social media, with different formats, lengths, and degrees of structure. Keep the source and context attached to each comment; a review and a support ticket may reflect different circumstances and populations.
Key factors include the number of comments, the languages represented, how often new feedback arrives, and whether the data contains personal information. A small, stable corpus may be manageable with straightforward rules. A continuous, multilingual stream may call for a system that can handle varied language and be reviewed or updated as the data changes. These are selection criteria, not proof that one technique will work better in every case.
Compare the technical options by task
For finding comments, literal search may be enough when queries use the same words as the feedback. Semantic search can also retrieve conceptually related comments that use different wording, but it still serves a retrieval task: it does not, by itself, decide which themes matter or assign a reliable category to every comment. Rules are another option when the desired patterns are clear and can be expressed as explicit conditions. They are easy to inspect, but may miss unfamiliar phrasing or cases outside the rules.
For theme discovery, exploratory clustering groups comments by similarity without requiring a set of labels in advance. A person still needs to inspect the groups, decide what they mean, and check whether distinct issues have been merged. Supervised classification is more appropriate when the team has a defined taxonomy and representative examples labelled by people. It can then be evaluated against those labels, though errors still need monitoring. Assisted generation can draft a summary from a selected set of comments, but a polished summary is not evidence that the underlying comments support every statement. Keep the source comments available for verification.
A primary case described by BBVA AI Factory illustrates one possible workflow for a particular setting: multilingual sentence embeddings, fine-tuning with SetFit, dimensionality reduction with UMAP, and clustering with HDBSCAN, followed by keyword extraction to help interpret groups. The organization describes using the system to analyse comments from its own mobile-app questionnaires and support responses to recurring issues. This is an implementation example, not evidence that the same pipeline is preferable for other feedback, organizations, or tasks.
Use a decision matrix to choose an initial approach
Choose an approach by crossing the result you need with the conditions your team can actually meet. If there are no labels and the goal is to explore unfamiliar topics, clustering can be a starting point, provided someone can review and name the groups. If categories are already defined and labelled examples cover the relevant languages, channels, and edge cases, supervised classification is worth evaluating.
Then account for budget, acceptable latency, and review capacity. A system that must process comments immediately has different operational requirements from one that runs in batches. Consider error costs as well: misclassifying a routine compliment is not equivalent to overlooking a potential safety issue. The matrix is a way to structure the decision, not a performance guarantee. Test the candidate approach on feedback representative of the intended use before relying on it.
A simplified decision matrix
Use this as a starting point. Validate the choice against your corpus, error costs, and operational requirements.
| Situation | Possible starting approach | What to check |
|---|---|---|
| No predefined labels; explore what is present | Exploratory clustering | People must interpret the groups and check whether issues have been merged |
| Known categories and representative labelled examples | Supervised classification | Evaluate errors, including on relevant languages and edge cases |
| Need a narrative synthesis | Assisted generation | Check each substantive statement against identifiable source comments |
| Need to find specific comments | Literal or semantic search | Check whether retrieval is relevant and whether important comments are missed |
| Clear, stable patterns that can be expressed as conditions | Rules | Check how the rules handle new wording and cases outside the defined conditions |
Account for consequential errors and operational checks
The most costly errors are not always the most obvious. Missing a critical signal, such as a possible safety concern, can matter more than mislabelling a low-impact compliment. A wrong label might send feedback to the wrong team or prompt an unsuitable response. A synthesis that makes claims not supported by identifiable comments can undermine trust in both the analysis and the decisions based on it.
Before implementation, check that each label, theme, or substantive claim in a synthesis can be traced back to source comments. Define how staff can correct a mistake and how ambiguous or high-impact cases are routed for human review. Also decide what happens when the system cannot assign a category confidently: an explicit “unclassified” outcome may be safer than forcing every comment into an incomplete taxonomy. Traceability and auditability matter alongside measured accuracy.
Finally, make sure the proposed workflow fits the real constraints: authorized access, data handling and retention, the frequency of new feedback, integration needs, operating budget, and the time available for review. A method that looks suitable in a demonstration may not be practical if the team cannot check its outputs or maintain its labels and rules.
Checks to complete before implementation
A short validation process for checking whether the chosen approach fits the team’s actual task and constraints.
- 01Define the primary task: retrieval, theme discovery, classification, or synthesis.
- 02Audit the corpus for volume, languages, structure, sources, and personal information.
- 03Check whether predefined labels and representative labelled examples are available.
- 04Assess error costs, budget, acceptable latency, and capacity for human review.
- 05Confirm authorized access and appropriate data handling and retention.
- 06Require traceability from outputs to source comments, plus a process for corrections and escalation.
Worked scenarios and questions to ask before deciding
Suppose a product team needs to find every comment mentioning trouble with a payment screen. If the wording is predictable and the corpus is small, a literal query or a clear rule may be sufficient. If customers describe the same problem in many different ways, semantic search may be worth testing. In either case, check a sample of results for relevant comments that were missed and unrelated comments that were returned.
Now suppose the team wants to understand themes it did not define in advance. Exploratory clustering could help surface groups to investigate, but the output needs human interpretation. If the team instead needs a weekly count for established categories—such as payment problems, delivery questions, and feature requests—supervised classification may be worth evaluating when suitable labelled examples exist. For a short report to help colleagues review a large batch of comments, generation can provide a draft, but the claims should remain traceable to the comments and should not replace review of important or ambiguous cases.
Before choosing, ask: Is the primary need to retrieve specific comments, apply known labels, explore unknown themes, or draft a synthesis? Are the available labels and examples representative of the languages, channels, and edge cases in the corpus? Which is more costly here: missing a signal, assigning the wrong category, or producing a summary that cannot be verified? What processing and retention are authorized for the data? Can the team inspect, trace, and correct the outputs? The answers determine whether filters, rules, search, classification, clustering, or assisted generation are a reasonable place to start.
The practical takeaway
There is no single best method for every feedback task. Search finds comments; rules apply explicit conditions; clustering helps explore patterns without predefined categories; supervised classification assigns known labels; and generation drafts a narrative synthesis. Their outputs serve different purposes, so compare them against the result you need rather than treating them as interchangeable forms of “AI analysis.”
Start with the simplest approach that can meet the requirement, then test it on representative data and the errors that matter most. Keep outputs linked to their source comments, provide a route for correction and human review, and revisit the choice when the corpus, taxonomy, or operating requirements change. The aim is not to produce more labels or longer summaries. It is to support decisions with evidence the team can inspect and act on.
Open questions
- The available evidence does not provide independent, like-for-like comparisons of cost or performance for search, rules, classification, clustering, and generation on the same customer-feedback corpus.
- The BBVA AI Factory account describes one organization’s system and application; it does not establish that its pipeline will perform similarly in other settings.
- The quality of a generated synthesis depends on the input, instructions, and verification process; the available evidence does not establish a universal accuracy measure.
- The operational effect of latency on customer outcomes varies by use case and is not quantified in the available evidence.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction