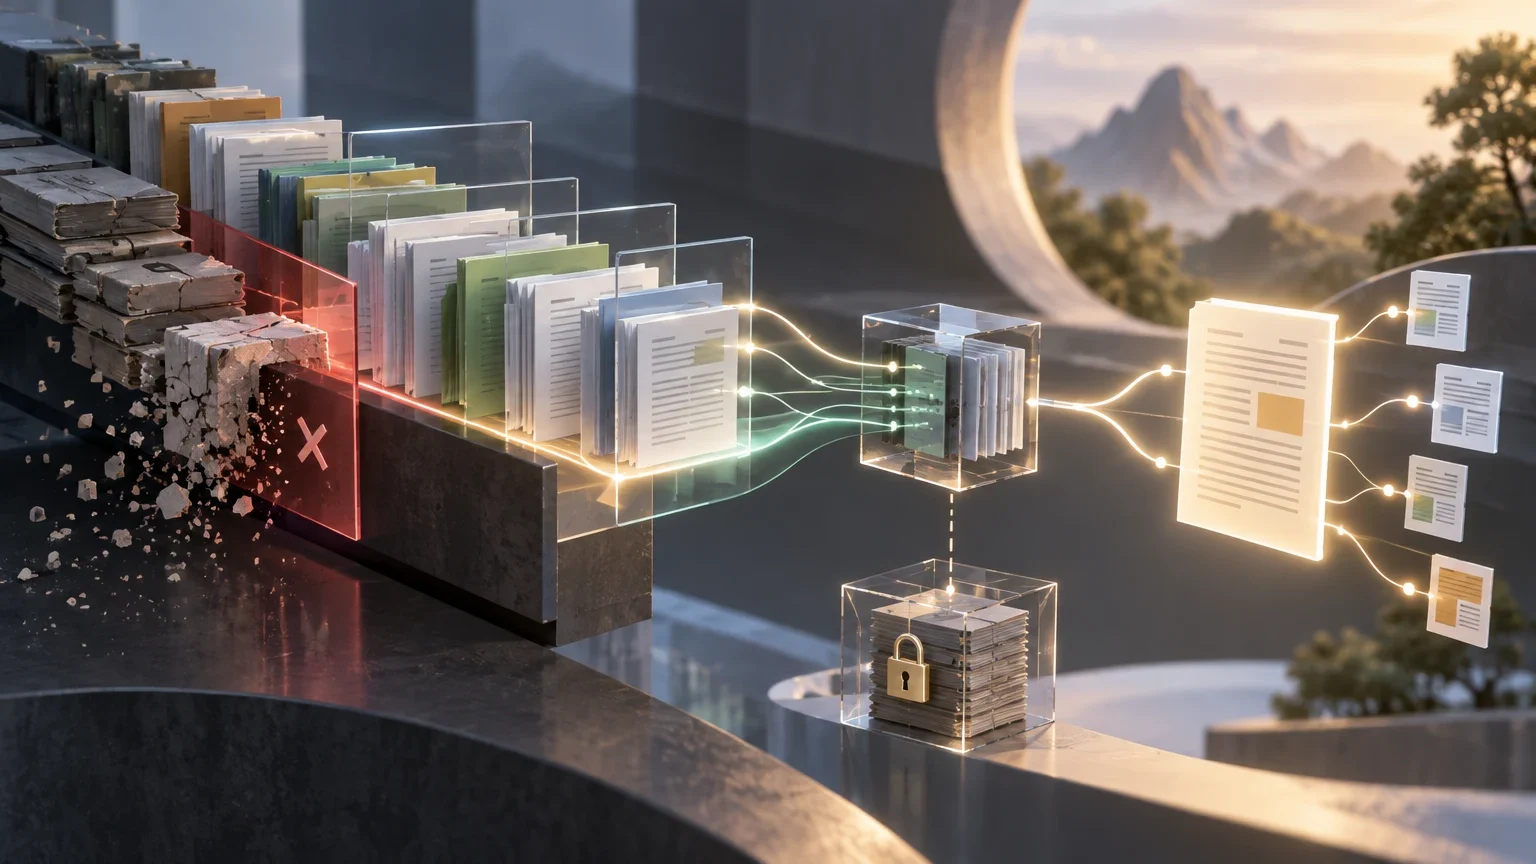
The problem: a citation can be accurate and still be useless
A retrieval-augmented generation system, or RAG system, is often evaluated by asking whether it retrieves relevant text and whether the answer is grounded in that text. That control is necessary, but it is not enough when the corpus changes. An answer may accurately reproduce a passage from a cancelled policy, a superseded manual, or a contract that no longer applies to the person asking. In that case, the failure is not necessarily in generation: it is in the lifecycle of the evidence.
It is useful to separate two questions. The first is semantic: does the retrieved passage answer the query? The second is a governance question: was it an authorized, accessible, and effective source for this query at this point in time? Vector similarity alone does not answer the second question. An older text may appear more similar to the question than a newer revision; a local copy may contain instructions that differ from a central policy; and a passage indexed while a person had access may continue to appear after that permission has been revoked.
The operational thesis is simple: adding files to an index does not create a maintainable knowledge base. Doing so requires a stable identity for the document, an identifiable revision, an effective-date interval, an authority rule, access controls applied during retrieval, and a record linking each answer to the evidence actually consulted. It also requires explicit retirement: no longer publishing a file at the source does not ensure that it disappears from indexes, replicas, caches, or derived records.
This guide treats the corpus as a system of records subject to change, rather than as a folder of files. The goal is not to promise infallible answers. It is to be able to demonstrate why evidence was eligible, detect when it ceased to be eligible, and abstain when the available rules do not determine which of several active sources should prevail.
Separate identity, revision, effective status, authority, and access
Identity answers which documentary object is being managed. It must remain stable even if the title, location, or format changes. For example, a corporate policy may retain its canonical identifier when it moves from an office document to a web page. Revision answers which specific edition contains the text. An editorial correction and a policy replacement may create different revisions, even when the change appears small.
Effective status expresses when a revision may be used as evidence. It must not be confused with the indexing date or the file's technical modification date. A policy published today may take effect next month; another may be retained only for historical queries. It is therefore useful to store, at minimum, an effective start, an effective end when one exists, and an operational status such as draft, approved, active, retired, or exceptionally restored.
Authority ranks sources that can address the same subject. An approved global policy may take precedence over local guidance, unless a valid exception exists for a jurisdiction, business unit, or product. This rule cannot reliably be inferred from wording or similarity. It must be a governed attribute, with an owner and an explicit precedence rule. If two active sources contradict each other and no applicable rule exists, the prudent behavior is not to choose one based on popularity or semantic proximity.
Access permission is another independent dimension. A passage does not stop containing protected information because it has been split, vectorized, or stored in an index. Authorization filters must be applied before results are ranked by relevance, and they must be updated when access control lists change. Search-service documentation confirms that document-level security can restrict which documents in an index a person can see, and that permission changes require affected documents to remain synchronized.
This design aligns with a basic provenance idea: distinguish entities, activities, and agents. The canonical document, its revision, and every passage are entities; extraction, chunking, embedding creation, and indexing are activities; and the owner, approver, and service running a process are agents. Modeling these relationships does not require adopting a particular technology, but it prevents traceability from becoming free-form notes that are difficult to query.
Minimum decision before retrieving a passage
| Dimension | Operational question | Treatment if missing or failing |
|---|---|---|
| Identity | Is the passage linked to a canonical document? | Exclude it from evidence-backed answers. |
| Revision | Is the exact edition that produced the passage known? | Exclude it or mark it for corpus repair. |
| Effective status | Was the revision active at the time of the query? | Filter it out before calculating similarity. |
| Authority | Is there a precedence rule for its scope? | Escalate the conflict or abstain. |
| Access | Does the person still have permission to see the document? | Do not return the passage or use it in generation. |
A minimum data model for a governed corpus
A minimum model does not need to capture every possible metadata field, but it must capture the fields that make it possible to decide eligibility and reconstruct facts. The canonical document entity can include an immutable identifier, document type, scope, accountable owner, source of origin, and classification. The revision entity should have its own identifier, a fingerprint of the received content, approval status, effective start and end, known publication date, and a relationship to the preceding or superseded revision.
Every retrievable passage must carry the identifiers of its canonical document and revision, a stable position or range within the revision, a fingerprint of its normalized text, and the attributes needed for filtering. An embedding is not the passage: it is a derived representation. It therefore needs its own model identifier, configuration version, calculation date, and reference to the exact passage that produced it. The index is also an operational entity: record its version, partition or replica, search configuration, publication time, and included set of revisions.
Add explicit relationships for supersedes, derives from, merges, and retires. A document merge does not necessarily equal a one-to-one replacement: several documents may be absorbed into a new source, while part of the information may have no successor. This distinction makes it possible to answer whether a document was retired, what its successor is when one exists, and whether a historical query should still be able to find it under specific controls.
Time fields deserve particular discipline. Store the time observed at the source, the approval time, the business effective-date interval, the extraction time, and the index publication time. Do not assume they are interchangeable. To reconstruct an answer, it matters to know what was known and what was operationally available, in addition to what text claimed to be effective. When clocks across systems are not synchronized or a date comes from unreliable metadata, record that uncertainty rather than turning it into artificial certainty.
Entities and fields worth retaining
| Entity | Minimum fields | Purpose |
|---|---|---|
| Canonical document | Stable ID, owner, scope, classification, authority | Identify the governed object. |
| Revision | ID, fingerprint, status, effective dates, successor or predecessor | Determine which edition may be used. |
| Passage | ID, revision, range, text fingerprint, filter metadata | Retrieve traceable evidence. |
| Embedding | ID, passage, model, configuration, date | Distinguish the derived representation from the text. |
| Index publication | ID, configuration, included set, publication time | Reconstruct the search environment. |
| Answer event | query, filters, candidates, index version, time | Explain the evidence available and selected. |
Change workflows: updating is not a single operation
Initial onboarding begins by validating the source, identity, owner, classification, and access rules. Content is then extracted, a revision is created, it is chunked, representations are calculated, and an index version is published. Publication should be atomic from the query perspective or, at minimum, prevent states in which part of a revision is visible and another part is not. If approvals are required, a draft can be technically processed without being eligible to answer questions.
A minor correction requires comparing the new fingerprint with the preceding revision and locating the segments that changed. Recalculating only the affected passages can reduce work, but only if the chunking algorithm maintains correct references. If a modification shifts headings, numbering, or sections, it can affect more passages than a literal comparison indicates. Optimization must be subordinate to traceability: it is preferable to reindex more content than to preserve ambiguous links between an embedding and text.
Replacing a policy is a governance event. It must create a successor revision or document, set the effective date, close the prior version's effective period where appropriate, and propagate retirement to every derived artifact. In some indexing systems, documents no longer present at the source can require an explicit deletion action; therefore, a rerun must not be assumed to prove complete retirement. Verification must inspect the state of indexes and replicas, not just the source record.
A full retirement retains, if the retention policy permits it, a history that is ineligible for ordinary answers. History may be needed for auditing, incident investigation, or reconstructing a past answer. It must remain separate from active indexes, with access controls and a defined purpose. Restoring a retired source is exceptional: it should create a new event, justify the status change, and trigger a new verifiable publication rather than erasing the trail of the previous retirement.
Source replacement process
- 01Record the incoming revision, its owner, its authority, and its planned effective date.
- 02Compare content and metadata with the active revision; identify affected passages and succession relationships.
- 03Approve or reject the new revision through the applicable document workflow.
- 04Create or update passages and embeddings; publish an identifiable index version.
- 05Mark the preceding revision as superseded or retired on the defined date, and remove it from retrieval eligibility.
- 06Invalidate stored retrieval results and answers that depend on the preceding revision.
- 07Run query, permission, replica, and cache tests; retain the deployment result.
Reindexing, caches, and duplicates: maintaining consistency across representations
Selective reindexing is useful when the relationship between every representation and its input can be demonstrated. Calculate differences in text and metadata. A content change requires reviewing affected passages and embeddings. A change in effective status, authority, jurisdiction, or permission may not alter the text, but it does alter retrieval eligibility; filters, metadata indexes, and caches must therefore be updated. Treating only textual changes leaves a path to incorrect answers using literally unchanged content.
Not all caches store the same thing. There may be caches for source downloads, processed passages, embeddings, retrieval results, and final answers. Each needs a key that incorporates relevant dependencies, such as the index version, source revision, the person's identity or access group, jurisdiction, and the query date when answering questions about effective status. Reusing an answer without these dimensions can disclose content or resurrect a retired policy.
Web-cache principles distinguish freshness, validation, and invalidation, and establish that requests changing resource state must invalidate applicable stored representations. In a RAG corpus, the specific mechanism may differ, but the principle transfers: when a source or its eligibility changes, the derived representations that could continue serving the prior version must be located and removed or invalidated.
Semantic duplicates require an explicit policy. Two passages may express the same rule while belonging to different revisions; returning both can artificially increase the model's confidence. Group candidates by canonical document or revision relationship before generating the answer. Grouping must not conceal conflicts: if two active, equally authoritative sources disagree, retain the conflict as a signal to abstain or request human review.
Retrieve with time, authority, and permissions before ranking by similarity
The retrieval query must be constructed as a sequence of constraints and ranking, not as vector search followed by an optional check. First determine the context: the requester's identity, effective permissions, product, jurisdiction, audience, relevant date, and any need to consult history. Then filter out revisions and passages that do not meet that context. Only eligible candidates should proceed to similarity calculation, lexical search, or a combination of both.
The relevant date deserves a visible product decision. For questions about the current rule, use the query time. For questions such as, “Which policy applied when I signed?”, request or cautiously infer a reference date and search the authorized history. If the date is unknown, do not present a historical reconstruction as if it were current. It is better to ask for the information, show the time scope of the evidence, or limit the answer to what can be justified.
Authority can be implemented as a score, but it should not always be reduced to a number. Some rules are hard constraints: a mandatory rule for a jurisdiction may exclude general guidance. Others may be preferential and allow coexistence. Document the rules, their owner, and their exceptions. The generative system should not invent a hierarchy from the tone of the documents.
Before drafting, retain the list of filtered candidates, the reasons for exclusion, the index configuration, and the passages ultimately used. The record must distinguish retrieved evidence from evidence cited in the answer. It must also record the query time and the version of the filtering rules. Without those data, a later investigation may find the current document but be unable to demonstrate which corpus produced the original result.
Recommended order for an evidence-based query
- 01Resolve the user's identity, permissions, and context.
- 02Set the reference date and scope of the query.
- 03Exclude documents or revisions that are retired, expired, future-dated, unauthorized, or out of scope.
- 04Apply authority, jurisdiction, product, and audience rules.
- 05Search and rank only within the eligible set.
- 06Group related revisions and detect unresolved conflicts.
- 07Generate an answer limited to the selected evidence, or abstain.
- 08Record candidates, exclusions, index, rules, and query time.
Regression tests, stop criteria, and responsibilities
Tests must evaluate system behavior under change, not only retrieval quality over a stable set. Build cases with a retired policy that retains greater similarity than its replacement, a passage removed from a revision, an approved policy with a future effective date, a local copy that contradicts a central source, and a permission revoked after indexing. Each case must declare which documents are eligible, which one should win when an authority rule exists, and when abstention is the correct output.
Also test time propagation. Measure the interval between approval of a retirement and its effective exclusion from relevant indexes, replicas, and caches. Testing the main index alone is not enough: a previously generated answer may be stored in another layer. Define different time objectives according to source risk. A security policy or document containing sensitive data may require faster invalidation than an internal editorial guide.
Set clear stop criteria. Block an answer when the link between passage and revision is missing, when permissions cannot be evaluated, when the source has no owner, or when an active conflict has no precedence rule. Display the update date when it helps interpret the answer, but do not use it to conceal uncertainty. Route to human review when potentially relevant evidence exists but the system cannot order it using explicit rules.
Responsibilities must be separated, even though one person may cover multiple roles in small teams. The source owner is responsible for content and its effective-status lifecycle. The indexing owner is responsible for extraction, publication, and technical invalidation. The effective-status approver decides when a revision is usable. The incident owner coordinates urgent retirement, exposure assessment, and communication. The product team defines how abstention is expressed and how additional context is requested from the user.
As a next step, turn this model into a list of verifiable controls and connect it to the learning-center guides on assistant evaluation, comparing retrieval approaches, and discovering sources. Implementation will depend on the architecture, but the success criterion remains the same: for every relevant answer, the team must be able to explain what evidence could be used, what was used, why it was authorized, and what would have prevented an answer.
Minimum regression test suite
| Case | Expected result | Test evidence |
|---|---|---|
| Superseded document | The newer revision prevails even if the older one is more similar. | Log of filters, candidates, and selected revision. |
| Retired passage | It does not appear in retrieval or in a stored answer. | Index query and cache-invalidation check. |
| Future effective date | It is not used for a question about the current rule. | Reference date and exclusion reason. |
| Local and central conflict | The authority rule is applied or the system abstains. | Evaluated rule and resulting decision. |
| Revoked permission | The passage is no longer visible to the affected identity. | Test with authorized and unauthorized identities. |
| Historical reconstruction | The set of evidence available at that time is reproduced. | Index version, query clock, and answer record. |
Open questions
- The exact way to represent permissions, effective status, and authority rules depends on the document repository, search engine, and regulatory requirements of each organization.
- Selective reindexing is safe only if the system can demonstrate which passages and representations derive from each revision; otherwise, it may be necessary to reindex a larger set.
- Historical reconstruction may be constrained by the retention policy, preservation of index versions, and availability of audit logs.
- Provider documents describe capabilities and behaviors of specific products; they do not prove that every RAG architecture has the same guarantees without its own implementation and testing.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction