What Quine is and the problem it aims to address
Microsoft Research has introduced Quine, an experimental initiative intended to help explore biological questions by connecting information that is often analyzed separately. The project combines a multimodal biology model with an interactive system that links it to scientific tools, research literature, and research teams. Its stated aim is to represent aspects of biological systems, anticipate possible responses to interventions, and help determine which hypotheses are most worth testing first.
The proposal starts from a practical constraint: biological experiments take time and resources, and many questions involve too many possible combinations to investigate exclusively in the laboratory. Quine is intended to use computation to explore a broad space of possibilities and narrow it to prioritized candidates. That does not turn a prediction into a finding. In principle, the model helps guide research; experimental evidence is still needed to test whether a hypothesis holds up.
The initiative is described as an early step toward a long-term vision, not as an established scientific tool. Microsoft Research also cautions that Quine is experimental, that its outputs may be incomplete or inaccurate, and that it is not intended for clinical or medical use. The announcement therefore combines a proposed architecture with initial results reported by the team itself; it is not an independent demonstration of broad utility.
Connecting biological modalities and scales
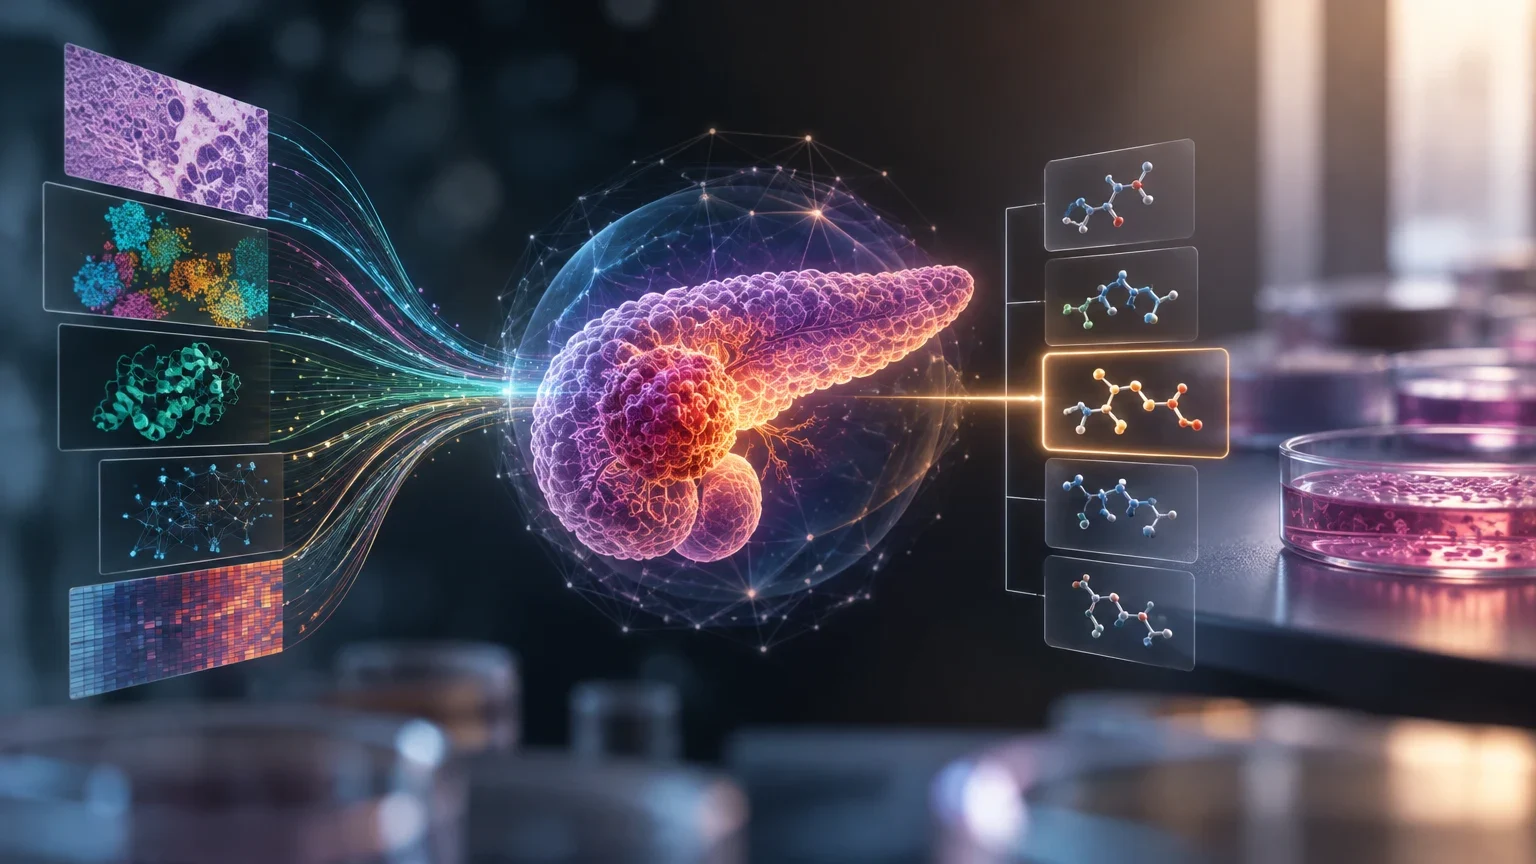
The model, as described, learns shared representations across different biological modalities and scales. The information types listed by Microsoft Research include biological sequence, structure and function, cellular state, and imaging; the description also mentions genomics, proteins, chemistry, RNA, cell state, and bioimaging. The intent is for a signal observed in one type of data to help inform a prediction about another, rather than treating each dataset as an isolated domain.
Scale matters because biological phenomena are related from molecules and cells through to tissues. The project aims to combine these levels to model how a change or intervention might be associated with other effects. In practical terms, a question about a cell’s state could benefit from molecular information or the results of earlier experiments. However, an architecture designed to connect modalities does not automatically prove that it can do so accurately, or that the relationships it learns are causal.
The second component, which the team calls an interactive harness, connects the model to scientific tools, literature, and researchers. The idea is to organize a working sequence: pose a question, generate proposals, select experimental designs, measure outcomes, and use those measurements to guide new questions. The public description sets out this approach but does not provide a complete external evaluation that would allow its performance to be compared with specialist models, conventional methods, or expert decisions.
What each component is intended to do
| Component | Stated role | What it does not establish on its own |
|---|---|---|
| Multimodal model | Learn connected representations across different data types and biological scales. | That predictions will be accurate in a new context or identify causation. |
| Interactive harness | Connect the model with tools, literature, and research workflows. | That every tool is comprehensively integrated or that the process outperforms alternatives. |
| Experiments | Test candidates and return measurements that may guide the next round. | That reported results will generalize to other labs, organisms, or patients. |
From computation to experiment: the pancreatic cancer example
Microsoft Research describes a research case involving pancreatic ductal adenocarcinoma, a form of pancreatic cancer. In collaboration with researchers at the Broad Institute of Harvard and MIT, the team explored whether cellular state, in addition to genetics, might be related to tumor response to drugs. According to the publication, Quine was used to prioritize thousands of compounds based on their potential to shift tumor cells between states considered relevant to treatment.
The team reports that its highest-ranked compounds produced the largest intended changes in laboratory assays focused on a transition from a cellular state called classical to one called basal. It also reports weaker effects in the reverse transition and says that some compounds were associated with a third phenotype, which the team says was consistent with a system prediction. These are results reported by the project’s authors; the available information does not establish independent replication or show that the compounds are effective treatments.
Microsoft Research says the initial prioritization was completed over one weekend and that the process could save months of experimental work. That timeframe refers to the prioritization workflow described; it does not show that the entire research, validation, and treatment-development cycle was shortened to that period. The publication presents the case as an early test of how the system might narrow candidate options before laboratory work, not as clinical evidence.
The example illustrates a role in supporting experimental decisions: choosing which candidates to test. The relevant evidence is not simply that the model generates a list, but how the candidates perform when measured and whether the selection improves reproducibly against a clear benchmark. The public description reports promising results attributed to the team, but does not, on its own, provide all the metrics, comparators, and data needed to judge that improvement independently.
What it means for the project to be at an early stage
The announcement describes Quine as an early-stage research effort. Initial access is intended to be limited to the Quine Fellows program and selected research collaborations. Microsoft says it expects to broaden access as the technology matures, but that expansion is a future expectation, not confirmed general availability.
The early stage also affects how the design should be interpreted. The team acknowledges that the model will not represent biology perfectly and frames the goal as being useful enough to inform experimental design. That aspiration is not a guarantee of accuracy: each prediction may depend on the type and quality of the data, the biological system being studied, and the experimental conditions.
The use warning is explicit: Quine is experimental research technology, not for clinical or medical use. Its outputs may be incomplete or inaccurate and require review by qualified researchers and appropriate scientific and experimental validation. This rules out presenting it as a tool for making diagnostic, treatment, or clinical-care decisions.
How a Quine prediction should be treated
- 01Pose a specific biological question and define what observation could answer it.
- 02Use the system to generate or prioritize hypotheses, while making its limitations explicit.
- 03Design assays that can test the predictions with appropriate controls.
- 04Measure the results and review whether they support, contradict, or change the hypothesis.
- 05Repeat and cross-check the process before claiming that the result generalizes.
What is still needed to assess its scientific value
The public description reviewed does not include a separate technical paper with full details of the architecture, training, and evaluation. Although it lists the modalities and the system’s general purpose, questions remain about which data were used, how they were harmonized, what quality controls were applied, and which parts of the workflow produce each prediction. Without those details, it is difficult to reproduce the work or determine which component accounts for the reported results.
It is also important to know precisely how Quine’s prioritization was compared with benchmarks: random selection, specialist models, existing computational procedures, or expert judgment. To assess improvement, researchers would need access to metrics defined before the experiments, sample sizes, controls, statistical uncertainty, and results for candidates that did not work, as well as the highlighted examples.
Generalization remains another open question. A result from cell lines in one specific experimental context does not, by itself, establish that the system works for other cancers, organisms, laboratories, or conditions. Prospective evaluations and independent replications would be useful, with a clear separation between data used to train the system or select candidates and data used to test its performance.
For now, the most supportable reading is limited: Quine presents a strategy for connecting biological data and ranking hypotheses, and Microsoft Research reports initial compound-prioritization experiments in pancreatic cancer. The public evidence provided is not enough to independently measure how much it improves on alternatives, how well it generalizes, or whether its results lead to clinical benefit. Those questions require technical documentation and further validation.
Open questions and evidence that could address them
| Question | Evidence that would help assess it |
|---|---|
| Does it outperform existing methods? | Prospective comparisons using defined benchmarks and published metrics. |
| Can the result be reproduced? | Protocols, data, and independent replications at different laboratories. |
| Does it generalize across contexts? | Tests in biological systems, organisms, and experiment types not used to develop the system. |
| How uncertain are its predictions? | Calibrated estimates, error analyses, and complete results, including negative findings. |
| Does it have clinical relevance? | Appropriate clinical evidence; the described cell assays are not enough to establish it. |
Bottom line: a tool to guide science, not replace it
Quine aims to address a real challenge in biological research: linking different kinds and levels of data to explore more hypotheses than would be practical to test directly. Its combination of a multimodal model and a tool-connected system is intended to create a loop between predictions, experimental decisions, and new measurements.
The pancreatic cancer case is an initial application described by the team, with prioritized candidates and laboratory results reported by Microsoft Research. But the project remains at an early stage, and the available information does not yet demonstrate a general advantage over benchmark methods or a clinical application. Assessing its value will require reproducible data, transparent comparisons, and independent validation.
For readers, the key distinction is between a proposed capability and demonstrated utility. Quine may help decide which hypotheses to examine; experiments, replication, and scientific review determine which conclusions can be supported.
Open questions
- A separate technical paper with complete details of the architecture, training, and evaluation has not been verified.
- The laboratory results on compounds and cellular states come from the project team’s description; independent replication is not established here.
- A complete public comparison with computational methods, expert selection, or other benchmarks is not available.
- The reported case does not establish generalization to other cancers, organisms, biological scales, or laboratories.
- The reported one-weekend timeframe concerns prioritization; it does not show that the full scientific or therapeutic process was reduced to that period.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction