What Liquid AI has announced
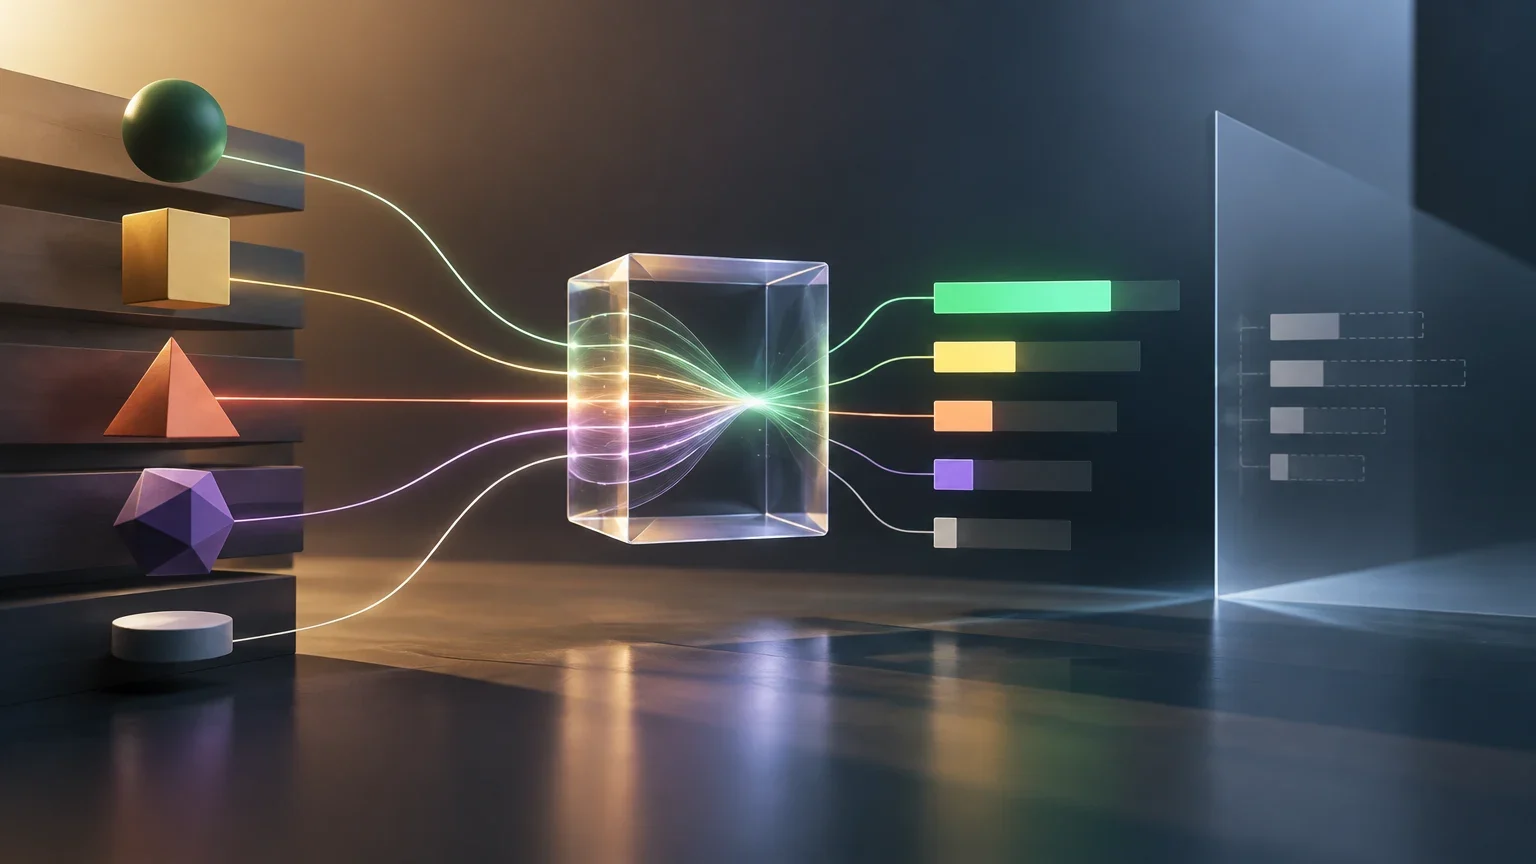
Liquid AI presents d1 as a decision model: rather than drafting an open-ended response, it evaluates an input and returns structured results for a bounded decision. Its documentation describes three offerings in the family: d1-3B, a multimodal text-and-image model; d1-omni-600M, which accepts text, images or audio; and d1Hosted, available through the Liquid AI API.
The company proposes this type of model for classification, prioritisation, moderation, request routing and other tasks with predefined outcomes. The distinction is practical: if a system needs to choose a label or assign a score, it can return a bounded, structured result; if it needs to explain, summarise or write, it needs generative capability. The documentation explicitly lists those open-ended generation tasks as uses for a language model.
Availability described in the documentation does not mean every modality, interface or model is available in every environment. Before integrating d1, check the specific model, accepted inputs, API and current terms. The company’s announcement also presents its comparison results with Jev as its own claims; those results should be treated as vendor claims, not as independent validation.
How it expresses decisions
The documentation groups queries into three primitives. Choice selects among categories with no inherent order and returns a probability distribution over the named alternatives. Score places an answer on an ordered scale, such as a severity rubric. Noul poses a binary question and returns a probability between 0 and 1—for example, the probability that a message is spam.
This makes it possible to distinguish between choosing the most likely option and seeing how much uncertainty remains between alternatives. If a system assigns similar probabilities to two departments, it can route the case for review rather than treating the winning label as certain. But a probabilistic output does not, by itself, show that the probabilities are well calibrated: that property has to be measured on representative data.
Liquid AI says d1 does not generate response tokens and produces a decision in a single call. The phrase “zero generated tokens” describes how the provider says the output is produced; by itself, it does not specify every billing component, such as input handling, API pricing or infrastructure costs. Nor does it establish that a task will always be faster or cheaper than with a generative model.
Where it could fit in a business
The proposal is most relevant when possible answers are bounded and the decision is repeated frequently. Uses listed by Liquid AI include message classification, ticket routing, moderation, urgency assessment, binary safety checks and approval of tool calls. For visual inputs, the company mentions image inspection and classification; for audio, intent detection and voice-command routing with the model that supports that modality.
One operational example is request triage: the system assigns probabilities to known categories and sends ambiguous cases to a person. Another is a gate that checks whether an extracted result meets a requirement before accepting it. In both cases, usefulness depends on whether the option set reflects real-world cases and whether there is a safe path for new, incomplete or out-of-distribution inputs.
D1 does not automatically replace an LLM. The documentation itself recommends generation for free-form writing, conversation, summarisation, code, open-ended questions and complex multi-step reasoning. An architecture can combine both approaches: use a decision model for a bounded classification, then turn to a generative model or a person when an explanation or open-ended answer is needed.
Choosing between structured decisions and generation
| Need | Approach that may fit | What to check |
|---|---|---|
| Assign a request to a fixed category | Decision model, such as Choice | Category coverage, ambiguous cases, and an abstention or review option |
| Score severity against a defined scale | Decision model, such as Score | A consistent scale definition and agreement with human evaluators |
| Write an explanation or summarise a case | Generative model | Text quality, faithfulness to the input and safety controls |
| Answer an open-ended question or hold a conversation | Generative model | Reasoning required, context and need for follow-up |
| Approve or reject an action using binary criteria | Decision model, such as Noul | Costs of false positives and false negatives, threshold and oversight |
What is missing to assess the comparison with Jev
Liquid AI says d1 outperforms Jev on the Hugging Face Decision Index and also highlights results on multilingual evaluations, long inputs and resistance to prompt injection. The existence of a manufacturer’s claim does not make it independently verified fact. Interpreting the result requires the exact benchmark version, its tasks, evaluation data, protocol, models compared and execution conditions.
It is also important to distinguish an aggregate score from task-level results. An index that combines different types of evaluation can inform a comparison, but it does not, by itself, predict how a system will perform on invoice classification, message moderation or ticket routing at a particular company. Performance can vary with language, input length, label design and the frequency of exceptional cases.
The sources provided do not establish an independent comparison of accuracy, calibration, latency and cost against Jev or generative models under equivalent conditions. To repeat the claim that d1 “outperforms” Jev rigorously, the compared versions, test set and methodology would need to be documented, and the result shown to be reproducible beyond the provider’s announced evaluation.
A minimum test before choosing a model
Evaluate a representative task and compare alternatives under the same protocol.
- 01Define the decision, valid options and cost of making an error.
- 02Prepare a test set separate from examples used to tune instructions or thresholds.
- 03Include languages, long inputs, formatting errors and cases that do not fit any category.
- 04Measure per-class quality, probability calibration and the rate of referral for human review.
- 05Compare latency and total cost with a generative alternative on the same infrastructure and at the same volume.
- 06Repeat the evaluation when data, configuration, model version or service conditions change.
Limits and practical criteria
Probabilities are useful only if they reasonably reflect the frequency of correct outcomes for the task at hand. A high score should not automatically be treated as a guarantee, and a decision threshold can have different consequences depending on the error: in moderation, for example, a false alarm and harmful content slipping through do not carry the same cost. Calibration and thresholds should be checked using relevant data and reviewed when inputs change.
It is also worth testing how the model behaves with irrelevant information, malicious instructions, unknown categories and incomplete inputs. The company’s claim of greater resistance to prompt injection does not remove the need for your own security testing. For sensitive tasks, human review, limits on what the system can do and a way to escalate uncertain cases are sensible safeguards.
As a rule of thumb, d1 is worth testing when the expected result fits a defined structure and can be evaluated using representative examples. A generative LLM is a better fit when the task requires writing or an open-ended answer. If a process needs both, a hybrid pipeline can be tested and its overall quality, latency and cost compared before changing a production system.
Open questions
- The available evidence does not independently confirm the performance comparison with Jev or all of its conditions.
- The sources provided do not establish comparable accuracy, calibration, latency and cost results for real business tasks.
- It is unclear whether “zero generated tokens” implies any specific difference in billing; this should be checked against the API terms.
- Availability, modalities and interfaces may vary by model and environment; confirm current status before integrating.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction