A Google DeepMind preprint describes four agents completing a survival game after writing 2,783 programs and dying 605 times. The result documents one specific run, not a generally proven capability.
V4.1-Flash-1017 improves on DeepSeek’s reported results for agentic tasks and lowers the observed cost per task in its DeepSWE evaluation. The company has also made Search and Fetch available through APIs; performance comparisons for the new checkpoint are, for now, internal evaluations.
The company has granted six researchers from the non-profit organization METR permissions equivalent to its own employees, marking a precedent in external verification of AI risks.
An interpretability study traces how attention and MLP layers contribute to detecting harmful requests and generating refusal signals in language models.
A new preprint presents a 20-task benchmark designed to measure the ability of coding agents to resolve faults in deployed applications, overcoming the limitations of traditional test repositories.
A preprint introduces a method that connects a speech encoder to a frozen LLM to answer closed-set questions via probability distributions over options, reducing latency in real-time voice agents.
Muse Spark Open is attributed with 816 billion parameters, 42 billion active parameters, and a one-million-token context window. However, the available primary documentation from Meta does not confirm this variant or official Apple Silicon optimization; local hardware requirements and performance also remain unverified.
Nemotron 3.5 Super VL is designed to interpret documents, charts, images, and video while supporting long-running tasks with tools. Available information confirms the launch and model scale, but it is insufficient to establish independent performance or the specific NVIDIA hardware required for each deployment.
An experimental paper describes a way to stabilize looped Transformers and measure their performance. It does not show that OpenAI uses this approach in its next model, nor does it establish that the architecture makes safety oversight harder.
The new model combines reasoning, tool use, and understanding of text, images, documents, and video. NVIDIA says it activates 12 billion parameters per token and offers efficiency improvements, but the published results are not enough to establish an independent comparison or a universal inference cost.
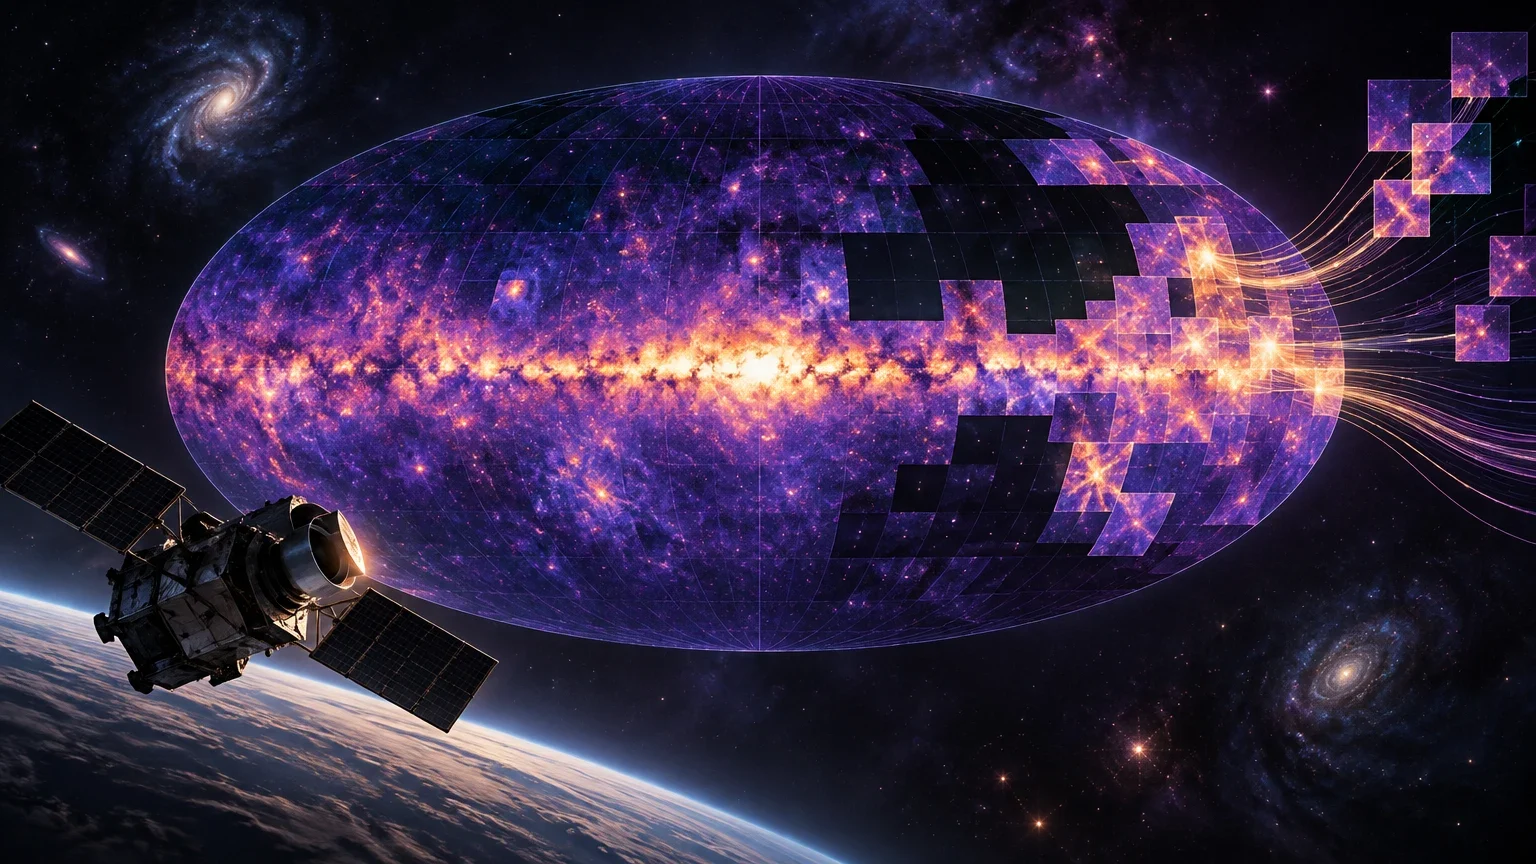
A Johns Hopkins astrophysicist used Claude Science to process space mission data and fill gaps in the sky's ultraviolet map, combining observations with statistical estimates validated by data-hiding tests.
Meta has launched Muse Wonder and Muse Wonder Full, its first frontier models, available via API and subscription. We analyze the announced capabilities, pricing, and the limitations of performance comparisons against OpenAI and Anthropic.