One-sentence definition
Diseño sistemático de instrucciones, datos, herramientas, memoria y estado que se entregan al modelo en cada paso.
Definition: Designing the Information Available for a Task
Context engineering is the design and management of information presented to an AI model during an execution to help it complete a specific task. It can include instructions, the user’s message, parts of the conversation history, examples, tool results, retrieved documents, and information about the current state of the work. The central decision is not just what to tell the model, but what information to include, in what form, at what point, and subject to which limits.
The term is used in a developing field and does not have a universally accepted formal definition across all disciplines and providers. It is more precise to treat it as a practical label for a set of observable technical decisions: gathering information, choosing which parts are relevant, organizing them for the task, and updating them as results or system state change. The name does not guarantee that a system follows a particular method or improves its performance.
In a simple conversation, context may consist mainly of instructions and messages. In an application that retrieves documents or uses tools, it may also include external results. In an agent working through several stages, some information may be stored outside the conversation and brought back in when needed. In every case, what matters is the information actually available to the model during that execution.
What Can Be Part of the Context
Instructions define the role, constraints, or expected format. The user’s message expresses the immediate need. Conversation history can provide references to earlier decisions, provided those exchanges remain relevant. Examples show response or problem-solving patterns, although their value depends on how representative they are of the task.
Retrieved documents and tool results provide information beyond the initial message. For example, a tool might return the contents of a file or the result of a search. Work state can record what has been done, what remains, and what result needs to be preserved for the next step. These elements do not always need to be present: including them unnecessarily also uses space and can add noise.
Context is not necessarily a single piece of text written by a person. It can be a collection assembled by an application before each model call. One part may come from a request; another, from a data source, search, conversation history, or previous operation. That is why looking only at the prompt visible to the user does not always reveal what information the model received.
Common Elements and Review Questions
| Element | What it can be used for | Review question |
|---|---|---|
| Instructions | Setting the task, constraints, and format. | Are they clear and consistent with one another? |
| History and state | Maintaining continuity across steps or turns. | Which parts are still needed and up to date? |
| Documents and tool results | Providing data to answer a question or take action. | Are they relevant, reliable, and sufficient for this task? |
| Examples | Illustrating a response or work pattern. | Do they represent the current case without encouraging inappropriate imitation? |
How the Context Engineering Cycle Works
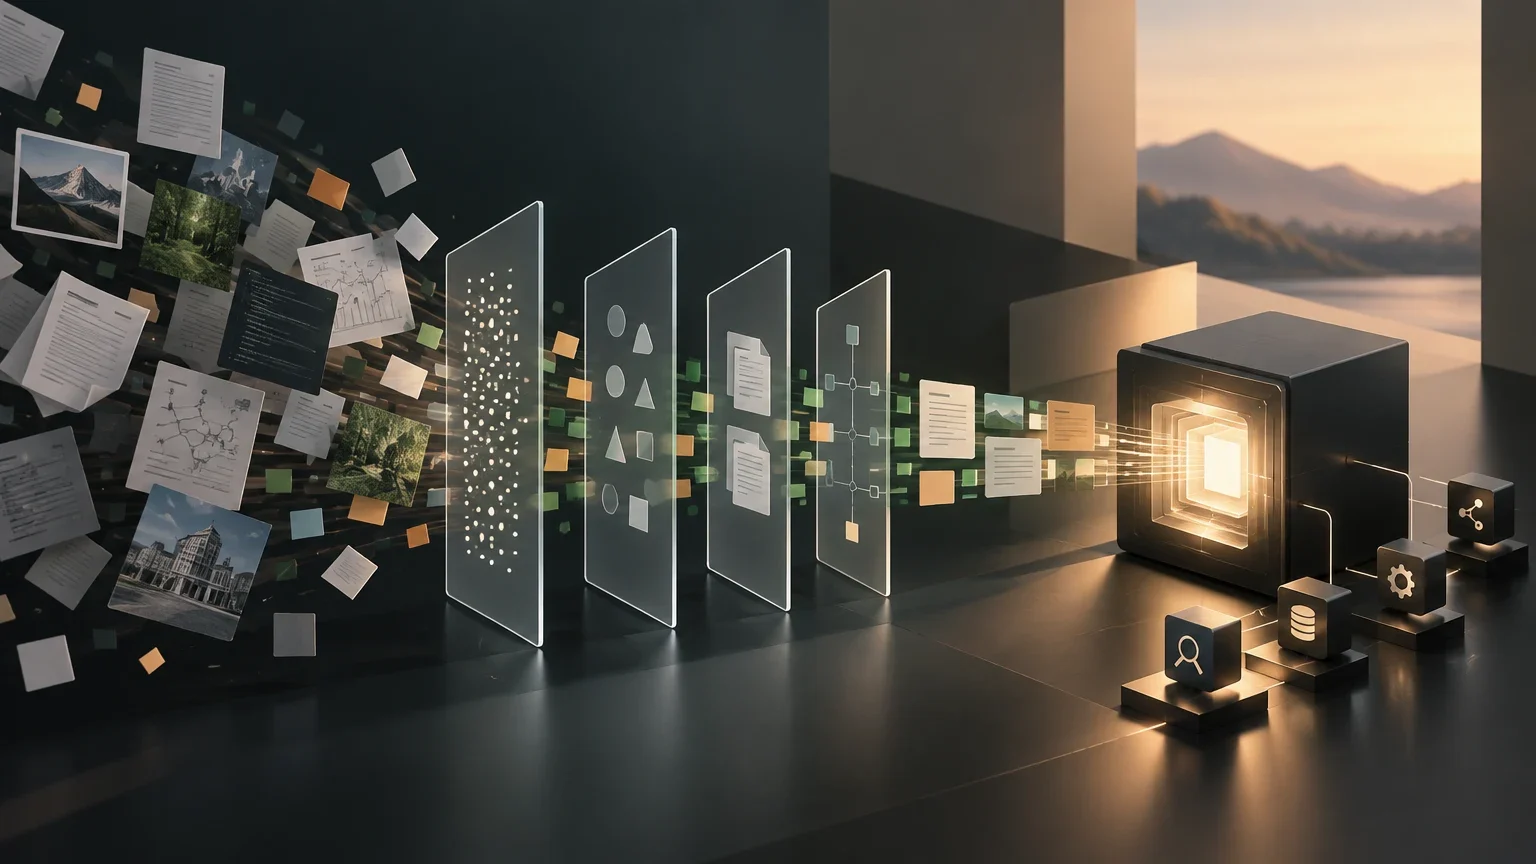
A context strategy can be understood as a cycle. First, identify what the task needs: for example, answering a question, editing a file, or comparing sources. Then obtain available information from the message, conversation history, documents, tools, or an external memory. Gathering data does not mean that all of it should be included: relevant information must be selected, checked for freshness, and distinguished from material that will not help.
Next, organize and transform the material. It may be necessary to extract passages, summarize results, separate facts from open questions, or structure the work state. The selected information is then added to the context the model will see. After the model responds or acts, the system can check the result and update the state: retain a useful finding, replace outdated information, or search for what is still missing.
The process repeats if the task continues. The right strategy depends on the task, sources, and system capabilities; there is no recipe that guarantees a correct result. Poor selection can omit a decisive fact. Including too much can make it harder for the model to find what matters. It is therefore useful to design the cycle around specific needs and observe what information the system uses.
Basic Cycle
- 01Define what the task requires and what result is expected.
- 02Gather potential information from the message, conversation history, documents, or tools.
- 03Select, organize, and transform the relevant information.
- 04Add it to the context available to the model.
- 05Review the response or action and update the state for the next step.
Applied Example: A Coding Agent
Imagine someone asks an agent to fix a bug in an application. Loading every project file at once may be unnecessary. A more selective strategy starts by identifying the error message and locating the components most likely to be related. The system can inspect files, tests, and documentation using tools, then give the model relevant excerpts alongside the constraints of the requested change.
After a change is made, test results or tool outputs may become part of the context for the next step. If work needs to continue at a later stage, a status note can summarize the goal, decisions, modified files, and outstanding tasks. That note is a partial representation of the work, not a complete transcript or a guarantee that no detail has been lost.
This pattern shows why context management can involve both on-demand searches and maintaining information across stages. Systems described for long-running agents use handoffs and external state to continue work when a single context window is not enough. The specific implementation depends on the agent.
Applied Example: Customer Support
In a customer support assistant, a person’s question might be combined with the current policy that applies to the case and a relevant part of their authorized history. For example, to check the status of a return, the system might need the current question, the applicable rule, and the order detail required to identify the transaction. This example is illustrative: the available sources do not document a specific customer support system with this configuration.
Selection should also limit access to what is necessary. If personal information does not help resolve the request, there is no reason to add it to the context by default. The application should define what information it may retrieve, who may access it, and how long it may be retained. These privacy and authorization decisions belong to system design; they are not solved simply by adding instructions to the model.
The assistant also needs to distinguish current policy from earlier messages that may be out of date. If an answer depends on a current rule, the retrieved information should be checked against an authorized source. The fact that a document appears in the context does not, by itself, prove that it is correct, current, or applicable to the case.
Applied Example: A Research Agent
A research agent can divide a complex question into several lines of inquiry and keep the materials gathered for each one separate. Rather than presenting every document to a single model at every step, it can maintain sources and findings by topic and give a coordinator a synthesis that points to relevant material and identifies unanswered questions.
A synthesis makes it easier to hand work from one stage to the next, but it can omit nuance or qualifications. For that reason, the work state should distinguish what was observed in the sources, what is an inference, and what still needs to be checked. If a conclusion depends on a detail, it may be necessary to return to the original document instead of relying only on a summary.
An Anthropic account of a multi-agent research system provides an example of organizing work among agents with separate contexts and synthesizing findings for a coordinating agent. It is a specific case of system design and does not show that the same architecture is better for every research task.
Related Concepts: Prompts, RAG, Chunking, Memory, and Context Windows
Prompt engineering focuses mainly on writing and organizing instructions to guide the model’s response. Context engineering has a broader scope: it also considers how to gather, select, organize, and update the rest of the available information. The two practices can overlap. A good instruction is part of the context, but it does not, by itself, solve which documents to retrieve or what state to retain.
Retrieval-augmented generation, or RAG, is an approach that combines information retrieval with generation. It can be a way to obtain documents for the context, but it is not synonymous with context engineering. A system can use RAG and still need to decide what to retrieve, which passages to include, and how to handle the results. Context can also be managed without using a RAG system.
Chunking means dividing documents or other materials into units for storage, retrieval, or processing. It affects which portions can reach the model, but does not, on its own, determine whether they are relevant or how they should be combined with instructions and conversation history. Memory, in turn, refers to mechanisms for retaining and retrieving information across moments or tasks. When something is retrieved from memory, the system still needs to decide whether it is relevant before adding it to the current context.
A context window is the limit on the information a model can process in a single execution, as determined by the system’s characteristics. It is not a strategy for choosing content: a larger window does not determine what to include or guarantee that every part will receive equal attention. A cache can reuse content or processing results to reduce repeated work, but it is also different from deciding what information a task needs.
How to Distinguish the Concepts
| Concept | Main question | Relationship to context engineering |
|---|---|---|
| Prompt engineering | How should the instructions be expressed? | It is one part of context design, not the entire process. |
| RAG | How can information be retrieved to generate a response? | It can supply documents, whose selection and inclusion still need to be managed. |
| Chunking | How should materials be divided into units? | It affects what can be retrieved; it does not decide by itself what should be included. |
| Memory | What information should be retained and retrieved across moments? | It can supply state that should be evaluated before being added to the current context. |
| Context window | How much information can one execution process? | It imposes a limit, not a selection policy. |
Common Misconceptions and Limitations
A common mistake is to assume that more context always helps. Experiments with models and long contexts have found that the ability to use information can vary depending on where relevant evidence appears. Increasing the amount of text or the size of the window therefore does not guarantee that the model will identify or use the needed information more effectively.
Another mistake is confusing information being available with information being used. The fact that a document was included does not show that it correctly influenced the response. Similarly, a summary does not necessarily preserve every nuance of the original. Compression can lose conditions, exceptions, or disagreements; decisive details should remain checkable against the source.
Retrieved material may also be incomplete, irrelevant, or outdated. In addition, documents and web pages can contain malicious instructions aimed at an agent. If the system treats such content as trusted instructions, it may be led away from its task. Prompt injection is a risk associated with adding untrusted content; defenses need to be tested and should not be assumed effective merely because they exist.
Context selection also involves decisions about cost, latency, and privacy. Retrieving or processing more information can add work, while moving unnecessary data into the context expands its exposure. There is no universally correct amount of context: it depends on the task, source quality, system constraints, and the errors the design is intended to prevent.
How to Evaluate a Strategy
To find out whether a strategy helps, define representative test tasks and decide in advance what counts as an acceptable result. Then compare variations: for example, what happens when fewer documents are retrieved, the evidence is ordered differently, or a more explicit status summary is retained. Where possible, change one decision at a time to make the comparison easier to interpret.
Evaluation can look at the quality of responses or actions, omissions of relevant information, selection errors, latency, cost, and the amount or sensitivity of the data included. In systems that use documents, it is also useful to check whether answers rely on sources that are applicable and current. Results should be interpreted in relation to the tasks and test data used; they do not automatically demonstrate that the strategy will work in other cases.
To attribute an improvement to context management, compare results systematically and keep the model and other relevant conditions as constant as possible. An anecdotal impression, or the fact that an answer sounds convincing, is not enough to demonstrate causality. If errors occur, examining what was retrieved, what was omitted, and what information actually reached the model can help locate the problem.
A Short Design Review Checklist
- 01Does the included information address an identified need for the task?
- 02Have the relevance and freshness of the sources been checked?
- 03Does the system preserve critical details that a summary might omit?
- 04Are personal data that are not needed excluded?
- 05Have quality, omissions, latency, and cost been measured on representative tasks?
- 06Have untrusted inputs and situations where retrieval fails been tested?
Practical Criteria and Related Concepts
When designing a system, start by specifying the task and the information that could change the response or action. Obtain information only from permitted sources, select what is relevant, and keep a way to review the original material if a synthesis is not enough. Update the state when new evidence arrives instead of accumulating conversation history indefinitely when it may no longer be useful.
Then test the design with ordinary cases and edge cases: contradictory sources, outdated information, ambiguous requests, and documents containing instructions unrelated to the task. Review what reaches the model, what is left out, and what result follows. If the system fails, do not assume that it needs more context; check whether the problem lies in retrieval, selection, organization, data freshness, or the model’s interpretation.
To explore the related vocabulary, see the glossary entries on prompt engineering, RAG, chunking, and memory, as well as the glossary index. The practical distinction is straightforward: prompts are mainly about instructions; RAG is about retrieving information for generation; chunking is about dividing materials; and memory is about retaining and retrieving state. Context engineering considers how to combine these pieces for a particular execution.