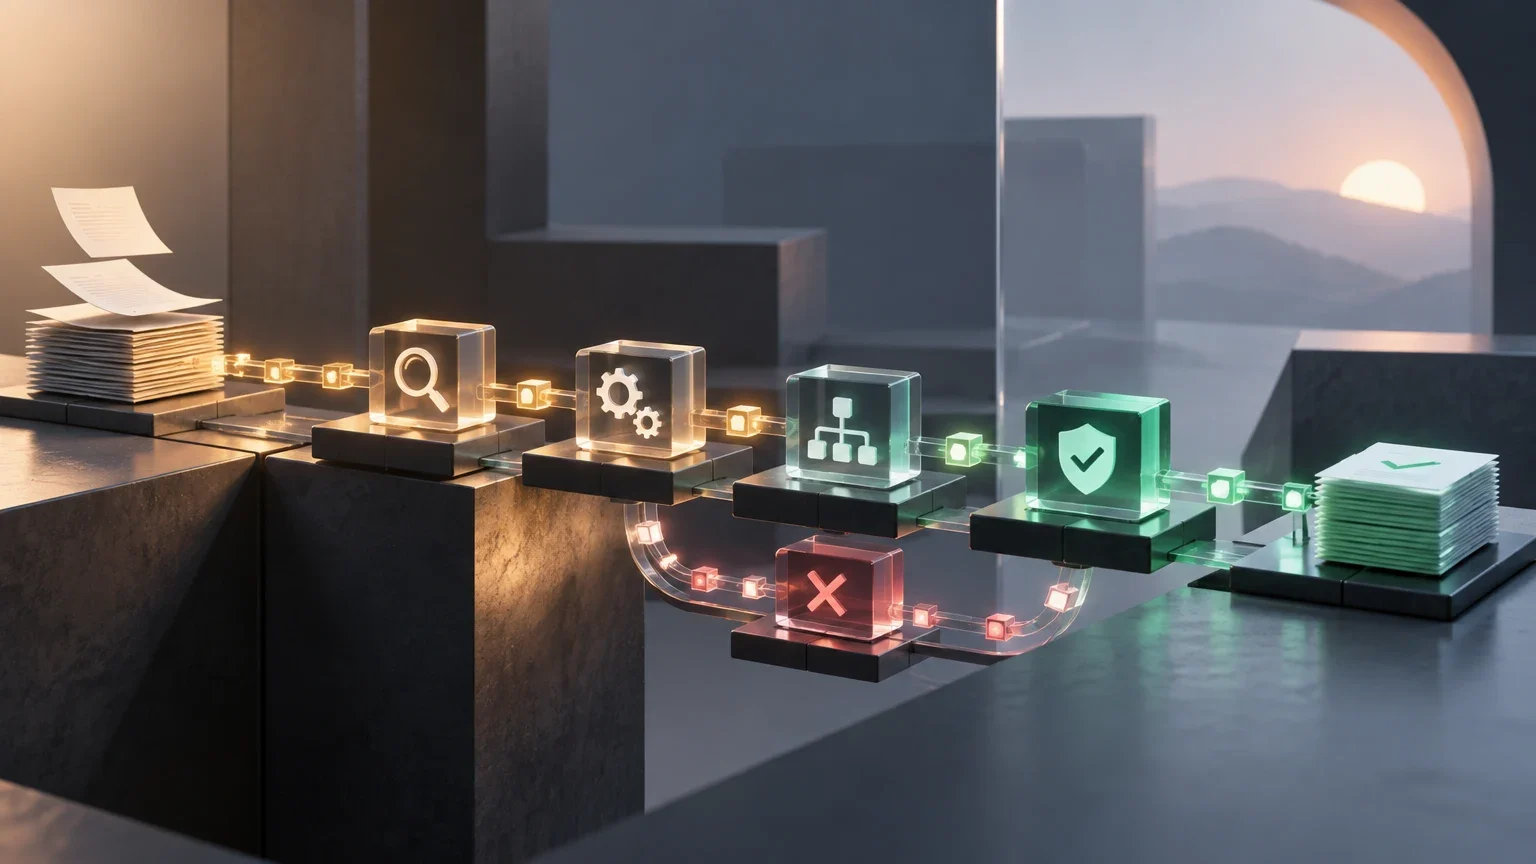
The boundary between a one-off task and a multi-step workflow
AI workflow automation uses AI technologies and products to automate tasks and improve activities within an organization. In structured sequences, AI systems perform, coordinate, or support processes, either autonomously or in collaboration with human workers. The concept covers a wide range, from a language model classifying support tickets to a multi-agent workflow coordinating research, drafting, and review.
The operational challenge is not whether a model can perform one isolated action. It is whether the system can reliably complete a sequence of interdependent steps under changing conditions. An agentic workflow combines adaptive reasoning with deterministic execution to handle complex tasks that conventional automation approaches may not manage effectively. Orchestration coordinates the work within a defined governance framework, helping keep agent behavior traceable, controlled, and aligned with business rules.
The distinction between a single task and a multi-step workflow defines the operational scope of the automation. A one-off task relies on a model's immediate response, whereas a multi-step workflow demands sustained coordination across multiple stages. This structural difference shifts the focus from raw model performance to the stability of the entire execution chain, where each step depends on the successful completion of the previous one.
Operational differences between traditional and agentic workflows
Comparison of key attributes described in Automation Anywhere’s documentation.
| Attribute | Traditional workflows | Agentic workflows |
|---|---|---|
| Execution model | Predefined and path-driven | Goal-driven and resolved at runtime |
| Exception handling | Stops or routes the process to people | Attempts to resolve the issue autonomously |
| Adaptability | No: requires reprogramming | Yes: adjusts to context |
| Logical basis | Predefined rules | Natural-language reasoning |
Components of the orchestration stack
An agentic workflow architecture brings together several elements that interact to support execution. At its core is the AI agent. Rather than being a static script, it is a system built on AI models that can interpret goals and assess context. Agents can interact with existing systems, analyze data, collaborate with other agents, and communicate with people in natural language.
The orchestration layer acts as the system’s conductor, managing workflow sequences and routing to determine which tools run, when, and under what conditions. This layer matters because it enables agentic workflows to operate in business environments; without it, autonomous agent behavior can introduce operational risk. APIs let software applications communicate and exchange data, features, and functions, making them a key part of connecting services within a workflow.
The interaction between the AI agent and the orchestration layer creates a dynamic feedback loop that sustains workflow integrity. The agent provides the cognitive flexibility to interpret ambiguous inputs, while the orchestration layer enforces the structural constraints necessary for business compliance. This division of labor ensures that adaptive reasoning does not compromise the deterministic requirements of enterprise processes, maintaining a balance between innovation and operational control.
Operating cycle of an agentic workflow
Stages summarized from Automation Anywhere’s technical documentation.
- 01Signal capture and event monitoring: The agent detects a trigger and interprets the request to clarify the user’s intent.
- 02Context, memory, and RAG: The agent retrieves relevant information, such as policies and historical data, using retrieval-augmented generation (RAG).
- 03Reasoning and planning: The agent assesses information, weighs options, and creates a plan by dividing the goal into a sequence of steps.
- 04Action execution: The agent calls tools such as RPA or APIs to carry out planned tasks, pausing when human approval is required.
- 05Feedback and adaptation: Results are logged and evaluated; exceptions are flagged for review, and lessons inform workflow logic.
Critical points of failure during execution
Implementing agentic workflows requires a strong approach to risk because AI agents can behave unexpectedly. One major challenge is uncontrolled execution: a poorly configured goal can cause an agent to loop or perform tasks incorrectly. Clear execution limits and progress monitoring are essential to managing this risk.
Another potential failure point is hallucination, in which an agent misinterprets a policy or generates information that does not exist. Grounding the agent in a verified knowledge base and requiring explicit approval for high-risk actions can help mitigate this issue. Context drift in long workflows can also affect the reliability of the final output if the agent loses alignment with the original instructions or the system’s state as the sequence progresses.
Uncontrolled execution often manifests as repetitive loops when an agent fails to recognize that a goal has been achieved or when it encounters an unresolvable error. These loops consume computational resources and can delay critical business operations. Implementing strict iteration limits and timeout mechanisms within the orchestration layer provides a deterministic safeguard against such scenarios, ensuring that the system halts gracefully rather than continuing to process indefinitely.
Evaluation criteria for choosing tools
Choosing the right automation tool is central to operational viability. Evaluation should focus on state management between steps, recovery from partial failures, and verification of the final output. An effective orchestrator should support persistent session-state storage, whether in relational databases such as PostgreSQL or key-value systems such as Redis, so that a workflow can resume after a failure.
The end-to-end workflow success rate is a key metric for distinguishing a model failure from an orchestrator failure. If an intermediate step fails and is recovered, the success rate should reflect the system’s ability to handle the exception without interrupting the overall process. Cost per run and latency also matter, especially in high-frequency workflows where reducing calls to expensive language models can directly affect economic viability.
State management is the backbone of reliable workflow execution, particularly when processes span multiple sessions or require long-term memory. By persisting state in external databases, the system can reconstruct the context of a failed run and resume operations from the last stable point. This capability is essential for maintaining data integrity and preventing the duplication of actions that could lead to inconsistent records or financial discrepancies in high-stakes environments.
Operational evaluation metrics
Key indicators for assessing the reliability of an automated workflow.
| Metric | Description | Importance |
|---|---|---|
| End-to-end workflow success rate | Percentage of runs that complete every step without unplanned human intervention | High: measures the system’s overall robustness |
| Recovery time | Time from detecting a failure to resuming the workflow | Medium: affects user experience and service-level agreements |
| Cost per run | Total API, compute, and storage costs for a complete cycle | High: determines economic viability at scale |
| Context-drift rate | How often an agent loses alignment with the initial instructions in long workflows | Medium: affects final-output quality |
Separating model capability from system robustness
A common evaluation mistake is to confuse a language model’s capability with the reliability of the orchestration system. A model may generate the right answer in an isolated test, but that does not guarantee that the complete workflow will run reliably under load or with variable data. System robustness depends on orchestration architecture, state management, and verification mechanisms—not just the quality of the underlying model.
Final-output verification is a critical part of distinguishing a workflow that merely works in a demonstration from one designed for business use. Professional workflows include output-validation steps that check fields, assess model confidence, and require human approval when needed. In this hybrid approach, AI handles judgment-based decisions while the workflow applies deterministic rules and safety checks.
Distinguishing between model capability and system robustness prevents misallocation of resources during the development phase. A high-performing model in isolation may still fail within a complex workflow if the surrounding infrastructure lacks adequate error handling or state persistence. Evaluating the system as a whole, rather than focusing solely on the underlying language model, ensures that the final solution is resilient to the variability inherent in real-world data and operational conditions.
Pilot protocol for validation
Before production deployment, run a pilot protocol to validate the automation in a controlled environment. Start by identifying suitable processes: tasks that use substantial data, require judgment, or are currently slowed by manual handoffs. Tool selection should ensure that the technology stack supports language models, orchestration, and integration mechanisms.
Define human oversight explicitly, including where a person must intervene to approve an action. Test scalability by increasing data volume and the complexity of edge cases. A 2026 paper reports that a self-hosted n8n deployment at an academic institution achieved availability above 98% during its operating period. That result describes one institutional deployment; it does not establish that self-hosted platforms will achieve the same availability in other environments.
The pilot protocol serves as a critical validation stage before full-scale deployment, allowing teams to identify and mitigate risks in a controlled setting. By testing the workflow with representative data and edge cases, organizations can verify that the system handles exceptions appropriately and that human oversight mechanisms function as intended. This phased approach reduces the likelihood of production failures and provides a clear baseline for measuring the effectiveness of the automation in real-world scenarios.
Steps for implementing agentic workflows
Implementation roadmap summarized from Automation Anywhere’s documentation.
- 01Identify suitable processes: Select data-intensive tasks that require judgment or are slowed by manual handoffs.
- 02Choose AI tools: Ensure the technology stack supports language models, orchestration, and integration mechanisms.
- 03Run pilots: Test whether agentic workflows deliver value in a controlled environment.
- 04Establish human oversight: Specify exactly where a person must intervene to give explicit approval.
- 05Scale incrementally: Refine agent prompts and tools based on pilot feedback.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction