What the model actually does
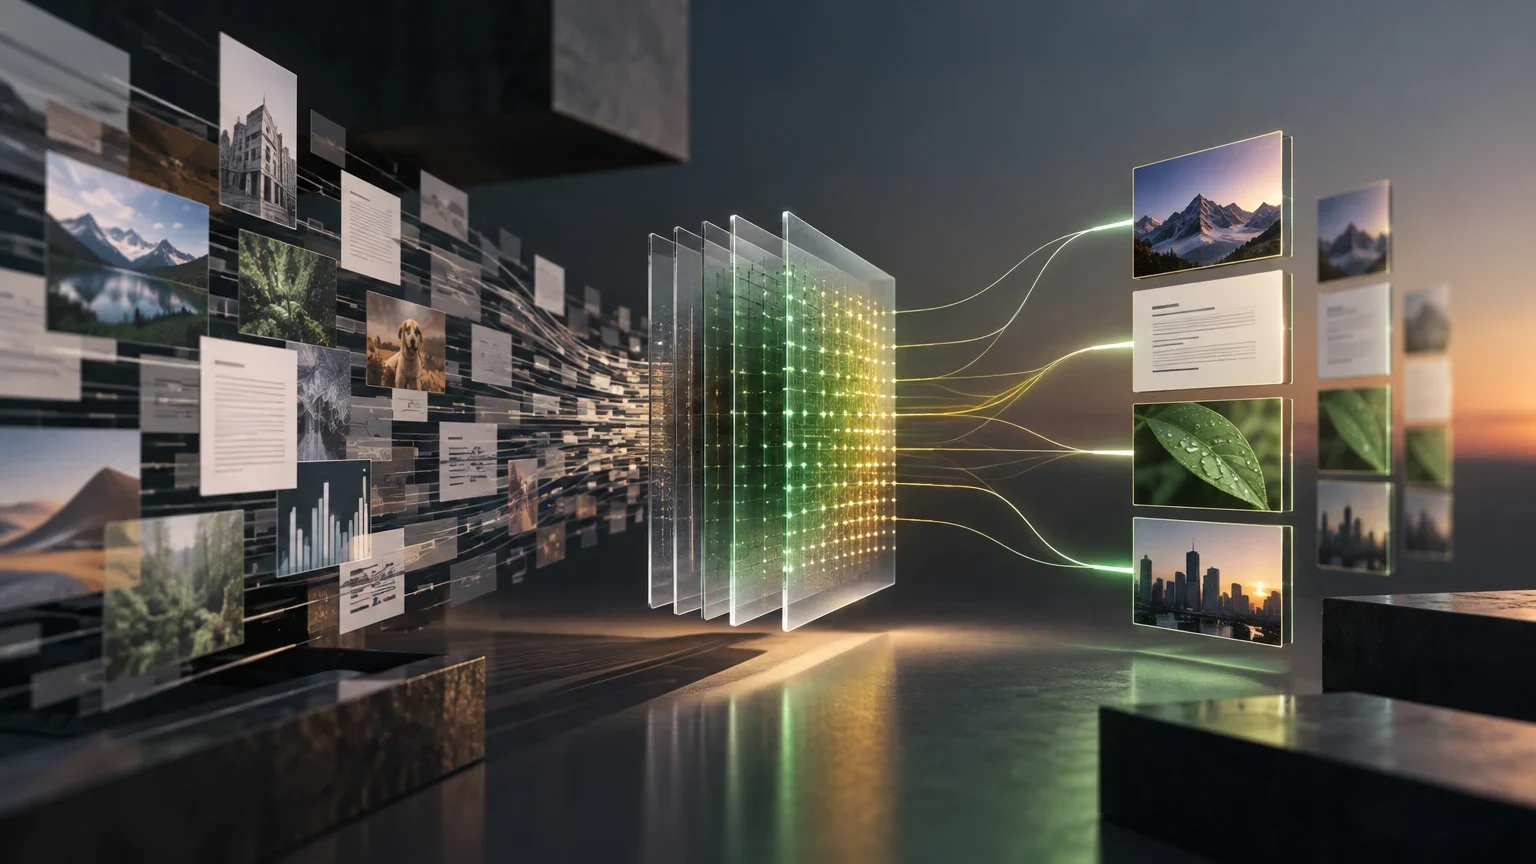
Nemotron 3.5 Rerank 8B BF16 is a reranking model developed by NVIDIA, published on October 20, 2026. Its specific function is to score the relevance of a document relative to a text query, returning a single numerical value (logit) for each query-document pair. It does not generate text, create embeddings, or answer questions directly; its role is to reorder a list of candidates previously retrieved by a dense search system.
The model is multimodal: it accepts text, a page image, or a combination of both as the document. This distinguishes it from purely textual rerankers and positions it as a key component in Retrieval-Augmented Generation (RAG) pipelines that handle visually rich documents, such as PDFs with tables, charts, or infographics. The architecture combines a Pixtral-based visual encoder with a bidirectional Ministral3-based language tower, allowing it to process both textual and visual information from the document simultaneously.
The separation of duties between the initial retrieval stage and the reranking stage is critical for system efficiency. The dense search model generates embeddings for the entire corpus, a computationally intensive process that is typically performed offline or with significant latency. In contrast, the reranker operates on a small, pre-filtered subset of documents, allowing it to apply a more complex, cross-encoder-like attention mechanism without incurring the prohibitive costs of processing the entire database. This architectural division ensures that the system can scale to large corpora while maintaining the high precision required for downstream generative tasks.
The bidirectional nature of the language tower allows the model to attend to both preceding and following tokens in the query and document simultaneously. Unlike autoregressive models that process text sequentially from left to right, this architecture captures global contextual dependencies within the input pair. This capability is particularly beneficial for reranking, where the relevance of a specific phrase often depends on its relationship to the entire document structure and the full scope of the user's query, rather than just local word proximity.
Capabilities and examples by task
The model is designed for three types of document input: text only, image only, and text+image. In practice, this allows its use in scenarios where relevant information is distributed between text extracted from a PDF and the images of its pages. For example, if a query asks for a specific data point appearing in a table, the reranker can evaluate both the extracted OCR text and the original page image to determine which best represents the answer.
The official card provides a usage example comparing a document with NeMo Framework text and image against a biology document. The model assigns higher scores to documents related to NeMo, regardless of whether they contain only text, only an image, or both, and lower scores to the biology document. This demonstrates its ability to capture semantic relevance across multiple modalities.
The ability to process text and images concurrently addresses a common failure mode in traditional RAG pipelines. Standard text-only rerankers often discard visual information during the preprocessing stage, relying solely on OCR-extracted text. This approach can lead to significant information loss, particularly when the visual layout, spatial arrangement of data in tables, or graphical elements convey meaning that is not fully captured by linear text extraction. By retaining the original page image, the model preserves these structural and visual cues, enabling a more holistic assessment of document relevance.
In scenarios involving complex documents such as financial reports or scientific papers, the relationship between a textual caption and its associated chart is often essential for understanding the data. The multimodal input allows the model to cross-reference the numerical values in the text with the visual trends in the chart, ensuring that the reranking decision accounts for both the explicit data and its visual representation. This reduces the risk of retrieving documents that are textually similar but visually inconsistent or misleading, thereby improving the overall quality of the context provided to the generative model.
Published benchmarks and methodology
The official card indicates that the model was evaluated on two main benchmarks: ViDoRe V3 for visual document retrieval and MIRACL-VISION for multilingual visual retrieval. The reported metric is NDCG@10. However, the card does not publish specific numerical scores for this checkpoint, which prevents a direct comparison with other models at the time of writing this analysis.
For text retrieval, the model was evaluated in 34 languages, including English, Spanish, French, German, Chinese, Japanese, among others. For image retrieval, the evaluation covered 18 languages. These evaluation sets describe the coverage measured, rather than a universal performance ranking. Choosing a system requires checking retrieval with representative queries and documents under comparable conditions.
The selection of ViDoRe V3 and MIRACL-VISION as primary benchmarks reflects the model's focus on visual document understanding. ViDoRe V3 specifically targets the retrieval of documents where visual elements play a central role in the query-answer relationship, while MIRACL-VISION extends this evaluation to a multilingual context. The use of NDCG@10 as the metric emphasizes the importance of ranking quality in the top results, which is the most critical portion of the list for downstream applications. A high NDCG@10 score indicates that the most relevant documents are not only retrieved but also placed at the top of the ranked list.
The multilingual evaluation across 34 languages for text and 18 for images highlights the model's intended global applicability. This breadth of language support is crucial for organizations with diverse document corpora, ensuring that the reranking performance does not degrade significantly when processing non-English content. The inclusion of both public and private test sets in the ViDoRe V3 evaluation suggests a rigorous testing protocol designed to prevent overfitting to known benchmarks, although the specific performance metrics remain unpublished for this particular checkpoint.
Benchmarks mentioned in the official card
Summary of the evaluation sets cited by NVIDIA for this model.
| Benchmark | Type | Languages | Metric | Published Score |
|---|---|---|---|---|
| ViDoRe V3 | Visual document retrieval | 8 public, 2 private | NDCG@10 | Not published |
| MIRACL-VISION | Multilingual visual retrieval | 18 | NDCG@10 | Not published |
| Text Evaluation | Textual retrieval | 34 | Not specified | Not published |
Pricing and deployment requirements
The model is distributed under the OpenMDW-1.1 license, which allows commercial and non-commercial use, subject to the terms of that license. There is no official commercial API published by NVIDIA for this specific model, so the main cost is the GPU infrastructure required for its execution. The model weights are publicly available on Hugging Face.
Regarding hardware requirements, the official card specifies compatibility with NVIDIA Ampere (A100 80GB), Hopper (H100 80GB), and Blackwell (GB200 186GB) architectures. The model uses bfloat16 precision, which reduces memory consumption compared to float32, but still requires high-performance GPUs. For inference, an environment with CUDA and Flash Attention 2 is recommended to optimize speed.
The reliance on specific NVIDIA GPU architectures, such as Ampere, Hopper, and Blackwell, is driven by the need for native support of bfloat16 precision and optimized matrix multiplication kernels. These architectures provide the necessary computational throughput and memory bandwidth to handle the large context windows and multimodal inputs efficiently. The use of bfloat16, rather than float32, halves the memory footprint of the model weights and activations, which is essential for fitting the model into the available GPU memory while maintaining numerical stability during inference.
The recommendation to use Flash Attention 2 is a key optimization for reducing latency. Flash Attention 2 improves the memory access patterns of the attention mechanism, reducing the number of reads and writes to high-bandwidth memory. This optimization is particularly beneficial for reranking tasks, where the model must process multiple query-document pairs in a short time. By minimizing memory bottlenecks, Flash Attention 2 allows the model to achieve higher throughput, making it more suitable for real-time or near-real-time retrieval applications.
Hardware and software requirements
Minimum recommended configuration according to official documentation.
| Component | Requirement | Notes |
|---|---|---|
| GPU | NVIDIA A100 80GB, H100 80GB, or GB200 186GB | Ampere, Hopper, or Blackwell architectures |
| Precision | bfloat16 | Requires native GPU support |
| Libraries | Transformers 5.20.0, vLLM 0.32.0 | Flash Attention 2 recommended |
| Operating System | Linux | Windows or macOS support not documented |
Limitations, security, and alternatives
The most significant documented limitation is the maximum context of 32,768 tokens, which is shared between text and image. If the combination of both exceeds this limit, it is necessary to truncate the text or reduce the image resolution. By default, the longest side of images is limited to 1,120 pixels, although it can be expanded to 1,540 pixels. This restriction can affect performance on very long documents or high-resolution images.
Regarding security, the official card warns that the model does not always guarantee a meaningful ranking for a given query. Additionally, it is recommended to review any remote code (trust_remote_code) before executing it, as it may contain unverified logic. No specific vulnerabilities have been documented, but as with any AI model, it is the developer's responsibility to implement appropriate security controls.
The shared context limit of 32,768 tokens imposes a practical constraint on the size of documents that can be processed in a single inference pass. For very long documents, such as entire books or extensive technical manuals, the input must be segmented into smaller chunks that fit within the context window. This segmentation strategy requires careful consideration to ensure that relevant information is not split across chunk boundaries, which could degrade the reranking accuracy. Developers must implement preprocessing logic to handle these edge cases, potentially using sliding windows or hierarchical summarization to manage long-form content.
The security implications of using remote code extend beyond simple vulnerability scanning. The trust_remote_code mechanism allows the model to execute Python code defined in the model's repository, which may include custom attention mechanisms or preprocessing functions. In production environments, this code must be treated as untrusted input and subjected to rigorous code review and sandboxing. Failure to do so could expose the system to potential security risks, including data exfiltration or denial-of-service attacks, particularly if the model is deployed in a multi-tenant or cloud-based environment.
Practical selection criteria
The decision to use Nemotron 3.5 Rerank 8B BF16 should be based on several factors: the need for multimodal reranking, the availability of suitable GPU hardware, and the ability to integrate the model into the existing pipeline. If the corpus is purely textual, a lighter textual reranker might be sufficient and more economical. If the corpus includes visually rich documents, this model offers a clear advantage by being able to evaluate both text and image.
For teams without access to high-performance GPUs, the option of deploying this model locally may not be viable. In those cases, the use of third-party APIs offering multimodal reranking should be considered, although this introduces API costs and potential privacy restrictions. The final choice must balance accuracy, cost, latency, and compliance requirements.
The decision to deploy this model locally versus using a third-party API involves a trade-off between data privacy and operational cost. Local deployment ensures that sensitive documents do not leave the organization's infrastructure, which is a critical requirement for industries with strict data residency or compliance regulations, such as healthcare or finance. However, this approach requires significant upfront investment in GPU hardware and ongoing maintenance of the inference environment. Conversely, third-party APIs offer a lower barrier to entry and handle the infrastructure complexity, but they introduce data transfer costs and potential privacy concerns related to the handling of proprietary documents by external providers.
Performance testing with proprietary data is a crucial step in the selection process, as benchmark scores may not accurately reflect the model's performance on a specific corpus. The distribution of document types, language, and visual complexity in an organization's data can vary significantly from the evaluation sets used in public benchmarks. By measuring NDCG@10 and latency on internal data, teams can validate the model's suitability for their specific use case and identify any necessary preprocessing or configuration adjustments. This empirical validation ensures that the final deployment meets the required accuracy and performance targets.
Decision process for implementing the reranker
Recommended steps to evaluate the viability of Nemotron 3.5 Rerank 8B BF16.
- 011. Assess whether the corpus contains visually rich documents (images, tables, charts).
- 022. Verify the availability of compatible GPU hardware (A100, H100, or GB200).
- 033. Conduct performance tests with proprietary data to measure NDCG@10 and latency.
- 044. Compare with textual alternatives or third-party APIs in terms of cost and accuracy.
- 055. Audit remote code and security requirements before production deployment.
Keep exploring
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction