Laboratory
Entity that develops or publishes the model and maintains its technical and safety documentation.
Explore the documented models, published evaluations and primary sources associated with this organisation.
Generalist frontier model oriented towards complex tasks, use of tools and highly demanding professional work.
16 SEP 2026↗ GENERALIST FRONTIERComplex work, coding, and tool-using agents.
16 SEP 2026↗ COST/CAPABILITY BALANCETasks requiring a balance of quality, speed, and cost.
16 SEP 2026↗ HIGH EFFICIENCYHigh volume, subagents, and structured extraction.
16 SEP 2026↗ PREVIOUS FRONTIERPrevious OpenAI generation for code and professional work, retained for comparing migrations and cost.
18 SEP 2026↗ NON-REASONING · LONG CONTEXTLong-context non-reasoning model, useful as a historical reference for code, instruction following, and predictable latency.
18 SEP 2026↗ OPEN REASONINGReasoning model with open weights for local or private execution; fits on one H100 GPU according to OpenAI.
18 SEP 2026↗ VISUAL GENERATION AND EDITINGOpenAI's main model for generating and editing images with complex instructions and high-quality visual production.
18 SEP 2026↗ VIDEO WITH SYNCHRONIZED AUDIOHistorical video model with synchronized audio, useful for comparing the evolution of the Sora family.
18 SEP 2026↗ REAL-TIME VOICE CONVERSATIONReal-time voice model for expressive conversations, natural interruptions, and tool-enabled workflows.
18 SEP 2026↗ SPEECH RECOGNITIONSpecialized high-accuracy transcription model for files and real-time audio inputs.
18 SEP 2026↗ TEXT VECTOR REPRESENTATIONOpenAI's highest-capacity embedding model for semantic search, classification, clustering, and RAG.
18 SEP 2026↗ CODING, COMPUTER USE AND PROFESSIONAL WORKOpenAI model for complex coding, computer use and professional work with text and image inputs. The provider describes performance close to Astra at a lower cost; assess that trade-off on your own tasks.
30 SEP 2026↗Figures are shown with the context reported by their source. A provider result is not an independent comparison and does not replace your own evaluation.
An organization, a product, and a model are not the same unit. Inferama separates them to avoid attributing capabilities or commercial terms to the wrong item.
Entity that develops or publishes the model and maintains its technical and safety documentation.
Identifiable version with limits, modalities, and behavior that may change between releases.
API, application, associated cloud, or commercial plan; each channel may have different pricing, retention, and limits.
Every claim must retain the official page consulted and the verification date.
An arena score reports the outcome of a comparison under a specific protocol; by itself, it does not prove that a model follows instructions better, maintains temporal continuity, or synchronizes audio and video. This guide separates what can be said about Sora 2 Pro from what the available benchmarks do not establish.
26 Sep 2026 ↗
A guide to evaluating GPT‑Live‑1 in full-duplex voice conversations by separating turn dynamics, comprehension, task success, and the safety of delegated actions. It proposes a reproducible protocol using controlled audio, traces, temporal annotation, and blinded human review.
23 Sep 2026 ↗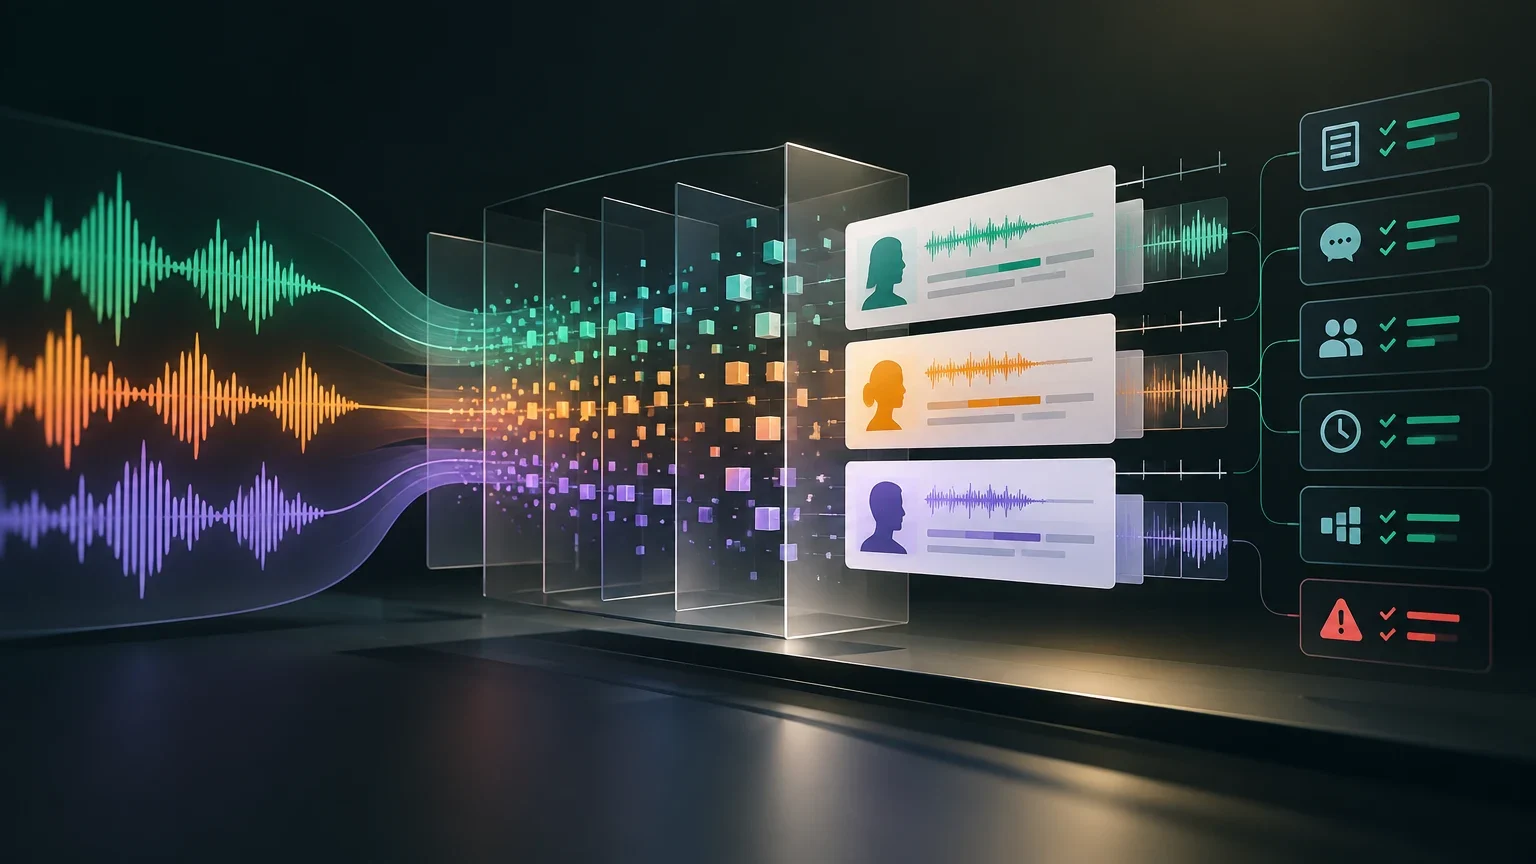
A useful automatic speech recognition evaluation cannot be reduced to a single accuracy percentage. This guide proposes a protocol for separately measuring text fidelity, critical entities, speaker attribution, timestamps, segmentation, and the validity of the output consumed by an application. The goal is to compare versions and configurations reproducibly, then decide with evidence when to promote, restrict, or block a deployment.
23 Sep 2026 ↗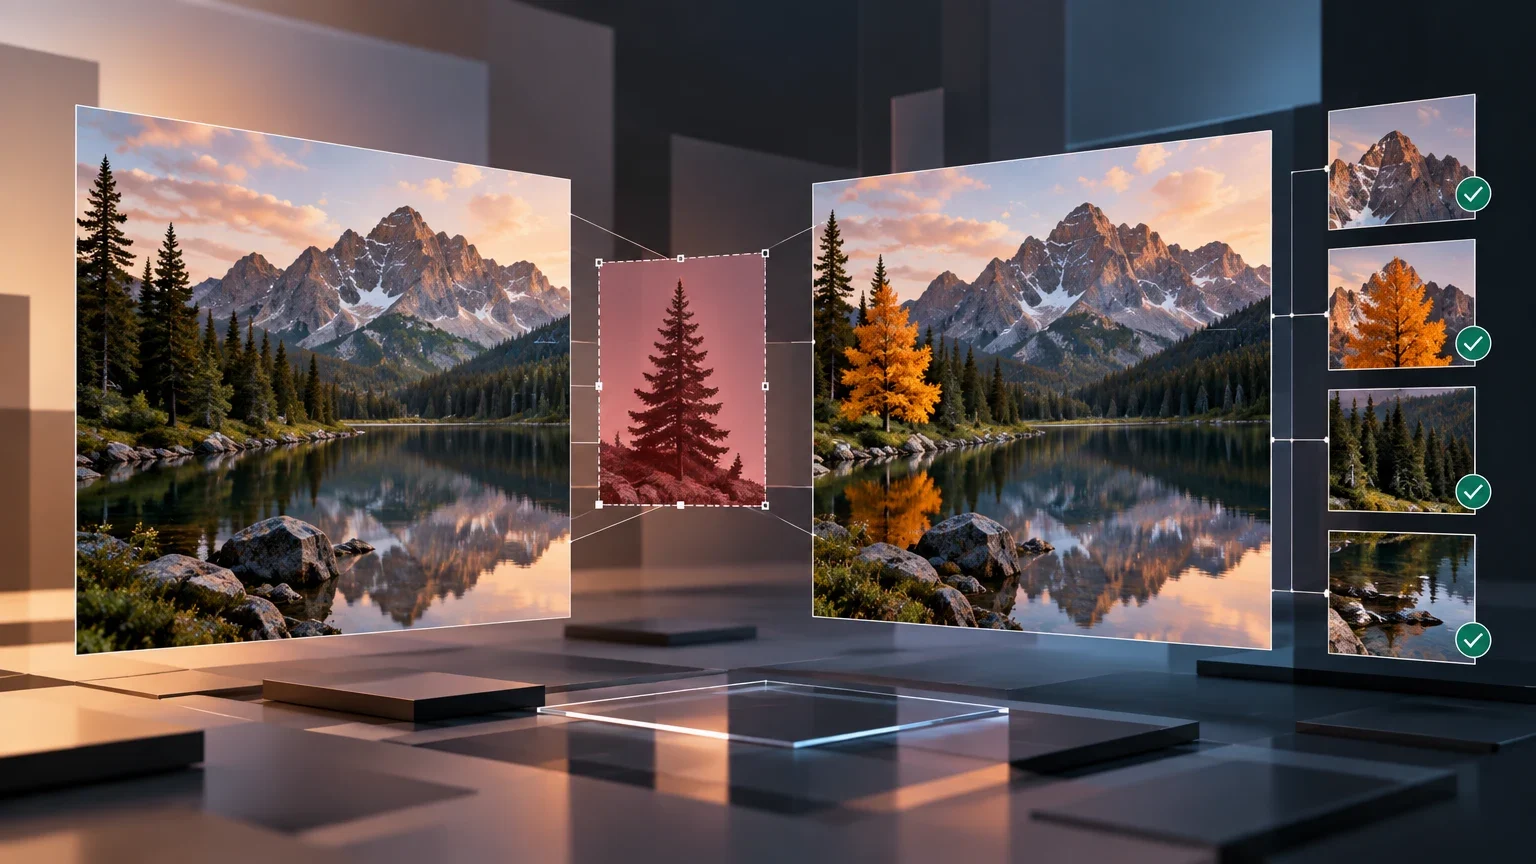
A generative edit that is useful in production is not validated merely because the requested change looks correct. This guide proposes treating every retouch as a preservation contract: define what may change, what must remain, how to measure it, and when to require human review.
23 Sep 2026 ↗
GPT-Transcribe is listed as a transcription model available through the OpenAI API. Before replacing an existing ASR system, teams should validate not only the resulting text, but also the technical contract that supports search, summaries, alerts, quotations, reviews, and compliance records.
22 Sep 2026 ↗
BenchCAD 1.0 measures whether a system can generate, modify, or interpret CadQuery programs whose geometry can be executed and compared with a reference. It is a useful signal for parametric reconstruction, but it does not replace validation of tolerances, function, manufacturing, or integration into an engineering workflow.
22 Sep 2026 ↗