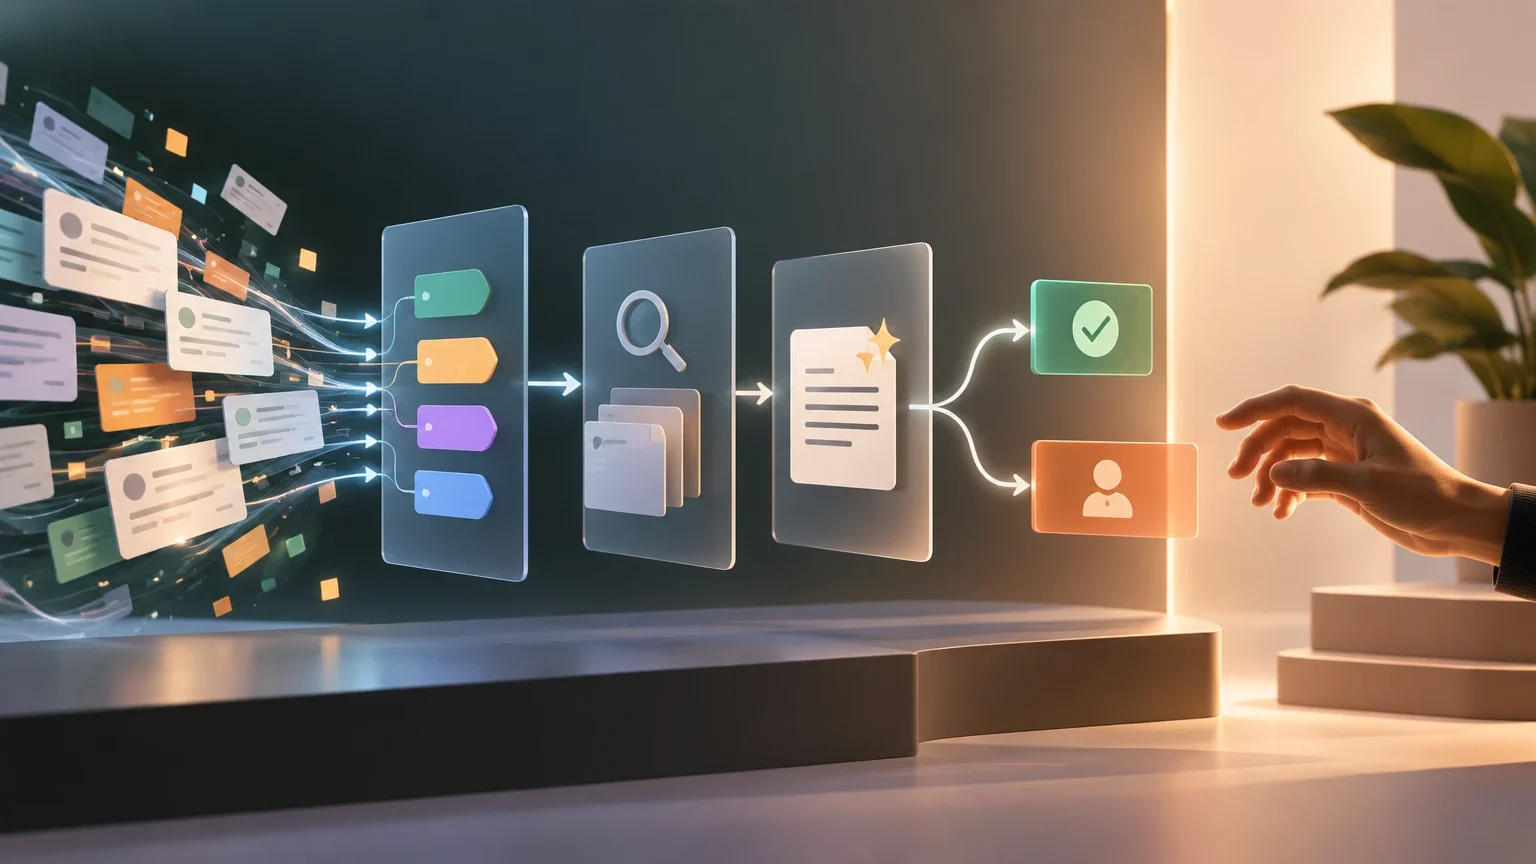
The starting mistake: treating every ticket as equally safe to answer automatically
A support team may receive thousands of emails, chats, and forms that appear repetitive. That repetition invites full-response automation: the system reads the message, chooses a category, drafts a reply, and may even modify an account, process a cancellation, or promise a refund. The problem is not that these four tasks happen in seconds. It is that they do not have the same meaning or carry the same risk for the person receiving support.
Classifying a ticket as a possible access issue is an operational prediction. Retrieving a help article is evidence retrieval. Drafting an explanation is language generation. Changing a plan, disclosing data, resetting credentials, cancelling a service, or deciding compensation is an action that may affect a customer’s rights, money, security, or contractual relationship. A responsible workflow does not treat these outputs as equivalent.
Reducing the average time to first response also does not, by itself, prove that support has improved. An instant reply that misunderstands the request, relies on outdated documentation, or forces the customer to repeat information may increase reopenings, transfers, and frustration. Evaluation must focus on whether the case reaches the appropriate route and is resolved correctly, with relevant evidence and a real opportunity for correction when the system fails.
Before choosing models or vendors, the team must decide which kind of work it wants to automate and which consequences it accepts if the system is wrong. The guide to choosing use cases can help define the problem; decisions about autonomy should be treated as a matter of safety and governance, not as a simple productivity setting.
Separate the four operations in the support workflow
Designing the workflow as one opaque automation hides where errors occur. It is better to divide it into observable operations and record the result of each one. The first is classification: identifying intent, product, language, apparent urgency, category, and destination queue. The second is retrieval: locating authorized, current information in the knowledge base, case history, and, where appropriate, permitted internal systems. The third is drafting: turning that evidence into a clear response consistent with the support tone. The fourth is execution: closing the case, sending the response, or making a change in a system.
This separation makes it possible to apply different controls. Classification can suggest a queue and display confidence, but high confidence does not prove that the label is correct. Retrieval needs to verify the scope of permissions, the currency of the policy, and the match between source and case. Drafting needs to prevent the model from filling gaps with plausible but unsupported information. Execution requires authorization rules, pre-action validations, and its own traceability, even when the draft itself is flawless.
It also clarifies an important limit: AI should not use every available field merely because it can technically read it. Ticket and profile fields must relate to a defined support purpose, be necessary to resolve the case, and be subject to controlled retention. Especially sensitive information, irrelevant data, or attributes that may bias routing should be excluded by design unless there is a justified need and appropriate controls.
The access inventory should document, for each operation, which data the system may consult, which source provides it, which permissions are required, and what is expressly out of scope. A vague access policy leaves the model and its integrations as implicit arbiters of whether data is needed; that is not an appropriate role for a text prediction system.
Separate operations and their primary control
| Operation | Expected result | Minimum control | Can it act on its own? |
|---|---|---|---|
| Classify | Suggested label, priority, and queue | Reviewed sample, threshold by category, and abstention route | Yes, for routing; no, for deciding sensitive cases |
| Retrieve evidence | Authorized and relevant sources | Permissions, currency, case match, and source logging | Yes, within the authorized scope |
| Draft | Evidence-based draft | Review of support, tone, disclosed data, and unverified claims | Only in low-impact cases |
| Execute | Change, closure, or external commitment | Authorization, rule validation, logging, and reversibility | Only for pre-authorized, bounded actions |
Case inventory and autonomy matrix
The next step is to build an inventory from real tickets, not idealized categories. An informational question about documented hours or features does not carry the same risk as a technical incident involving possible data loss. An account change may require identity and permission checks. A financial complaint may affect an invoice or refund. A security alert, a request for access to or deletion of data, and a message showing signs of serious harm require specialized routes.
For each case type, assess at least five dimensions: impact if the response is wrong; reversibility of the action; quality and currency of available evidence; certainty of classification; and acceptable response time. Urgency alone does not justify greater autonomy. In some cases, it requires faster escalation to a trained person or team precisely because the risk is higher.
The matrix should not operate as a score that conceals delicate decisions. Some categories are excluded from autonomous responses even when all other variables appear favorable. These commonly include refunds and other payments, cancellations with contractual consequences, material access changes, privacy, security, policy exceptions, service suspension, and communications containing threats, self-harm, harassment, or signs of critical frustration. The exact definition depends on the service and its obligations, but the exclusion must be explicit and testable.
In low-impact categories, an automated response is reasonable only when conditions are closed: the intent falls within a known set, evidence comes from a current source, no external action is required, there is no conflict between sources, and the response can be corrected without meaningful harm. If any of these conditions is missing, the system should abstain, ask a limited clarification question, or escalate.
Illustrative autonomy matrix
| Case type | Typical risk | Initial autonomy | Exit condition |
|---|---|---|---|
| Documented informational question | Low, if no account data is required | Bounded automated response | Current source, included case, and no conflict |
| Technical incident | Variable | Classification and draft | Escalate if there is data loss, security risk, or uncertain diagnosis |
| Account change | Medium or high | Guided intake and draft | Approval or identity verification according to the action |
| Financial complaint | High | Classification and context preparation | Human review before committing amounts or terms |
| Privacy or security | High | Priority routing | Authorized team; no substantive automated response |
| High-risk language | High | Alert and specialized route | Human intervention under the applicable protocol |
Design a verifiable ticket, not a conversational black box
Every case processed by AI should be reconstructable afterward. This does not mean retaining all content indefinitely. It means keeping the necessary and proportionate record to review a decision, investigate an incident, and improve the workflow. The record should distinguish what the customer said, what authorized systems provided, what the model inferred, what a person proposed, and the action ultimately executed.
A useful structure includes the case identifier; the original input and permitted attachments; the identity or verification status available to the agent, without exposing more information than necessary; the suggested category and route; retrieved sources with their version or effective date; the draft; applied validations; the approver, where applicable; and the final action. It is also useful to record the model version, high-level instructions, tools used, and the results returned by those tools.
Traceability does not make an incorrect decision correct, but it makes it possible to detect patterns: a policy retrieved incorrectly, a queue receiving cases that do not belong there, an integration carrying out an ambiguous action, or a category where declared confidence does not match real-world performance. It is also the foundation for stopping automation selectively rather than disabling the entire system.
Documentation should assign owners. Support may own the process and customer experience; quality may review samples and define resolution criteria; security and privacy may approve access and controls; product may maintain policies that affect features and plans; and the technical team may operate the model and its integrations. No team should assume that another team reviews the final effect unless that responsibility is explicitly defined.
Minimum record for an assisted resolution
- 01Retain the original request and identify which parts were sent to the system.
- 02Record the category, suggested queue, confidence level, and the reason for abstention, if it occurred.
- 03Record the permitted retrieved sources, their currency, and any detected conflict.
- 04Separate the AI draft from the reviewer’s edits and decision.
- 05Record validations, authorization, executed action, result, and available reversal mechanism.
- 06Apply a defined retention period and access controls to the record.
Evidence determines when to respond, abstain, or escalate
A knowledge base enables a response when it contains an instruction that applies to the case, is current, comes from an identifiable owner, and can be explained without adding unverified conditions. The system should not present as policy a summary that blends incompatible documents, nor should it turn a general recommendation into a specific guarantee for that customer.
The absence of evidence is operational information, not an invitation to improvise. If no applicable article exists, if a document is outdated, if two sources disagree, or if the history is insufficient to confirm a fact, the appropriate output may be a clarification question or a transfer. The draft should be able to state its limits clearly: what has been checked, what is missing, and which team will continue the review.
Retrieval must also be case-specific. An article about a standard plan may be irrelevant for a customer with different contractual terms. An account-status datum may have changed since the last contact. For this reason, evidence is not measured only by the number of documents found, but by their relevance, authority, and currency. Evidence coverage can become a metric: the proportion of automated responses that included sufficient support according to human review.
Under no circumstances should the conversation be used to extract or disclose data that the customer does not need in order to resolve the request. Responses should avoid internal details, third-party information, credentials, unnecessary identifiers, or explanations that make abuse of systems easier. When a customer requests an action that requires authentication, automation may direct them to the approved process, but it must not replace required verification.
Non-negotiable escalation rules and testing before deployment
Escalation rules should be implemented outside the model’s free-form text whenever possible. A classifier may suggest that a case concerns security, but a rule based on keywords, metadata, form type, or a tool result can add an independent barrier. If any of those signals appears, the workflow should direct the case to the appropriate queue and block actions incompatible with that route.
In addition to payments, cancellations, privacy, and security, include routes for policy exceptions, contractual commitments, possible discrimination, threats, compromised accounts, and high-risk language. The list should be reviewed with people who understand the real operation: agents, quality leads, legal teams where appropriate, security teams, and product owners. A case excluded from automation is not a system failure; it is a control decision.
Before sending automated responses, test the workflow using a frozen historical set. Keep this set separate from examples used to design instructions or tune rules. Include long conversations, incomplete messages, spelling mistakes, supported languages, multiple requests, context changes, conflicting sources, angry customers, and cases that resemble easy categories but contain an exception. Evaluate by segment, not only through an overall average.
Adversarial conversations do not need to involve sophisticated attacks. It is enough to test what happens when a customer asks the assistant to ignore procedures, inserts instructions in an attachment, requests another person’s data, or combines an informational question with a sensitive action. The system must treat that content as part of the request, not as operational instructions capable of changing its rules. Testing should confirm that the separation between customer text, internal policies, tools, and authorizations is maintained.
Gradual rollout with reversal conditions
- 01Begin in draft mode: an agent reviews and edits every proposed response.
- 02Enable classification suggestions and measure routing accuracy against samples reviewed by specialists.
- 03Allow automated responses only in a closed category, with no external action and sufficient evidence.
- 04Review errors, reopenings, transfers, complaints, and missed escalation cases daily during the initial phase.
- 05Define thresholds before launch for pausing or reversing automation by category.
- 06Expand scope only if results hold by segment and incidents are investigated and corrected.
Measure correct resolution, not just speed
The dashboard should compare the assisted workflow with a baseline process and break results down by case type, channel, language, product, and queue when those cuts are relevant and permitted. An aggregate indicator can conceal that the system performs well for simple questions and poorly for account changes or financial complaints. The decision to expand autonomy should rest on that level of detail.
Routing accuracy measures whether the ticket reaches the queue that an expert review would have selected. Correct resolution evaluates whether the response and final action resolved the case according to defined quality criteria. Reopening and transfer rates reveal whether a seemingly fast response left work to later contacts. SLA compliance shows whether automation shortens or lengthens the time until appropriate assistance, not merely the time until the first message.
Add safety and evidence metrics: the proportion of responses with a relevant and current source; the frequency of justified abstentions; incidents of improper data access or disclosure; the percentage of actions blocked by an escalation rule; and harm from incorrect resolution. This last indicator requires an agreed taxonomy, such as minor correctable inconvenience, financial harm, data exposure, breach of commitment, or security impact. These cases should not be hidden inside a single satisfaction metric.
Cost per case can inform operational decisions, but it should not automatically offset an increase in serious errors. Customer satisfaction provides a useful signal, although it is not sufficient on its own: a person may value the speed of a response that later proves incorrect. Human review of samples, incident investigation, and the ability to reconstruct each case complement perception metrics.
Metrics and the decisions they support
| Metric | Question it answers | Warning signal |
|---|---|---|
| Routing accuracy | Does the case reach the right queue? | Decline in sensitive or minority categories |
| Correct resolution | Did the response and action resolve the case? | Gap between speed and reviewed quality |
| Reopenings and transfers | Was work shifted to later contacts? | Increase after automated response is activated |
| Evidence coverage | Is the response supported by relevant sources? | Outdated, missing, or conflicting sources |
| SLA to appropriate assistance | Did the customer receive useful help in time? | Fast first response but late escalation |
| Harm from error | What consequences did failures have? | Any serious incident requires immediate review |
Checklist for approving or stopping support automation
Approve an automation only if you can describe its scope precisely: included categories, authorized sources, excluded data, permitted actions, owners, and escalation conditions. If the team cannot explain what the system does when a source is missing, confidence is low, a request falls outside policy, or a tool returns an ambiguous result, the workflow is not yet ready to operate autonomously.
There must also be a simple mechanism for agents and quality leads to correct a classification, flag an incorrect source, and stop an automated response by category. Correction should feed a process review, not become a silent exception. Changes to policies, products, prices, or contractual terms require a review of retrievable articles and, where appropriate, renewed testing of the automation.
Stop or reduce scope if serious errors occur, if reopenings or transfers exceed the defined threshold, if evidence coverage declines, if the ticket profile changes, or if the required traceability cannot be maintained. Reversal is a design capability: it must be possible to return a category to draft mode without interrupting customer support.
Support automation is more controllable when it begins with tasks that reduce administrative workload without replacing high-impact decisions. Classification, evidence retrieval, and draft writing can provide value when clear limits are maintained. Executing a resolution concerning a person’s account, money, data, or rights requires a proportionate level of control. To decide which level applies in each case, connect this guide with use-case selection criteria, safety controls, and the assessment of automation costs and scope.
Open questions
- The categories requiring human approval and reversal thresholds depend on the service, applicable obligations, connected systems, and each organization’s risk tolerance.
- This guide does not determine which identity checks, retention periods, or legal workflows are required in a particular jurisdiction or sector.
- A model’s stated high confidence does not necessarily equal accuracy; it must be validated with representative samples and specialist review.
- The availability, currency, and authority of the knowledge base must be verified in each organization before automated responses are enabled.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction