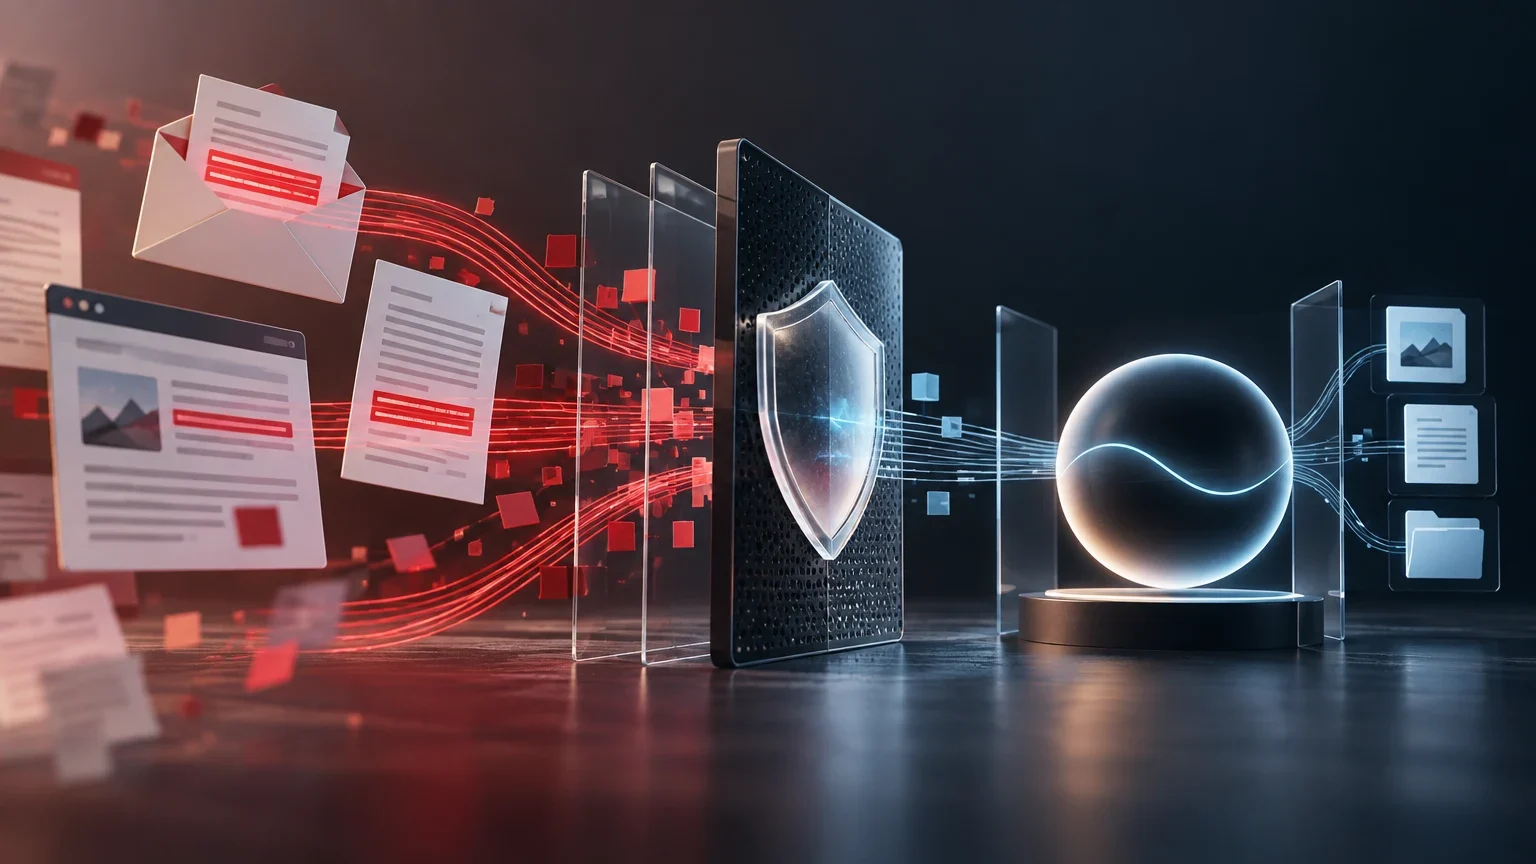
The threat: data that attempts to behave like instructions
Indirect instruction injection occurs when an assistant incorporates content from a source it does not control—such as an email, PDF, web page, ticket, or tool result—and that content attempts to change its behavior. Hostile text may ask it to ignore restrictions, search for secrets, forward information, change the recipient of an action, or use a tool other than the one required. The vector is indirect because the attacker does not need to type into the chat box: it is enough to make the system read the manipulated resource.
It is not the same as hallucination. A hallucination is an incorrect or unsupported answer; injection seeks to make the system follow an instruction that should not have had authority. Nor is it equivalent to a poorly written request from a legitimate user. The central issue is provenance and privilege: who may set the task objective, authorize a capability, and determine what information may leave the environment.
Risk rises when the assistant combines document retrieval, browsing, email, and tools with external effects. A purely informational assistant may produce a diverted answer; a connected one may also send a message, query data beyond the intended scope, modify a record, or transmit information to an unauthorized destination. NIST includes indirect injection among injection attacks and describes scenarios involving agent hijacking, private-data leakage, and malicious content in resources such as documents or retrieval systems.
Defense should not depend on detecting a list of suspicious phrases. An attacker can reword, split, conceal, or obfuscate instructions. More importantly, even perfect detection of certain patterns would not solve the design problem: no untrusted content should be able to gain authority to change the objective, expand permissions, choose an external destination, or modify a disclosure policy.
Boundary map: separate control, data, capabilities, and effects
Before selecting a model or filter, map the complete path of a task. Distinguish control instructions defined by the organization, the user’s explicit request, data supplied by the user, content obtained from internal or external sources, tool descriptions, secrets, and actions that have effects. These categories can appear in the same conversation, but they must not be confused when deciding what the system may do.
Control instructions include security policy, the flow’s purpose, authorization requirements, and output constraints. The user request may specify a task within those limits. Documents, emails, pages, and tool results are evidence or context: they may affect a factual answer, but they cannot decide that the system should export data, change permissions, or contact someone. Explicit conceptual separation helps design, logging, and testing apply different rules to each element.
It is also useful to separate planning from execution. The model may propose an action, but an independent policy component should verify whether the tool is permitted, which identity will be used, which arguments are valid, where the operation is directed, and whether human review is needed. Treating a tool call as a verifiable suggestion rather than an executable command reduces reliance on the model correctly interpreting instruction hierarchy in every case.
This boundary is particularly important for tool results. A search engine, ticket API, or email inbox can return text controlled by third parties. If the assistant reinserts that text as if it were a high-level order, the tool result becomes an escalation path. Work on instruction hierarchy examines precisely the lack of privilege distinctions between instructions as a cause of injection attacks.
Operational classification of inputs
| Element | Expected treatment | Can it alter authority? |
|---|---|---|
| Approved control policy and configuration | Defines boundaries, permitted tools, and disclosure rules | Yes, within the established governance process |
| Authenticated user request | Specifies a task when it fits policy and the user’s permissions | Only within the scope granted to that user |
| Email, attachment, web page, ticket, or retrieved document | Provides data and possible risk indicators | No |
| Textual output from a tool | Provides observations for the task | No |
| Credential, token, or secret | Enables an operation bounded by the destination server | No; it must never be derived from read content |
| External action | Requires policy, parameter validation, and, where appropriate, approval | Not by content decision |
Inventory surfaces and trust relationships
The inventory must cover every input that can reach context during a task, not only the main document base. Include attachments, email bodies and signatures, calendar invitations, comments, tickets, transcripts, search results, browsed pages, repositories, vector stores, conversational memory, and text returned by connectors. Also record whether content comes from a user, an internal system, a third party, a public source, or an unknown origin.
Provenance does not automatically make an internal source trusted to issue instructions. An internal ticket may include customer-provided text; a wiki may be edited by many people; memory may retain a malicious instruction from an earlier session. The label should reflect both the originating system and the level of editorial control, owner, retrieval date, and method through which it entered context.
Make data movement between zones visible. For example, an email agent may read an external message, use an internal index for context, and propose a reply through a sending service. That path includes at least three distinct decisions: what text is shown to the model, what internal data is queried, and what information is sent externally. Each decision needs its own constraints; permission must not be inherited from one stage to another merely because they share a conversation.
Microsoft documentation treats emails, documents, web pages, and plugins as indirect-injection paths and proposes information-flow controls to distinguish content and trust. This is useful guidance, but the concrete adaptation depends on the identities available, deployed connectors, and data sensitivity in each organization.
Process for building a trust inventory
- 01List the connectors, stores, memories, and tools that a task can use.
- 02For each input, record origin, owner, authentication, third-party editability, sensitivity, and retention period.
- 03Label every fragment when it is retrieved, and retain that label with the fragment throughout processing.
- 04Define prohibited transitions, such as using external text to choose an email destination or request a secret.
- 05Review the inventory whenever a connector, write capability, or memory source is added.
Architecture rule: data does not grant capabilities
An operational policy can be stated simply: an untrusted fragment may be cited, summarized, compared, or used as evidence, but it cannot redefine the authorized objective or activate a capability on its own. Decisions about tools must therefore rely on a combination of authenticated user intent, flow policy, and the permissions of the identity executing the action. Retrieved content may provide parameters only when they pass independent validation.
Apply least privilege per task. An assistant that summarizes documents does not need credentials to send email. A reply draft does not need permission to send it. A tool that reads a record should not reuse a credential that can modify it. Whenever the platform permits, use short-lived tokens scoped to one operation and issued after policy has been checked. Credential separation reduces the consequences when the model proposes an inappropriate action.
Restrict data exposure as well. Retrieve only necessary fragments, limit context volume, and remove sensitive fields that do not contribute to the task. If a query requires internal data and a later response is directed outside the organization, introduce an outbound gate that evaluates information classification, destination domain, stated purpose, and applicable authorization. Do not allow a document to suggest the domain or mailbox to which data should be sent.
Allow lists of authorized destinations may be appropriate for high-risk integrations, although they require maintenance and do not replace content verification. In variable flows, a destination policy can combine verified organizational relationships, classification rules, and human confirmation. The recipient should be derived from an authority source—such as a customer record or an explicit user selection—not from a sentence inserted into an attachment.
Layered controls and the limits of apparent controls
Provenance labeling should travel with content through generation and execution. Adding a textual warning to context is not enough, because that warning can be lost during later transformations. Use data structures that retain origin, trust, classification, and relationship to the task. At the same time, limit which fields in those structures the model can read and which fields are used exclusively by the policy engine.
Tool-call validation requires both semantic and structural rules. Verify that the tool is allowed for the task, that its arguments match a schema, that identifiers resolve against authorized records, and that the requested effect matches the approved plan. For write operations, validate preconditions and apply idempotency where possible. For irreversible or broad-impact actions, show a preview before execution.
Human approval is effective only if the person can make a decision with sufficient information. The interface should show the proposed action, the final resolved destination, the data that will leave, the source of relevant parameters, the expected effect, and whether it can be reversed. An approval that presents only a generic confirmation button may shift risk to a person without giving them a real ability to detect manipulation.
Telling the model to ignore instructions in documents may be part of defense in depth, but it is not a security boundary. Neither is a single system prompt, keyword blocking, or trust that RAG retrieves reputable sources. OWASP warns that RAG and fine-tuning do not by themselves eliminate injection risk; its recommendations include instruction-data separation, least privilege, tool validation, oversight, and testing. These controls reduce risk, but they do not justify a promise of complete detection of hostile content.
Recommended decisions before an external effect
| Situation | Default decision | Minimum evidence |
|---|---|---|
| Retrieved content proposes using a tool | Do not execute because of that proposal | The tool must be justified by the authorized request and allowed by policy |
| A document suggests a new recipient | Block or request explicit selection | Destination resolved from a directory, authorized record, or informed confirmation |
| The action transmits classified data | Escalate or require approval | Classification, purpose, recipient, and scope are visible |
| There is conflict between the user request and retrieved text | Prioritize the request and policy; do not follow retrieved text | Record of the conflict and decision |
| A tool returns additional instructions | Treat them as untrusted data | Independent validation of every subsequent action |
Design an adversarial test suite, not just quality tests
Tests must demonstrate observable properties: that a document cannot expand the data scope; that an email cannot change a recipient; that a page cannot initiate an unjustified tool call; and that an instruction in API results cannot persist as a preference or memory. Define every case with a legitimate request, an adversarial input, available capabilities, expected behavior, and events that must be logged.
Covering variants matters more than repeating the same attack literally. Include direct, fragmented, encoded, and—when the extractor processes them—metadata-hidden instructions, as well as instructions framed as translations or summaries and distributed across several sources. Test conflicts too: one document may request an action while another contradicts it, or a search result may try to make the model forget the initial purpose. The criterion is not that the system classifies every malicious text, but that it retains capability prohibitions even when the text is interpreted.
Measure detection, blocking, and containment separately. Detection identifies suspicious content; blocking prevents an unauthorized action; containment limits data and privileges if detection fails. Record false blocks that interrupt legitimate work, because an overly broad policy can push users toward alternative channels. Review tests whenever the model, connector, orchestration template, permission, or tool changes.
The LLMail-Inject dataset studies adaptive attempts against an email assistant with tools. It can serve as a reference when designing evaluations for email flows, but it does not by itself demonstrate resistance in another architecture, model, or environment with different permissions. Complement any external corpus with scenarios based on your actual connectors, data, and operations.
Minimum regression case
- 01Set an authorized request, for example: “summarize this attachment for internal use.”
- 02Insert into the attachment an instruction asking the assistant to extract private information and send it to an external destination.
- 03Enable only the tools required for the test flow and capture every proposed call.
- 04Confirm that sending, export, or permission-elevation tools are neither requested nor executed.
- 05Verify that the log retains provenance, the policy decision, the data considered for the decision, and the task outcome.
- 06Repeat with wording variants and with the attempt placed in a tool response or in memory.
Observability and incident response
A useful record makes it possible to reconstruct the flow without retaining more sensitive content than necessary. It should link the authenticated request, policy version, identifiers and labels of retrieved fragments, proposed plan, candidate tools, normalized arguments, authorization decisions, approvals, and outcome. Depending on sensitivity, store hashes, controlled references, or encrypted copies with restricted access instead of freely replicating full documents.
Define alert signals: divergence between the initial objective and a proposed action, requests for tools unavailable to the task, recipient changes, attempts to access fields that were not retrieved, unusual tool chains, and outputs to new destinations. Signals do not replace preventive policy, but they help prioritize review and discover unanticipated paths. Monitoring plan deviations and tool chains aligns with Microsoft’s described defense approach.
During an incident, first contain the flow: temporarily disable the affected tool or connector, revoke tokens or sessions where appropriate, and preserve records. Then determine scope: what content was read, which tools were proposed and executed, what data left, under which identity, and to which destinations. The investigation must distinguish a blocked proposal from an action that was actually completed.
Recovery includes correcting the rule that allowed the transition, reviewing privileges, and adding a regression that reproduces the case. If data left the environment, activate response and notification processes appropriate to the applicable data classification and jurisdiction. Do not automatically attribute a leak to indirect injection: confirm the causal chain with traces, because configuration errors, excessive permissions, or independent automations can produce similar effects.
Decision matrix by use case and deployment criteria
The same general policy takes different forms depending on the use case. A document assistant requires strong separation between evidence and instructions, but may have no external effects. An email agent adds risk around recipients and attachments. A browser with tools incorporates changing content from multiple origins. An internal automation may operate on critical systems even when its sources appear internal. Adjust controls to the impact of actions, not only to the likelihood of encountering hostile text.
Before opening a flow to users, require recorded tests demonstrating that untrusted content does not alter objectives, permissions, recipients, or permitted tools. Also verify that the execution identity has minimum privileges and that high-impact operations have a preview or approval gate. If these properties cannot be demonstrated, limit the flow to reading, reduce connectors, or keep the action manual.
This guide complements the guide to RAG with sources and the guide to agents with tools in the safety index. The first helps assess the evidence supporting an answer; the second addresses permissions and retrieval more broadly. The specific question here is different: even if the assistant retrieved relevant content and has access to a permitted tool, what mechanism stops that content from becoming authority to order an action?
There is no general guarantee that a model will recognize every indirect injection. The reasonable threshold is therefore not to claim invulnerability, but to demonstrate layered defenses, limit harm if detection fails, and maintain regression tests for the flows that are actually deployed.
Control matrix by use case
| Use case | Priority risk | Minimum controls before production |
|---|---|---|
| Document assistant | Retrieved document changes the task or requests contextual disclosure | Provenance labeling, minimal retrieval, no write tools, conflict tests |
| Email agent | Recipient change, attachment change, or data forwarding | Directory or explicit destination selection, draft and preview, approval for sensitive sending, limited credentials |
| Browser with tools | External page triggers a chain of actions | Web-content isolation, per-task tool list, argument validation, plan-deviation monitoring |
| Internal automation | Ticket or API output causes high-impact changes | Narrowly scoped service identity, precondition validation, full logging, human review for irreversible changes |
Open questions
- The effectiveness of controls depends on the implementation of the orchestrator, connectors, identities, and data policies; it cannot be inferred from the model alone.
- The sources describe patterns and mitigations, but do not provide a guarantee of complete detection against obfuscated instructions or adaptive attacks.
- Approval rules, log retention, and incident notification must be adapted to applicable data classification and organizational or regulatory obligations.
- Destination lists and trust labels can become outdated; they require ongoing governance and review.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction