What changes with Agent Lightning
Microsoft Research presents Agent Lightning v1.0 as a framework for training AI agents with reinforcement learning without rebuilding their logic inside the training system. The idea is to keep the agent that already performs tasks—including its steps, tools, and context management—and connect it to training infrastructure through a proxy for model calls.
The project aims to address a common divide between development and training: agent frameworks organize interactions with tools and other agents, while reinforcement-learning systems handle model optimization. If an agent has to be reimplemented for training, that version may behave differently from the one used in production. Agent Lightning is designed to let training observe the agent’s behavior within its own workflow.
Version 1.0 represents a rebuild of the project compared with earlier releases. The repository describes it as a lightweight implementation and publishes the code under the MIT License. The approximate figure of 3,500 lines, along with the benefits attributed to that simplicity, comes from the project team; it is not an independent measure of ease of use or total adoption cost.
How it connects agents and training
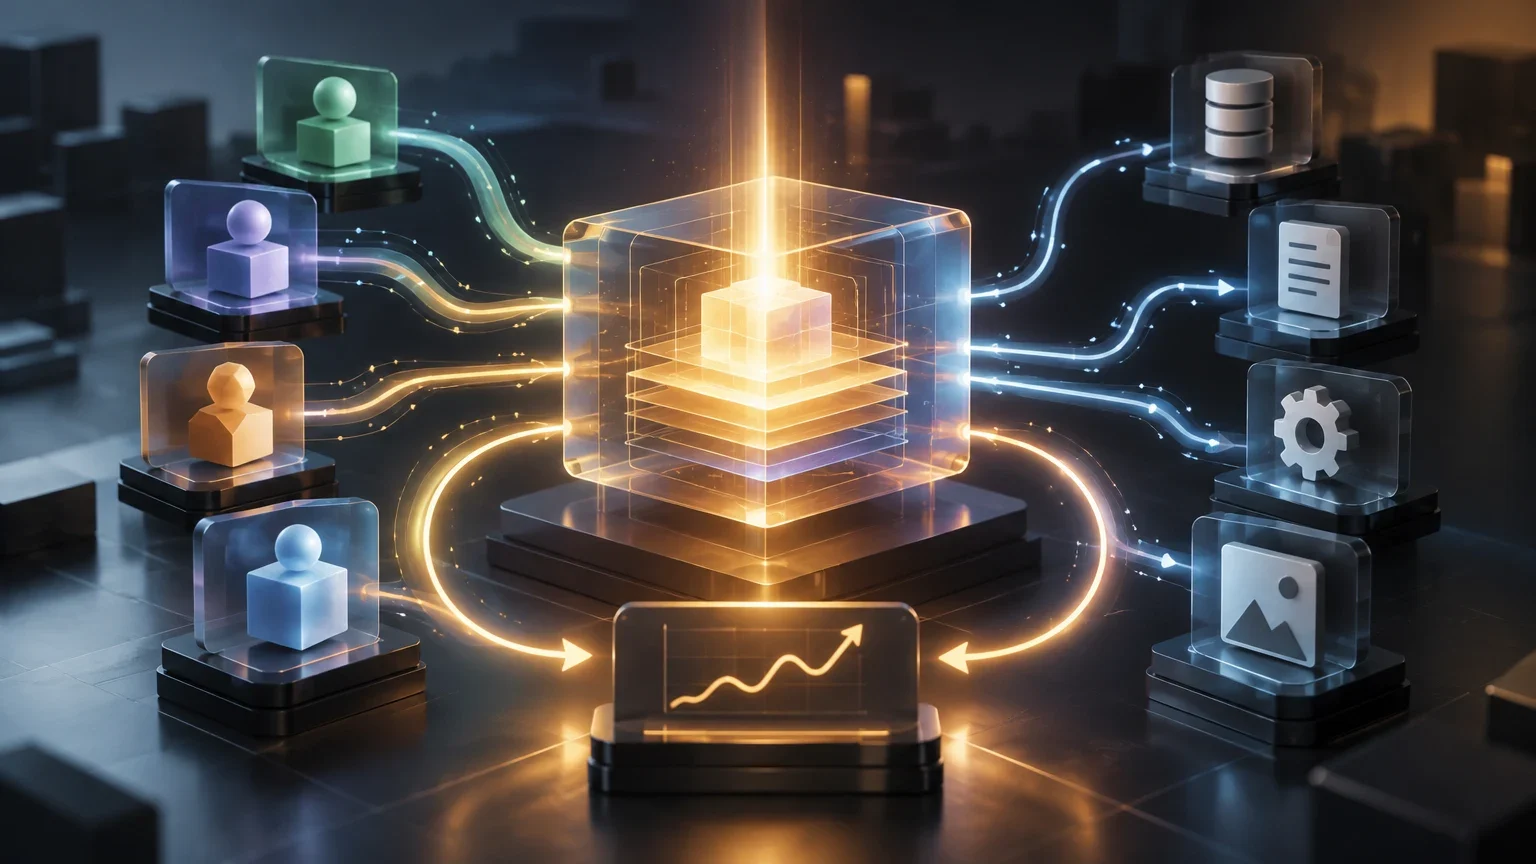
In the architecture described, an Agent Lightning server and client sit between the agent and the training system. For version 1.0, the repository identifies three main components: a trainer built on verl, an API Gateway that acts as an OpenAI-compatible API proxy and collects data, and a rollout controller that starts agents locally or as Kubernetes jobs.
The agent sends its model requests through the Gateway. The Gateway links calls to the corresponding rollout and records information needed to create training data, such as requests, responses, and the probabilities associated with generation. The controller manages agent execution, while the trainer organizes samples and updates the model policy. This separation allows agent logic and training logic to evolve as distinct components.
The described workflow starts with tasks and agent rollouts. During execution, it records interactions, errors, and reward signals, which can be configured to reflect whether a task succeeds or fails. The traces are then converted into data the training system can use. Microsoft Research describes using reinforcement-learning algorithms, including GRPO in the verl-based workflow; this does not mean that every algorithm or configuration is built in by default.
The project says it currently supports OpenAI Agents SDK, LangChain, and AutoGen. This list should be understood as compatibility documented by the project itself, not a guarantee that any agent built with these frameworks will connect without adjustments. Changing endpoints, managing credentials, matching request formats, and handling agent dependencies may require integration work.
Described training workflow
- 01The controller starts a task and runs the agent using its usual workflow.
- 02The agent routes model requests through the Agent Lightning Gateway.
- 03The Gateway records interactions and configured signals; the system organizes the traces into training samples.
- 04The trainer updates the model, after which the agent can run again with the updated policy.
What it means to train with the real harness
The harness is the layer that coordinates an agent’s behavior around the model. It may manage context, conversation history, memory, tools, step ordering, and interactions with other agents or an environment. Agent Lightning’s proposal is to keep that harness involved during training instead of replacing it with a simplified loop controlled entirely by the reinforcement-learning system.
In practical terms, the requests the agent already sends to the model pass through the proxy. That allows the agent to keep its tools, control logic, and environments while the system collects interactions relevant to training. Microsoft Research says this design avoids changing agent code in the cases covered by its architecture; the repository also describes the promise as running agents with zero changes. These are descriptions of the design, not evidence that every real-world integration literally requires no changes.
Keeping the harness also introduces technical challenges. A single task can generate multiple model calls, and each call may become a separate sample. The agent keeps context as text, while training may need the token IDs originally generated. Tokenizing the text again can shift token boundaries; summarizing context or delegating to subagents can also split a trajectory in different ways. The team also identifies challenges in calculating advantages and normalizing losses at the trajectory level, as well as mapping variable workloads to GPUs configured in advance.
Version 1.0 describes a shared-resource asynchronous training mode: rollouts are collected, new requests are temporarily paused while requests already in progress finish, the model is updated, and rollouts then resume. Microsoft Research reports an approximately twofold speedup over a synchronous setup in its experiments. That figure applies to the conditions tested by the team; it does not establish the speed an agent, hardware configuration, or workload will achieve in other settings.
Available code, compatibility, and getting started
The official repository publishes Agent Lightning v1.0 under the MIT License and provides documentation, examples, and scripts. Listed examples include math tasks using AutoGen and MCP tools, GSM8K, ScienceWorld, search and reasoning, code execution in a sandboxed environment, and a coding agent. The presence of a documented example does not mean the project guarantees support for every configuration of that environment.
The repository’s reference installation uses a machine with CUDA 13.0, synchronizes dependencies with uv, and runs a script to set up verl with the specified version and CUDA variant. This should not be read as a universal installation process or proof that the complete workflow will run on a computer without a compatible GPU. Before reproducing results, check the current installation guide, dependency versions, accelerator availability, and the requirements for each example.
Running agents as standard Kubernetes jobs is a highlighted capability of v1.0. Local execution is also supported. Kubernetes can make use of self-managed infrastructure or compatible services, but operating the cluster, resources, images, and job security remains the user’s responsibility. The claim that this option avoids reliance on commercial sandbox services describes an architectural possibility; it does not mean that large-scale training has no operating costs.
The figure of about 3,500 lines appears in both the project description and the institutional announcement. The available material does not provide an independent counting method—for example, which directories, generated files, or dependencies are included—so it is best treated as an approximate figure from the team rather than an objective comparison of complexity across frameworks.
What to check before choosing a setup
| Need | What is documented | What to verify in practice |
|---|---|---|
| Connect an existing agent | An OpenAI-compatible API proxy; stated compatibility with OpenAI Agents SDK, LangChain, and AutoGen. | Endpoint, authentication, request format, dependencies, and changes needed to the agent. |
| Train with verl | The v1.0 trainer is built on verl, and the project describes workflows using reinforcement-learning algorithms. | Compatible versions, the specific algorithm, GPU configuration, and how rewards are defined. |
| Run on Kubernetes | The controller can launch agents as standard Kubernetes jobs. | Permissions, resources per job, image management, isolation, and cluster costs. |
| Test locally | The repository includes examples and an installation path for CUDA 13.0. | Hardware compatibility, software versions, and requirements specific to each example. |
Published results and what remains to be tested
Microsoft Research presents a coding example using Qwen3.5-9B, mini-SWE-agent, and SWE-smith. The team reports that after reinforcement-learning training on approximately 6,000 samples, the result on SWE-bench Verified rose from 41.8% to 56.4% in Pass@1, a difference of 14.6 percentage points. The figure describes that experiment and setup; it does not show that Agent Lightning will produce the same improvement with other models, agents, or task sets.
The repository also reports a later example with Qwen3.5-35B-A3B: a rise from 47.8% to 61.6% on SWE-bench Verified after training on 1,800 examples, according to the project. These results were reported by the system’s authors and should be attributed accordingly. The supplied sources do not include an independent evaluation reproducing the figures or a controlled comparison that isolates the framework’s contribution from other training factors.
Assessing broader usefulness would require reproductions with sufficient detail about versions, data, compute budget, model configuration, rewards, and evaluation protocol; comparisons with untrained agents and other methods; and tests across more tasks and environments. It would also be useful to measure integration time and cost, run-to-run stability, agent failures, and sensitivity to incorrect rewards. The technical material itself acknowledges challenges such as assigning credit across steps and handling samples from trajectories of different lengths.
The verifiable conclusion is narrower than a promise of universal improvement: Agent Lightning v1.0 offers an open architecture intended to connect existing agents to reinforcement-learning training while retaining their harness, and it publishes its own examples and results. Whether the approach reduces integration work or improves a particular agent needs to be evaluated case by case against a baseline and under documented conditions.
Practical criteria for an initial evaluation
A useful test starts with a well-scoped task and an agent that already works with its usual harness. Before training, set a success metric, an untrained baseline, and an evaluation set separate from the data used for optimization. If rewards depend on automated tests, check that the tests measure the intended outcome and cannot be passed through shortcuts.
Next, measure the effort required to connect the agent to the proxy, the changes needed, and whether the traces capture relevant decisions. Record execution failures, GPU and CPU use, iteration duration, and the stability of improvements as well. A result that appears only on training examples or depends on a fragile setup needs further validation.
The MIT License makes the code available for inspection and adaptation, but it does not replace security and dependency reviews or checks on the terms that apply to the models and data in use. Adoption should be based on specific compatibility, the ability to operate the infrastructure, and a reproducible comparison—not just the line count or improvements reported by the team.
Short evaluation checklist
- 01Choose an agent and task with an existing, reproducible baseline.
- 02Check endpoint compatibility, dependencies, hardware, and execution method.
- 03Define rewards and a separate evaluation before starting training.
- 04Record integration changes, costs, failures, and results across multiple runs.
- 05Compare against alternatives and describe improvements that have not been independently reproduced as provisional.
Open questions
- The figure of about 3,500 lines is approximate and comes from the project; no independent counting method is specified.
- The SWE-bench Verified results are experimental claims by Microsoft Research and the project repository; the supplied sources contain no independent reproduction.
- Stated compatibility with certain frameworks does not guarantee integration without changes for every agent or version.
- The reference installation uses CUDA 13.0 and a specific verl setup; requirements may differ depending on hardware, dependencies, and examples.
- The approximately twofold speedup over synchronous training applies to the reported experimental conditions and does not establish performance on other workloads.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction