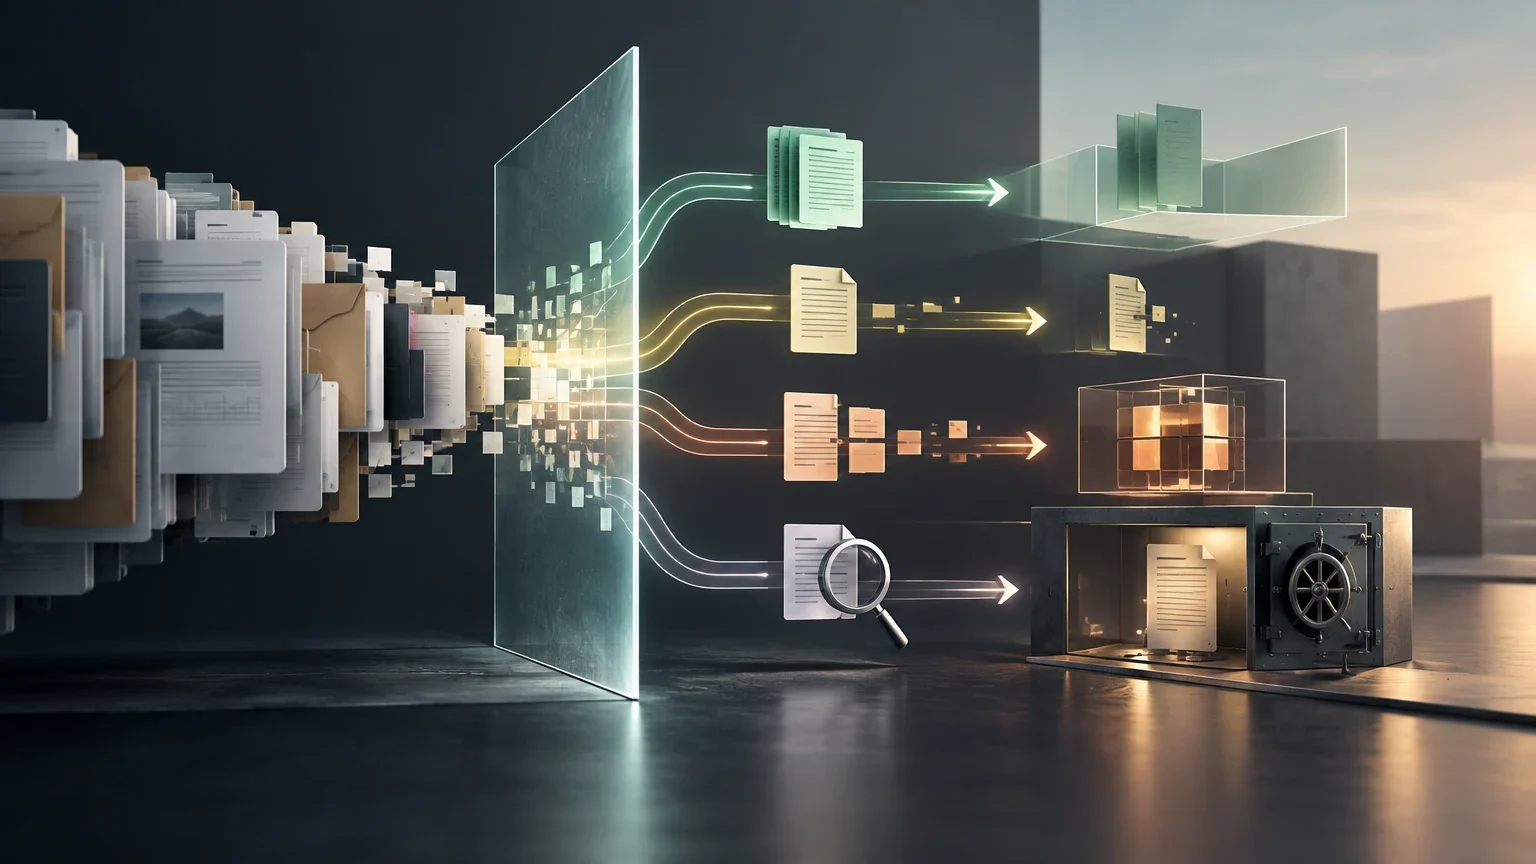
The decision is not simply “private document: yes or no”
A contract, an HR case file, an engineering report, or a client file may contain information with very different sensitivity levels. An internal search does not create the same risk as extracting fields to prefill a screen, producing a summary to guide an analyst, or assigning a classification that triggers an operational consequence. The first useful decision, therefore, is not whether to choose an external API or a model running on infrastructure you operate. It is to describe the transformation to be performed, the data involved, who will receive the result, and what happens if that result is wrong or disclosed.
The General Data Protection Regulation establishes principles of purpose limitation, data minimization, storage limitation, and data protection by design and by default. In an AI workflow, those principles require a justification for including each part of a document and each associated data item. It is not enough that the document is available to the team or that a contractual relationship exists with a provider: the specific workflow must have a defined purpose, relevant data, and controls proportionate to the risk.
It is useful to keep two layers separate. The first is factual: which text, files, metadata, instructions, and logs move through the system. The second concerns decisions: which use is permitted for each output, and which person or process takes responsibility for validation. This separation prevents a technical capability, such as producing a summary, from being confused with authorization to use that summary when deciding about a person, a contractual obligation, or an operation.
The initial question can be framed as follows: what is the subsequent action, is it reversible, and what would the impact of an error be? An answer that only helps locate a clause may require different controls from an output that changes a case file, rejects a request, prioritizes an investigation, or becomes part of an external communication. Reversibility does not eliminate risk, but it helps set the level of review and the stop conditions.
Variables to decide before selecting an environment
| Variable | Operational question | Typical consequence |
|---|---|---|
| Purpose | Search, summarize, extract, classify, or draft? | Defines the minimum content needed and the type of validation. |
| Sensitivity | Does it include personal data, trade secrets, credentials, health information, or employment information? | Increases the need to segment, restrict access, or change the environment. |
| Re-identification | Can fragments, dates, job titles, or project names attribute the content to someone? | Prevents treating the removal of names alone as sufficient anonymization. |
| Impact of error | Can the output affect rights, contracts, payments, safety, or operations? | Requires usage limits and, frequently, human review. |
| Reversibility | Can an action be corrected before it has consequences? | Guides the automation threshold and the level of prior testing. |
Build a minimum inventory of the workflow, not only of the original file
The original document is only one component. A scan may go through optical character recognition; the extracted text may retain headers, notes, tables, and reading errors; and an application may add instructions, prior search results, attachments, and user metadata. The request may then produce technical traces, metrics, temporary copies, audit logs, and an output that another system stores or forwards. An inventory that lists only the PDF cannot assess the real exposure.
For each component, record its source, owner or responsible business area, classification, location, technical recipients, retention period, and potential for human access. Include the text inserted into instructions, passages retrieved from an index, tools called by the model, and observability systems. Logs may be necessary for incident investigation, but they can also replicate sensitive information; they should be designed using the same minimization criterion as the main request.
NIST recommends managing generative AI risks through governance, mapping, measurement, and management. Applied here, the inventory is not an isolated administrative task: it makes it possible to identify which components must be assessed, who controls each stage, and what evidence can reconstruct how an output was produced. It also makes material changes easier to detect, such as a new OCR version, a different model, an additional connector, or a change in the retention policy.
Classification should be specific. “Confidential” may be a useful label, but it does not distinguish between a technical secret, contact data, a performance assessment, health information, or a document containing several of these categories. Classify attachments and metadata as well. A file name, internal path, case identifier, date, or project name can reveal as much as a paragraph in the body text.
Operational inventory in seven steps
- 01Identify the original, its attachments, its versions, and its provenance.
- 02Describe the transformations: OCR, cleanup, chunking, indexing, pseudonymization, and translation where applicable.
- 03List instructions, retrieved context, tools, model, and destination for each request.
- 04Classify text, images, tables, metadata, and logs separately.
- 05Assign a technical owner and an owner of the usage decision for every stage.
- 06Define retention, deletion, and authorized access for every copy or representation.
- 07Version the workflow and retain evidence of testing before authorizing production.
Four processing patterns and the criterion for choosing between them
Direct processing with controls may be proportionate when the purpose requires the full content, access is limited, the environment is authorized for that category of information, and the output does not independently trigger a material consequence. Controls are not an afterthought: they include authentication, role-based permissions, encryption in transit and at rest where appropriate, retention settings, environment separation, access logging, and testing that shows the application does not add unnecessary data to the request.
Prior minimization or pseudonymization seeks to reduce exposure before processing. It may involve removing irrelevant columns, replacing identifiers with references, excluding contact data, or providing only the required fields. Pseudonymization can reduce the impact of an exposure, but it is not necessarily equivalent to anonymization. The European Data Protection Board guidelines, published for public consultation, emphasize that additional information, quasi-identifiers, and context matter when assessing the possibility of attribution or re-identification.
Segmentation and selective submission are appropriate when the task can work with a section, a table, or specific fields. For example, locating a contract renewal date may not require sending commercial annexes, signatures, bank details, or the rest of the case file. However, splitting a document does not guarantee isolation: several fragments, a stable identifier, or accumulated queries may disclose the context that the workflow was meant to limit.
Processing in a controlled environment becomes relevant when information cannot leave a defined perimeter, when the complete document is needed, when the risk of re-identification remains high, or when an output has high impact. This pattern may involve self-operated infrastructure or an environment with specific technical and organizational boundaries, but its name alone does not demonstrate that it is suitable. Settings, access, retention, connected components, and auditability must be verified. The guide to local models may help assess the technical implications of operating components within your own infrastructure; it does not replace workflow analysis or remove the risks created by permissions, logs, or integrations.
Apply a decision tree according to the purpose
Search often supports a different architecture from classification. In search, the goal may be to return candidate documents or passages; the result should not be presented as a definitive answer if retrieval may be incomplete. For summarization, define the audience, length, facts that must be preserved, and prohibitions: a summary may omit relevant exceptions, conditions, or discrepancies. For structured extraction, define the field schema, the textual evidence supporting each value, and the handling of absence, ambiguity, or conflict.
For classification, specify which class is assigned, which signals are allowed, and what happens in borderline cases. A priority, risk, or status label can shape subsequent work even if it is not a final decision. For drafts, determine which sections the system may write, which information it must not invent, and who reviews tone, accuracy, recipient, and included data before sending or publishing.
A practical criterion is to check whether the purpose requires the full document. If it does not, reduce the content. If it requires the full content but the output is informational and reviewable, consider an authorized environment with access controls and logging. If the result can produce a material consequence or is difficult to correct, do not turn the output into an automatic action without a specific assessment, a clear validation condition, and mechanisms to stop the workflow.
Tool selection should not be confused with this classification. An OCR model may be useful to obtain text from a scan, and a lightweight model may support a bounded classification task, but both are part of a system that also includes storage, permissions, instructions, logs, and subsequent use. In particular, integrating Mistral OCR 4.1 or Amazon Nova 2 Lite does not by itself establish which data are authorized, which retention applies, or whether the output is suitable for a decision. Those questions must be verified in the configuration and in the workflow documentation.
Indicative decision by purpose
| Purpose | Preferred initial representation | Use of the output | Stop condition |
|---|---|---|---|
| Search | Relevant fragments with minimal metadata | Assistance in locating the original | There is insufficient evidence or the index may be incomplete. |
| Summarization | Necessary sections and coverage rules | Reviewable informational draft | Sections are missing, contradictions exist, or the document requires literal precision. |
| Extraction | Relevant fields or pages plus textual evidence | Prefill subject to validation | The value is ambiguous, absent, inconsistent, or outside the expected format. |
| Classification | Necessary attributes and defined classes | Controlled prioritization or routing | The case is borderline, the impact is high, or the signal is insufficient. |
| Drafting | Validated facts and an authorized template | Text pending approval | It includes unsupported assertions, sensitive recipients, or excessive data. |
Minimization does not remove the risk of re-identification or inference
Removing names, addresses, or identification numbers can be useful, but it is not enough to conclude that content is anonymous. A combination of role, date, location, amount, described incident, supplier, and project name may indirectly identify a person or disclose a specific negotiation. Additional information may exist within the same system, in a correspondence table, or even in knowledge available to people receiving the result.
There are also inferred data. A summary of absences, a risk classification, or an extraction of conditions may reveal information that does not appear as a direct identifier. Similarly, access metadata may show that a user consulted a sensitive case. Assess both the submitted content and what may be deduced from the output, from the frequency of queries, and from combination with other internal sources.
The assessment should cover plausible attacks and failures: poorly designed instructions that pull in an entire document, a search that retrieves content from another matter, a trace that retains clear text, excessively broad permissions, a connected tool that receives more context than necessary, or a person who relies on an incorrect extraction. Tests using difficult documents—scans, tables, annexes, contradictions, and content that must not circulate—are more representative than a demonstration based on clean examples.
INCIBE guidance recommends reviewing the provider and its privacy policies, using secure connections, and making use of privacy settings. For professional teams, this should translate into documented technical checks, not generic acceptance. Determine who operates each component, what access is possible, which settings have been enabled, how long requests and results are retained, and how deletion is verified when the purpose ends.
Define when the output assists and when human review is mandatory
Human review does not mean merely placing a person at the end of the screen. That person must have authority, sufficient information, and time to detect errors. In field extraction, this may require seeing the original passage that supports each value. In summarization, it may require comparing the draft with critical sections. In classification, it may require understanding the rule applied, the data used, and the available alternatives. Without these conditions, review risks becoming purely formal.
As a conservative rule, treat the output as assistance when it organizes, retrieves, proposes, or prefills. Increase control when the output may affect employment, access to services, contractual obligations, payments, safety, a person’s rights, external communications, or decisions that are difficult to reverse. In addition to impact, consider document uncertainty: poor scans, handwriting, complex tables, annexes, conditional language, and internal contradictions reduce operational reliability.
Define stop conditions before automating. These may include missing textual evidence, an answer outside the allowed schema, conflict between fields, low OCR quality, absence of required review, presence of excluded categories, or unapproved changes to the model, instructions, or connectors. A stop condition must produce a concrete action: block publication, send the item for review, request additional information, or remove it from the automated queue.
The NIST generative AI profile identifies risks associated with privacy, leakage, traceability, incorrect content, and human over-reliance. It does not itself require a particular architecture, but it provides a basis for avoiding an assessment based only on average accuracy. A system may be correct for most documents and still be unsuitable if its errors are opaque, hard to detect, or concentrated in the highest-impact cases.
Designing effective human review
- 01Show the output, source evidence, and the workflow version that produced it.
- 02State explicitly whether the result is a draft, recommendation, or validated data item.
- 03Require confirmation for cases defined by impact, ambiguity, or data category.
- 04Allow the reviewer to correct, reject, and explain the reason for the decision.
- 05Record validation without unnecessarily replicating sensitive content.
- 06Use rejections and errors to update tests, rules, and usage boundaries.
Turn controls into verifiable checks
Controls must be testable before and after deployment. For access, verify that only necessary roles can view the original, fragments, outputs, and logs. For isolation, test that a query concerning one matter cannot retrieve content from another. For retention, check what happens to temporary files, queues, caches, indexes, and traces. For deletion, define the scope: deleting a screen does not necessarily delete working copies or associated logs.
Traceability should reconstruct an output without retaining more content than necessary. Record internal identifiers, document version, applied transformation, OCR or model version, instruction template, retrieval rules, date, technical operator, and subsequent human decision. Link that evidence to access controls. Recording the full text of every request may be disproportionate for some purposes; an alternative is to retain references, fingerprints, or limited extracts where they enable investigation without multiplying the exposed content.
Include leakage and adversarial-behavior tests. Try to retrieve fragments from another case file, introduce instructions contained in the document to check that they do not alter the workflow, verify that outputs respect prohibited fields, and test the response to OCR errors. Test the incident plan: who can stop processing, how access is revoked, how evidence is preserved, and how scope is assessed without unnecessarily increasing exposure.
Contractual controls and technical configuration complement each other. An agreement may define responsibilities, but it does not replace least-privilege permissions, retention tests, or review of integrations. Conversely, correct configuration does not resolve an undefined purpose. This guide is operational and does not replace applicable legal analysis or an impact assessment where one is required.
Minimum control evidence before production
| Control | Verifiable evidence | Review frequency |
|---|---|---|
| Access | Role matrix and proof that unauthorized accounts cannot gain access | When roles change and periodically. |
| Retention and deletion | Documented settings and tests covering temporary copies, indexes, and logs | Before production and after technical changes. |
| Isolation | Cross-retrieval tests and tests of boundaries between matters or clients | With every relevant change. |
| Traceability | Record of version, transformation, model, and human decision | For every execution or defined case. |
| Quality and stopping | Difficult test set and evidence of blocking or escalation | Before deployment and continuously. |
| Incidents | Tested procedure for containment, revocation, and analysis | According to the response plan. |
Use a decision template for every document workflow
A concise template forces decisions to be made explicit and makes it easier for product, security, operations, and legal teams to discuss the same object. It should be completed per workflow, not for a tool in the abstract. For example, “summarize case files” may cover such different data, purposes, and consequences that a generic authorization becomes unhelpful. If there are multiple stages, document each one: OCR, indexing, retrieval, generation, output storage, and subsequent action.
At a minimum, include: purpose; data category and origin; included attachments and metadata; explicitly excluded content; prior transformation; authorized environment; entities operating each component; permitted output; recipients; retention period; validation owner; evidence to retain; stop conditions; and incident procedure. When a decision depends on a contractual or technical statement by a third party, state which evidence was reviewed and when, instead of assuming that the condition remains unchanged.
There are uncertainties that the template cannot resolve by itself. Available documentation may not fully describe the behavior of every component; a retention policy may vary by configuration; and re-identification capability depends on additional information and organizational context. Risks also change when connectors are added, results are reused, or the audience expands. The decision should therefore be reviewed after material changes and after incidents or testing findings.
The intended outcome is not to eliminate every exposure, which may be infeasible for certain purposes, nor to adopt a local model automatically. It is to justify a proportionate choice: which information is processed, why it is necessary, which controls limit exposure, which result may be used, and when a person must stop or validate the workflow. To expand the analysis of options, connect this decision to the solution selection index and internal security guides, while keeping the specific document workflow as the unit of assessment.
Open questions
- The cited European guidelines on pseudonymization were in public consultation in the supplied version; their interpretation and status may evolve.
- The possibility of re-identification depends on additional information, context, recipients, and combinations of data that are not always visible when designing a workflow.
- Contractual, technical, and configuration evidence for every component must be reviewed for the specific case; it cannot be inferred from a tool’s commercial category.
- This guide provides operational criteria and does not replace legal advice or formal assessments that may apply.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction