One-sentence definition
Response that must conform to a defined schema to be validated and processed automatically.
Definition and Distinction from Free Text
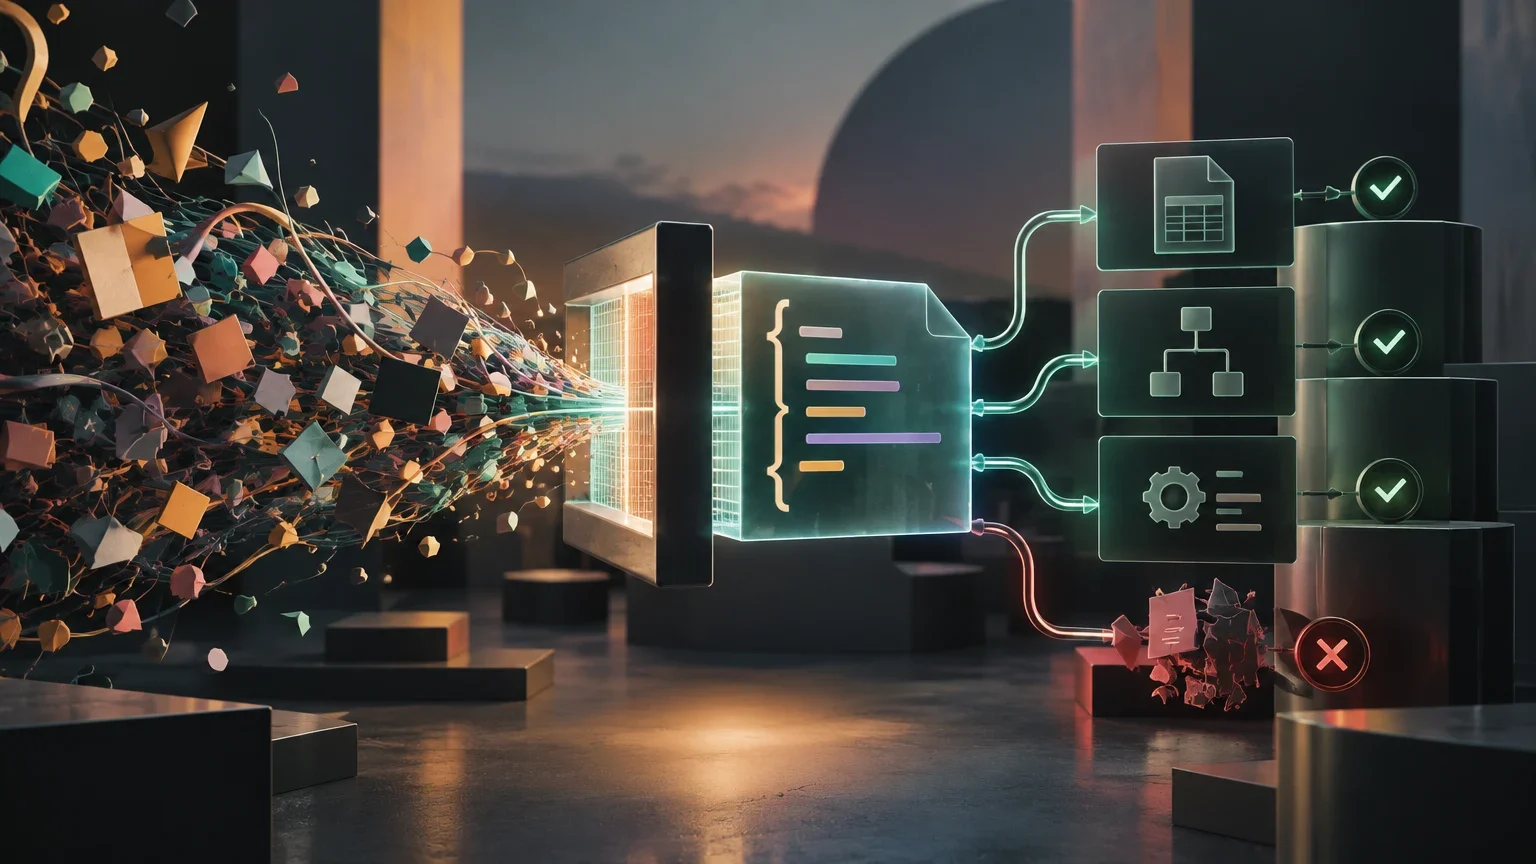
Structured output is defined as the generation of responses by a language model that conform to a predefined formal schema, typically JSON, XML, or CSV, allowing a program to parse them without ambiguity or human intervention. Unlike free text, where the model has total format freedom, structured output imposes a data contract that guarantees machine readability. This distinction is critical in production pipelines, where a format error can break entire automation chains.
The operational value of structured output lies in eliminating parsing uncertainty. In free text, a model might return a number in verbal format, wrap JSON in markdown fences, or omit mandatory fields. Structured output mitigates these risks by enforcing schema compliance, although it does not completely eliminate the possibility of semantic errors. It is the standard technique for data extraction tasks, ticket classification, or generating arguments for functions.
Comparison: Free Text vs. Structured Output
Key differences between both generation modes in the context of LLMs.
| Criterion | Free Text | Structured Output |
|---|---|---|
| Format | Variable, not guaranteed | Fixed, conforming to schema (JSON/XML) |
| Parsing | Requires heuristics or fragile regex | Direct via validators (Pydantic, Zod) |
| Main Risk | Semantic and format ambiguity | Schema complexity and latency |
| Typical Use | Chat, writing, brainstorming | APIs, data pipelines, agents |
Technical Mechanisms of Coercion and Validation
Three dominant approaches exist for obtaining structured output: Prompted JSON, Schema-constrained generation (constrained decoding), and Function calling. Prompted JSON involves instructing the model in natural language to respond in a specific format. It is quick to implement but offers no guarantees; the model may add explanatory text or generate invalid JSON. It is suitable for prototyping, always accompanied by client-side validation.
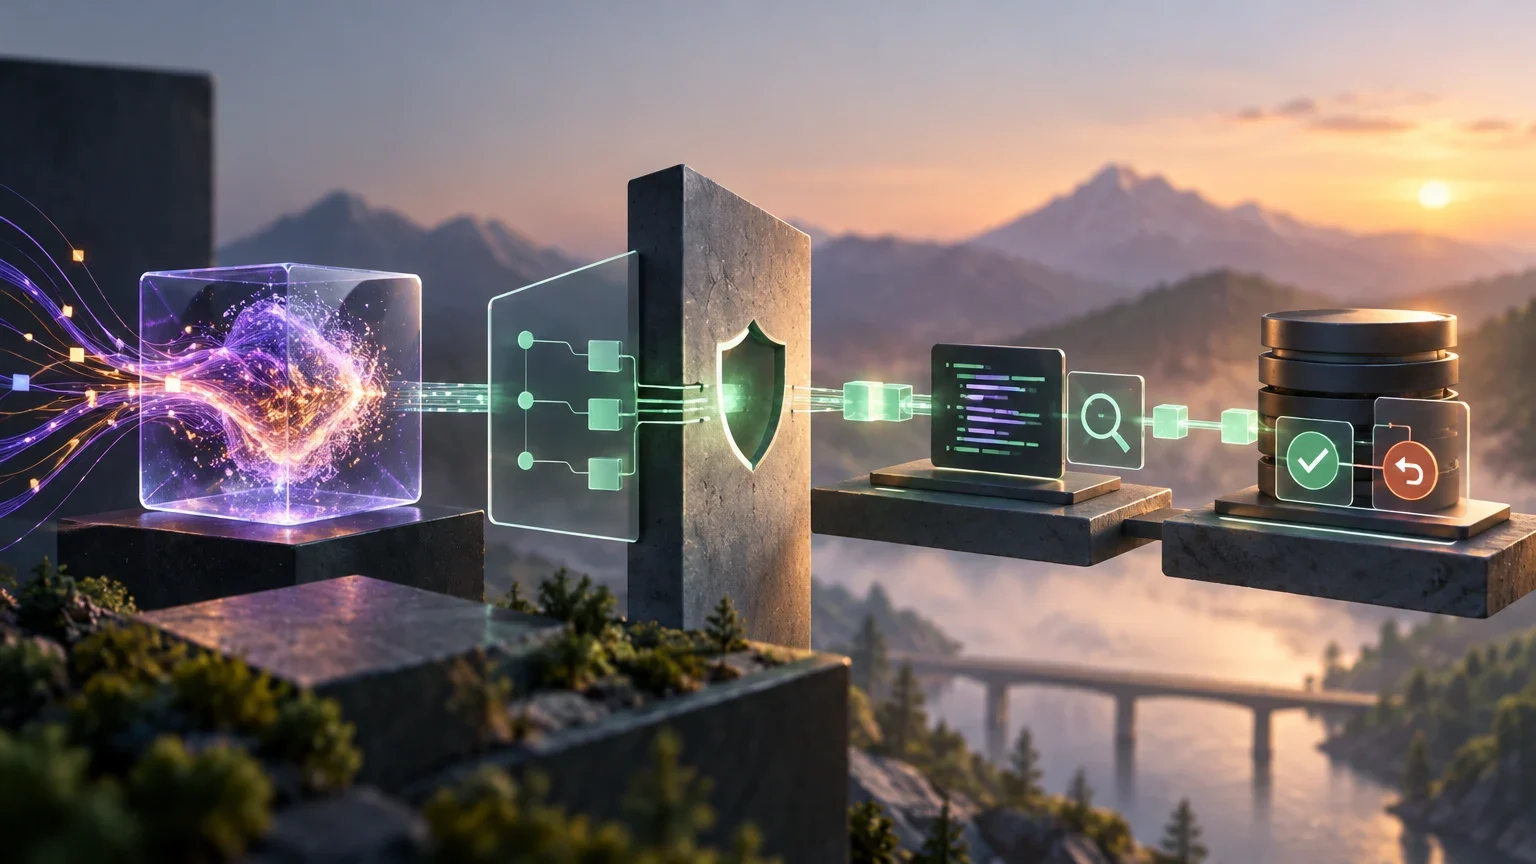
Schema-constrained generation, or constrained decoding, is the most robust mechanism. It works by limiting the tokens the model can emit at each generation step, masking the probabilities of tokens that would violate the schema syntax. This guarantees syntactic validity before a single invalid token is generated. Function calling combines this guarantee with the model's decision-making capability, allowing it to choose an action and generate the necessary typed arguments. For self-hosted models, tools like Outlines or vLLM implement this coercion via finite state machines or context-free grammars.
Production Validation Flow
Recommended sequence for handling structured output in a robust pipeline.
- 01Define a minimal JSON schema with mandatory fields, strict types, and enums for closed choices.
- 02Request generation from the provider using the response_format parameter or constrained decoding if available.
- 03Parse the raw response with a validator (Pydantic in Python, Zod in TypeScript).
- 04If validation fails, log the complete raw output for debugging.
- 05Perform a single retry with a tightened prompt or stricter schema.
- 06If the retry fails, route to a human review queue or apply a safe default value.
Applied Examples in Different Domains
In document data extraction, structured output allows converting unstructured invoices or contracts into JSON objects ready for database ingestion. For example, a schema with fields 'total' (number), 'due_date' (ISO date), and 'vendor' (string) allows the billing system to ingest data without parsing free text. Syntactic coercion prevents the model from returning the total as 'four hundred thirty-two dollars', which would break calculation logic.
In agent orchestration, structured output is fundamental for tool-calling. The agent must decide which tool to invoke and generate the correct arguments. A schema defining the function 'get_customer_info' with mandatory parameters 'name' (string) and 'id' (integer) guarantees that the agent does not attempt to call the API with malformed arguments. This is crucial in multi-step systems where a structural error in an intermediate stage can corrupt the agent's state in subsequent steps.
Common Confusions: Syntax vs. Semantics
A common error is assuming that syntactic validity implies semantic correctness. Technical coercion guarantees that the output conforms to the schema structure (e.g., that 'phone_number' is a string), but it does not guarantee that the value is correct. The model may generate a syntactically valid phone number that is non-existent or incorrect. This distinction is vital: automatic validation detects format errors, not content errors.
Empirical studies indicate that even when syntactic errors are eliminated via constrained decoding, significant structural and semantic errors persist. The main bottleneck is not syntax, but the model's ability to maintain semantic coherence under structural constraints. Therefore, structured output must be complemented with business validations, domain rules, and, in critical cases, human review.
Operational Limits and Performance Considerations
Structured output introduces operational limits that must be considered. First, schema complexity: very large schemas or those with many options can degrade model performance, as token restriction may interfere with the LLM's reasoning capability. Some studies suggest that models may perform worse on complex tasks when subjected to strict structure, so it is recommended to test structured output as an elicitation technique and measure its impact on response quality.
Second, added latency: constrained decoding requires calculating the probabilities of allowed tokens at each step, which can increase inference time. Third, provider dependency: not all providers support the same subset of JSON Schema or the same coercion parameters. It is recommended to use abstraction libraries like Instructor or Pydantic AI to manage these differences and ensure portability between providers.
Decision Guide: Which Method to Use?
Criteria for choosing between prompt, constrained decoding, and function calling.
| Scenario | Recommended Method | Justification |
|---|---|---|
| Rapid Prototyping | Prompted JSON + Validation | Maximum flexibility, no API dependencies |
| Deterministic Data Extraction | Constrained Decoding | Syntax guarantee, lower parsing risk |
| Agent Deciding Actions | Function Calling | Combines decision and typed arguments |
| Self-hosted Model | Outlines / vLLM guided decoding | Full control over inference layer |
Related Concepts and Further Reading
Structured output is closely related to data validation, agent orchestration, and LLM observability. To deepen understanding, it is useful to explore JSON Schema specifications, provider guides on structured outputs, and observability tools that allow tracing structured outputs in multi-step pipelines. The combination of technical coercion, client-side validation, and continuous observability is the recommended practice for production systems.
It is recommended to keep schemas minimal, version them from day one, and log both raw and validated outputs. This allows detecting silent regressions when models are updated or providers are changed. Structured output is not a magic solution, but a tool that, used with rigor, allows integrating LLMs into software systems in a reliable and maintainable manner.