A multimodal model for finding content
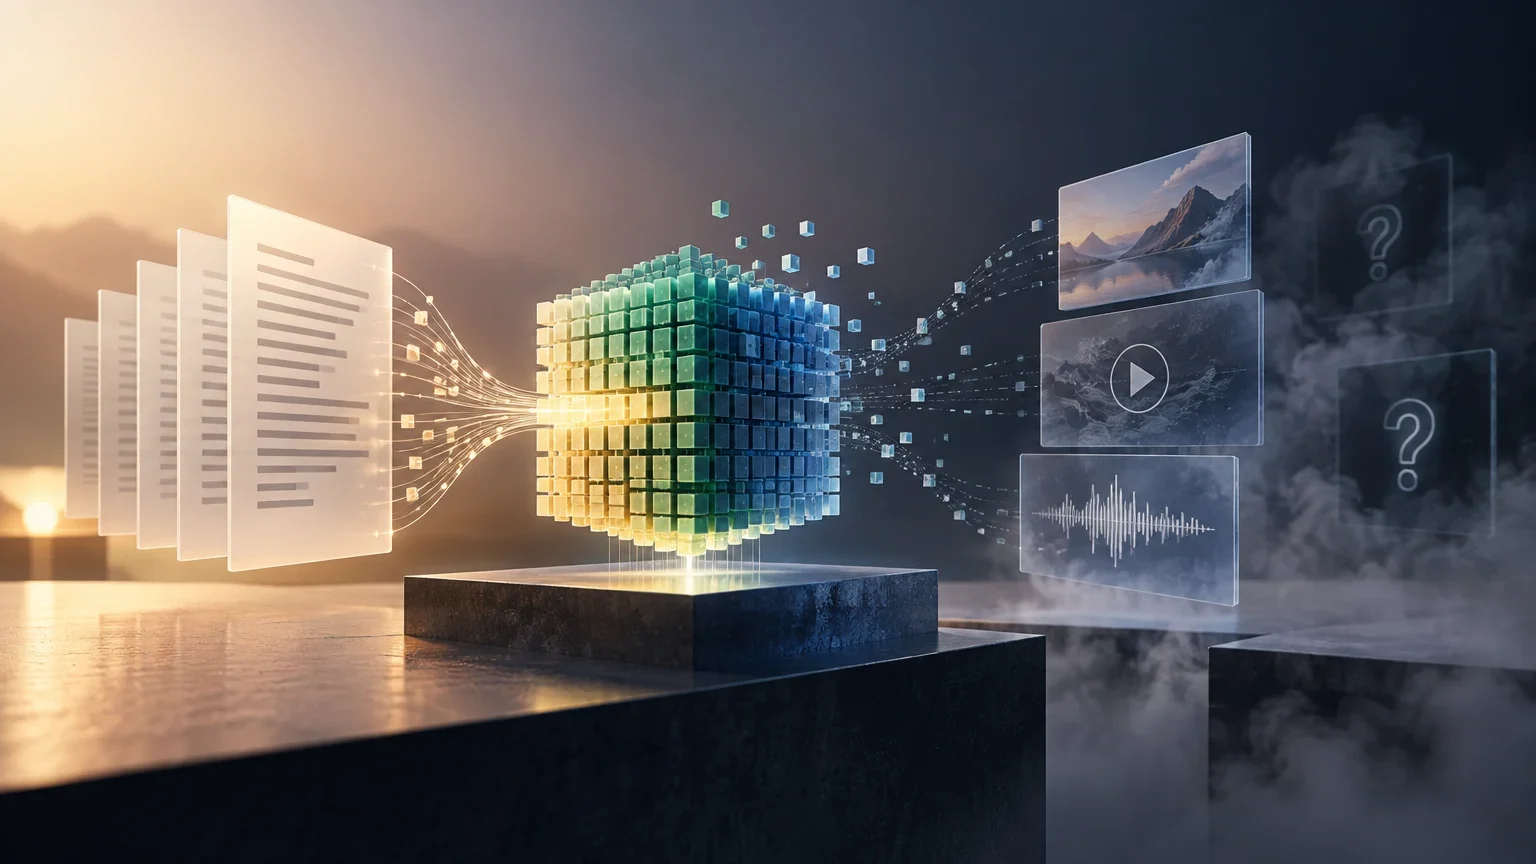
Google introduced EmbeddingGemma 2 as a multimodal expansion of its earlier text embedding model. The new version represents text—including code—images, audio, and video in a shared vector space. Its purpose is to help retrieve content related to a query; it is not a conversational model designed to write answers or generate images, audio, or video.
The model has 740 million parameters and combines a text component with vision and audio encoders that can be loaded selectively. Google says the text component has 270 million parameters, the vision encoder 170 million, and the audio encoder 300 million. These figures and the active configuration matter when estimating resource requirements: a text-only implementation does not necessarily load every component of the multimodal model.
EmbeddingGemma 2 produces 768-dimensional vectors and supports reducing them to 512, 256, or 128 dimensions through Matryoshka Representation Learning. Shorter vectors can reduce storage and speed up some searches, but quality may vary by dimension and task. A vector must be normalized after truncation if it will be compared using cosine similarity. Queries and documents in the index must also use the same dimension.
Google releases the model under the Apache 2.0 license. That license does not eliminate execution costs or, by itself, determine obligations related to an application's data. The model card describes a shared context of 8,192 tokens for the modalities; the effective limit depends on how inputs are combined and prepared.
How multimodal search works
An embedding is a numerical representation of an item, such as a sentence, image, or audio segment. A system compares vectors to rank candidates by similarity. In a document search, for example, a query about “footwear for rainy weather” might retrieve a product listing for waterproof boots even if it does not contain the exact word “rain.” That result is a candidate match, not proof that the model understood the intended use or that the listing is accurate.
EmbeddingGemma 2 can search across different modalities when an application prepares data for that task—for example, by matching a text query with images in a catalog. The model also supports inputs that combine text and media. To represent a product, an application might include its description and images; for a video query, it could provide the search text alongside frames processed using the chosen configuration.
Task prefixes help steer text representations. In asymmetric search, queries and documents play different roles: the query is prepared as a search question, while corpus items are prepared as documents. For symmetric tasks, such as clustering text or measuring sentence similarity, the same type of instruction is used for the items being compared. Prefixes apply to text, not to images, audio, or video.
Input configuration also affects how much content fits in the context. The model card specifies a shared budget across modalities, so combining text, images, audio, and video reduces the capacity available to each. For video, frame sampling and its frequency affect the information represented; for audio, the specified input format is mono at 16 kHz. These settings describe processing, but do not guarantee that every relevant detail will be retrieved.
How the task changes the evaluation
| Task | Inputs being compared | What the evaluation measures |
|---|---|---|
| Document search | A query and text documents | Whether relevant documents rank highly |
| Text-to-image search | A text query and images | Whether relevant images appear among the top results |
| Audio search | A query and recordings or segments | Whether relevant audio is retrieved under the defined criterion |
| Video search | A query and videos or represented frames | Whether relevant material is retrieved using the chosen sampling and data |
Model size, context, and local configuration
The 740 million parameters refer to the full multimodal model. According to the model card, the text-only configuration uses 270 million parameters; text and image use 440 million; text and audio use 570 million; and the full model uses 740 million. These figures describe the published loading configurations, not the total memory used by an application at runtime.
Weights size and memory use depend on factors such as numerical precision, software library, hardware, input length, and batch size. Google recommends bfloat16 when supported by the hardware and float32 otherwise; it warns that float16 can produce invalid values or degraded embeddings. Parameter count alone is therefore not enough to estimate memory use or latency for a specific deployment.
Matryoshka truncation lets users choose vectors with 768, 512, 256, or 128 dimensions. In results published by Google, reducing vectors from 768 to 256 dimensions cuts their size to one-third and changes several benchmark scores. At 128 dimensions, some multimodal scores fall further. These results apply to the tests and metrics reported by the provider; they do not establish which dimension will work best for a particular corpus or application.
Truncated vectors must be normalized before cosine similarity is used. The vector for a query and the vectors for indexed items must have the same dimension. Changing dimensions requires regenerating or consistently adapting the index; directly comparing a 768-dimensional vector with a 128-dimensional vector is not valid.
Published configurations by active modality
Parameter counts refer to the loaded components, not to the process's total memory use.
| Active modalities | Parameters listed |
|---|---|
| Text only | 270 million |
| Text and image | 440 million |
| Text and audio | 570 million |
| Text, image, audio, and video | 740 million |
Preparing reduced vectors for search
- 01Choose one dimension for queries and every item in the index.
- 02Truncate vectors to that dimension using the inference configuration or a compatible library option.
- 03Normalize vectors after truncation if you will compare them with cosine similarity.
- 04Validate retrieval on your own queries and documents before deploying the change.
How to evaluate retrieval performance
A useful comparison starts with a specific task and relevance criteria defined before testing. A benchmark can measure retrieval on a particular dataset, but it cannot guarantee the same results in another language, domain, or content type. Google's model card reports scores for different tests covering text, code, images, visual documents, video, and audio; each score belongs to a particular metric and evaluation set.
To evaluate text-to-image search, prepare real queries and a set of images labeled for relevance. For audio or video search, define what counts as a relevant result: an entire recording, a segment, or a frame. If the system combines modalities, specify how inputs are prepared and weighted before interpreting the metrics.
Compare the model with an alternative using the same queries, corpus, instructions, vector dimensions, and ranking rules. Measure retrieval quality, latency, and resource use separately. Record numerical precision, hardware, input length, and modality configuration so the result can be interpreted and repeated.
The evaluation should cover the languages and usage conditions expected in deployment. The model documentation notes that performance can vary across languages and may be affected by ambiguity and linguistic nuance. An aggregate score does not replace testing the queries that an application will actually receive.
A minimum test for your application
- 01Define the task: text search, text-to-image search, audio retrieval, video retrieval, or another combination.
- 02Collect representative queries and mark which results are relevant.
- 03Set the input preparation method, vector dimension, and ranking rules.
- 04Compare the candidate model with an alternative using the same corpus and configuration.
- 05Measure retrieval quality, latency, and resource use separately.
- 06Repeat the test in the languages, on the devices, and under the conditions planned for final use.
What the results show—and their limits
Google reports evaluation results across several benchmarks and compares some text tasks with EmbeddingGemma, the previous model. On MTEB multilingual, the published score for EmbeddingGemma 2 is 61.36, compared with 61.15 for the previous model. On the MTEB code test, the published scores are 78.68 and 68.76, respectively. These differences describe reported results for the specified tests; they do not guarantee improvement in every search system.
The model card also presents results for images, visual documents, video, and audio. Those values come from specific benchmarks and do not prove that the model generally understands a scene, a conversation, or an event. A search that ranks a relevant video near the top does not show that the system identifies every fact in it, answers open-ended questions accurately, or explains why the video is relevant.
The model generates representations, not conversational answers. An application can use retrieved results as context for another generative component, but the final quality will also depend on that component, the corpus, and the application's rules. Retrieval and the answer produced afterward should be evaluated separately.
Google says EmbeddingGemma 2 is released under Apache 2.0 and offers open weights. The model card notes that embedding models do not receive post-training safety tuning or output moderation in the same way as generative models; safeguards such as retrieval filters and fairness tests are the responsibility of the application’s deployers. An open license does not turn a search result into factual verification or remove the need to review bias, privacy, and intended use.
Retrieval and understanding are different
| Observed result | What it supports | What it does not prove on its own |
|---|---|---|
| A relevant document ranks among the top results | The system retrieved that document in a specific test | That it verified the document's contents or answered correctly |
| A related image appears for a text query | The test found a useful match in that configuration | That the model can interpret any image or scene |
| A video is retrieved for a query | The video was considered relevant under the chosen criterion | That the system understands every event in the video |
| A benchmark produces a high score | The model performed according to that task and metric | A universal advantage or a guarantee in production |
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction