Announcement and model architecture
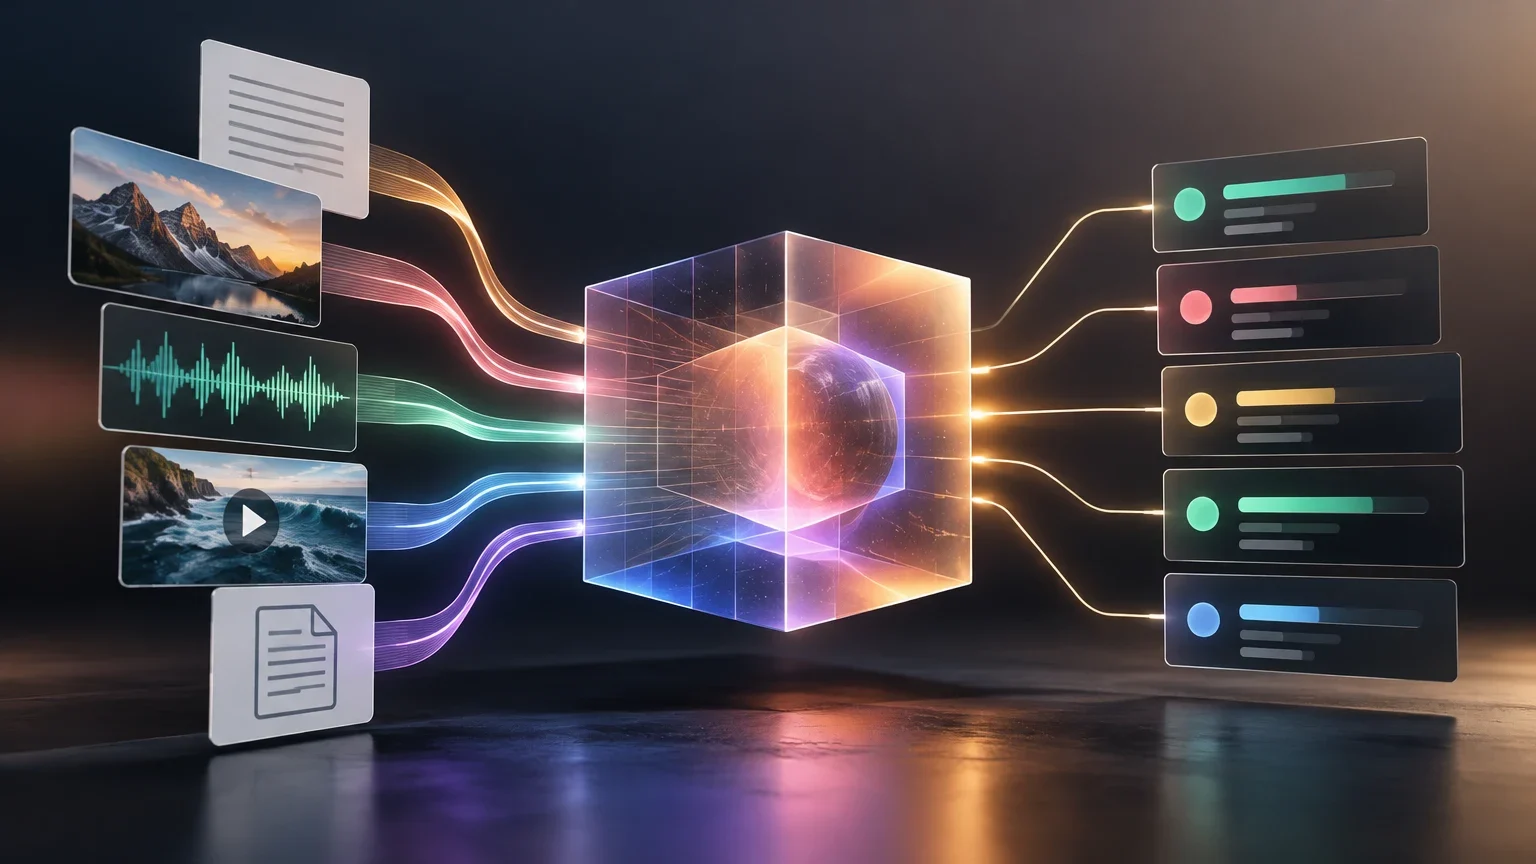
Google has introduced the Gemini Decisions API, a new endpoint designed for fast, closed-set decisions on multimodal inputs. This tool relies on the Gemini Decision 1 model (identified as gemini-decision-1), available through the Gemini API in Google AI Studio. Unlike generative models that produce text token by token, this model scores candidate options in a single inference pass, returning probabilities and confidence scores.
The goal of this architecture is to provide purpose-built primitives for bounded choices, such as tool selection, policy checks, model routing, or context grading. The API allows passing a shared multimodal input, which can include text, images, audio, video, and PDFs (up to 256K tokens), along with up to 1,000 independent questions in a single request.
The shared-input design separates the material being assessed from the questions asked about it. One multimodal input can therefore serve as the basis for many bounded evaluations within the same request, rather than requiring a separate copy of that input for every question. The model returns option scores and confidence values, while the application remains responsible for deciding what to do with those results.
This approach is intended for cases where an application needs to choose among defined outcomes rather than receive an open-ended text response. Tool selection, policy checks, model routing, and context grading are examples named for the API; the announcement does not establish that the model makes those decisions correctly in every application.
Evaluation types and response structure
The API supports three types of decisions in a single pass: noul (yes/no), choice (multiple choice), and score (ordered rubric). The noul type estimates the probability that a binary condition holds. The choice type selects from 2 to 255 options, returning the winning option and normalized probabilities for each candidate. The score type evaluates the input against an ordered rubric, returning a continuous weighted score and probabilities per level.
Each response includes a confidence score between 0 and 1, allowing application code to route ambiguous cases to a fallback mechanism or a human reviewer. The input uses the same content block format as the Interactions API, facilitating integration with existing development workflows.
The three evaluation types express different kinds of bounded questions. A noul response concerns whether one binary condition holds; a choice response ranks a fixed set of candidates; and a score response places an input against ordered rubric levels. These outputs are probabilities or scores, not explanations of why a candidate was selected.
A confidence value can help application code identify cases that may need a fallback or human review, but it does not by itself guarantee that the result is correct or that the probabilities are well calibrated. The appropriate threshold and response to an uncertain result depend on the application’s own requirements.
Question types supported by the API
| Type | Description | Primary Output |
|---|---|---|
| noul | Binary condition evaluation (yes/no) | Probability of fulfillment |
| choice | Selection from 2 to 255 options | Winning option and normalized probabilities |
| score | Evaluation against an ordered rubric | Continuous score and per-level probabilities |
Performance, latency, and cost
Google states that Gemini Decision 1 maintains a model compute latency of 50 to 100 milliseconds, with an end-to-end latency of 150 to 250 milliseconds. This latency remains nearly flat as the number of questions per request increases, from 1 to 100. The model supports contexts of up to 16K tokens in the published latency tests, although the general input allows up to 256K tokens.
Regarding cost, the price is set at $0.10 per million input tokens, with a $0 rate for output tokens. Google indicates that, by not billing output tokens, the API is nearly 5 times cheaper than Gemini 3.5 Flash-Lite with the Interactions API across the shared benchmark suite. The shared input is billed once per request, regardless of the number of questions evaluated.
The latency figures describe different parts of a request: 50–100 milliseconds for model computation and 150–250 milliseconds end to end. Google says the end-to-end figure changes little as a request includes more questions, across the tested range of 1 to 100. The published latency tests used contexts up to 16K tokens, so their timing results should not be treated as measurements for the full 256K-token input limit.
The quoted cost comparison is specific to the shared benchmark suite and to Gemini 3.5 Flash-Lite used with the Interactions API. Google attributes the difference to charging for input tokens but not output tokens, and says the shared input is billed once per request. These pricing and comparison details do not establish the cost or speed an application will experience with a different workload.
Internal use cases at Google
Several Google teams are already using the Decisions API as a low-latency control plane. In Gemini Notebook, the API acts as a real-time router that directs incoming queries to the optimal model tier and thinking level, reducing the latency of everyday queries by up to 40%.
In Stitch, the design tool, the API is used to generate playable wireframes of a product flow in seconds and apply edits made by voice or tap almost instantly. In CC (from Google Labs), it is used to select the appropriate emoji reaction from a palette of more than 200 options in a fraction of a second. Additionally, Google Search employs it as a safety layer to detect adversarial behavior in MCP tools.
The examples describe different roles for the API within Google products: routing incoming queries in Gemini Notebook, applying voice- or tap-based edits in Stitch, choosing an emoji reaction in CC, and detecting adversarial behavior in MCP tools for Google Search. Together, they illustrate the announced use of bounded decisions as a control layer, rather than showing that every use has the same task or outcome.
Google attributes a reduction of up to 40% in everyday-query latency to Gemini Notebook’s routing use. That figure is a claim about that described deployment; it should not be read as a general latency reduction for other products or applications.
Accessibility and evidence limitations
Developers can start building today by obtaining an API key in Google AI Studio. The API offers a no-cost tier for prototyping and is available through guides for Python, JavaScript, and REST. Ecosystem integrations are rolling out on platforms such as OpenRouter, LangChain, Vercel, and LiteLLM, with support coming soon for Gemini in Google Cloud.
It is important to note that the performance, latency, and cost-saving figures are Google's claims based on its own benchmarks. No independent verification of these metrics or details about the specific calibration mechanism used by the model has been provided. Before recommending it for critical production use, it would be necessary to evaluate the reliability of its probabilities in real-world scenarios and compare its performance with other solutions available in the market.
Access through Google AI Studio, a no-cost prototyping tier, and guides for Python, JavaScript, and REST provide stated starting points for developers. The named ecosystem integrations are rolling out, and support for Gemini in Google Cloud is described as forthcoming; these statements do not imply that every integration is already generally available.
For a production decision, the key distinction is between a returned probability and a probability shown to be reliable for the application at hand. The announcement does not provide independent calibration metrics or independent verification of the performance and cost figures. Application-specific testing can assess whether the outputs, latency, and costs meet the relevant requirements, but the published benchmarks alone do not settle those questions.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction