What problem Agents’ Last Exam is trying to solve
Agent benchmarks often simplify professional work so that it can be measured: a question with an answer, a code change in a repository, or an isolated action in an interface. That simplification may be necessary, but it leaves out an important part of real workflows: preparing files, inspecting local information, operating across several applications, producing an artifact, and leaving behind a final state that another person can verify.
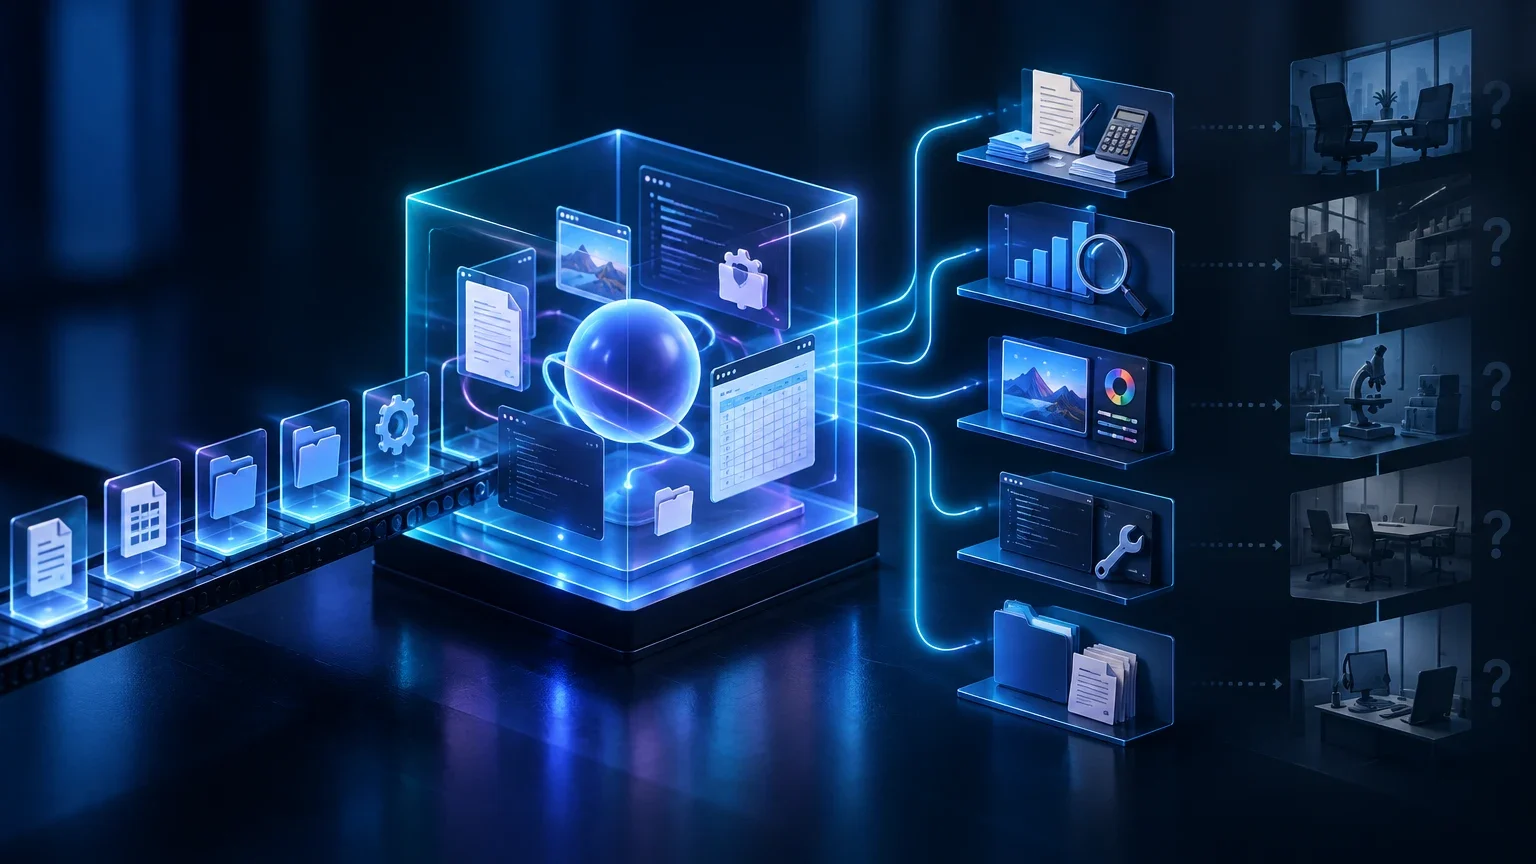
Agents’ Last Exam, commonly abbreviated as ALE, presents itself as a framework for evaluating agents that carry out long professional tasks in isolated operating-system environments. The documentation describes a unit made up of an agent, a task, and a sandbox environment. The task is not merely a textual instruction: it also includes an initial state and a mechanism for assessing the outcome produced after execution.
That change in the unit of measurement matters. Rather than asking only whether a model knows a procedure, ALE seeks to observe whether a specific configuration can complete a task under defined operating conditions. At a minimum, that configuration includes the model, the agent loop, the tools exposed to it, the environment, execution constraints, and the evaluator. The result therefore belongs to a configured run, not to a model understood as an abstract capability.
This can make ALE closer to a workflow test than an isolated skill evaluation. However, “closer” does not mean equivalent to workplace practice. A job combines tasks that may not be included, shifting priorities, human coordination, accountability, access to internal systems, security policies, and economic consequences. A sandbox evaluation can provide evidence about performance within that sandbox without directly measuring all of those elements.
The actual unit of evaluation: task, environment, harness, and budget
To read a result, it is necessary to reconstruct what was run. The task defines the objective and the initial state. The sandbox environment contains the files, applications, data, and constraints with which the agent can interact. The agent chooses actions through a harness, which connects the model to tools such as a terminal, graphical interface, browsing, or file reading and writing. Finally, a grader inspects the result according to criteria defined for the task.
Every component can change the outcome. A seemingly identical task may be easier if the environment includes a preinstalled utility, credentials, local documentation, or data that has already been normalized. It can also change if the agent receives screenshots, structured accessibility information, terminal commands, an automated browser, or a combination of these. Comparing two percentages without knowing these conditions can attribute to the model a difference actually caused by the harness or sandbox.
The budget is also part of the experiment. The time limit, maximum number of steps, permitted cost, context length, retries, and policy for transient errors change the probability of finishing. An agent that needs many interactions may achieve a strong result with a generous budget yet be impractical under latency or cost constraints. Conversely, a very strict constraint may conceal a strategy that would work in an asynchronous process.
The official repository includes code, public tasks, and execution infrastructure, while the technical documentation explains the task-creation and evaluation cycle. This is a useful basis for auditing configurations, but practical reproducibility requires recording exact versions, parameters, environment images or dependencies, and results for each repetition. The existence of code does not guarantee that every historical run can be reproduced without those details.
How to audit an ALE figure
- 01Identify the task-set version and the date of execution.
- 02Determine the evaluated subset and any tasks excluded, failed, or retried.
- 03Record the model, version, provider, system prompts, harness, and enabled tools.
- 04Describe the sandbox image, connectivity, initial data, permissions, and isolation limits.
- 05Note the time limit, steps, monetary or token budget, and recovery policy for failures.
- 06Separate the full-success metric from the mean partial-credit score, and publish results by task or category where possible.
Occupational coverage: 13 clusters and 55 subdomains are not 13 automated sectors
Project materials describe coverage of 55 subdomains grouped into 13 clusters and relate the taxonomy to O*NET and SOC 2018. This choice helps organize heterogeneous professional tasks and makes clear that the evaluation is not limited to programming or a single desktop application. It also makes it possible to ask which areas are present and which are sparsely represented.
Occupational taxonomy, however, does not automatically turn a task collection into a measurement of occupations. O*NET classifies and describes occupations, knowledge, skills, work activities, and other job attributes; a real position combines many tasks with different frequencies, levels of criticality, and dependencies on context. A selected task from a subdomain may represent a particular operation without representing the full job associated with it.
Nor should proportional coverage be inferred. The existence of a cluster does not reveal how many tasks it contains, what internal variety it covers, how difficult its cases are, or what economic weight they carry. To evaluate one’s own use case, the relevant question is not whether a sector appears in a label, but whether the set includes inputs, tools, exceptions, and quality criteria comparable to those of the actual process.
The relationship with O*NET can help with conceptual traceability. It allows discussion of which activities have been approximated and which gaps remain. But an occupational classification does not by itself provide an automation rate, a wage forecast, or an estimate of workforce reduction. Those conclusions would require additional data on adoption, process redesign, supervision, costs, and sustained performance.
What can and cannot be inferred from coverage
| Observation | Reasonable inference | Unjustified inference |
|---|---|---|
| There are tasks associated with 55 subdomains and 13 clusters | The benchmark seeks diversity across work domains | That it completely covers each occupation or sector |
| A task is linked to an occupational taxonomy | There is a reference for describing its work context | That it measures the total productivity of a job |
| An agent solves tasks from a cluster | It has worked under those tasks and conditions | That it can replace all people in that cluster |
| An area has few published cases | Observed evidence for that area may be limited | That the agent is incapable in every workflow in that area |
Full success, partial credit, and hidden references
The results page distinguishes between Pass Rate and Score. Under that definition, Pass Rate is the proportion of runs that receive a perfect score, while Score summarizes average partial credit. The two metrics answer different questions. The first requires the outcome to satisfy the task’s full criterion; the second can show that an agent made partial progress even when it did not deliver a wholly valid result.
Partial credit is informative, especially for diagnosing where agents fail. It may indicate that correct files were created but a check was missing, that part of a procedure was completed, or that the final result approached the expected one. It should not, however, be presented as operational success when the use case requires a complete delivery. In a financial close, data migration, or compliance update, a partially correct solution may have no value or may even introduce risk.
The task-creation documentation explains that the reference used for evaluation is kept hidden and materialized for evaluation. The grader runs an evaluation function that returns a score, generally on a scale from zero to one. This design aims to prevent the agent from directly obtaining the reference solution available to the evaluator and allows deterministic checks over artifacts or final states.
A deterministic grader does not eliminate every measurement decision. Someone must define which properties are checked, what tolerance is allowed, and what outcome deserves partial credit. A grader may be consistent when the same input is repeated while still measuring only the formalized conditions. The validity of the score depends as much on that definition as on the agent’s ability to execute actions.
CLI, GUI, and the problem of comparing different agents
ALE supports interactions through a command-line interface, a graphical user interface, and configurations that can combine both. The modality matters because it determines which observations and actions are available. In a terminal, the agent can inspect file structures, run commands, and automate transformations compactly. In a graphical interface, it must perceive visual state, locate controls, and cope with focus changes, windows, loading times, or ambiguous elements.
The leaderboard identifies subsets, including ALE-CLI. That subset can be useful for studying terminal-oriented agents, but it should not be treated as a numerically interchangeable version of the full evaluation. A CLI score excludes or reduces aspects of graphical interaction; a combined score imposes a different demand. Comparison is defensible only when the task set, rules, environment, and metric match, or when the differences are stated explicitly.
A general-purpose computer-use agent is not defined merely by operating a cursor. In evaluative terms, it matters whether it can observe relevant state, select tools, retain the context of a long task, recover from unexpected outcomes, and verify its own work. A harness that adds specialized tools may improve performance, but then the result evaluates the system formed by model and tools, rather than the model policy alone.
This caution also applies when looking at Terminal-Bench, OSWorld-Verified, and SWE-Bench Verified. Each benchmark asks a different question and uses its own tasks, environments, and verification methods. Terminal-Bench focuses on terminal tasks; OSWorld-Verified studies interaction with verified desktop environments; SWE-Bench Verified is aimed at resolving software issues. No result automatically becomes another merely because the same model or the same agent label is involved.
Rule for comparing results
| Element | Needed for a direct comparison | Risk if it differs |
|---|---|---|
| Task set | Same version and same subset | The difference may come from case selection |
| Modality | Same access to CLI, GUI, and tools | Different interaction capabilities are being measured |
| Environment | Same image, initial data, permissions, and network | The resources available for solving change |
| Budget | Same limits on time, steps, and cost | One configuration may explore more or recover better |
| Metric | Same definition of success and aggregation | Pass Rate and partial credit can tell different stories |
How to read a leaderboard or a vendor announcement
A leaderboard provides a useful snapshot, not an independent deployment guarantee. Before accepting a figure, check whether it reports the ALE version, subset, number of evaluated tasks, metric, and aggregation method. The precise identity of the model and harness, the tools, execution limits, and the policy for retries, infrastructure failures, or incomplete runs should also be available.
A success rate needs a clear denominator. Evaluating every available task is not the same as running a selection, omitting cases with unresolved dependencies, or publishing only successful runs. If there are several repetitions per task, the result should state whether it uses the mean, the best attempt, the first attempt, or another rule. Choosing the best of several attempts may answer a question about maximum capability, but it does not measure the reliability of a single run.
It is also useful to separate observed facts from interpretation. A fact is that a configuration achieved a particular metric under published rules. A possible interpretation is that the agent appears especially suitable for a certain kind of task. The latter requires inspection of disaggregated results, failures, and similarity to the target workflow; it does not follow from one global figure alone.
The status of a living benchmark adds another warning. If tasks, the public corpus, the environment, or graders change, a figure from one date may not be comparable with a later one. The project documents ALE’s living character and the existence of a public corpus. For longitudinal results, the version and date are not editorial details: they are part of the meaning of the data.
Minimum information that should accompany a published figure
- 01Benchmark version or identifier, date, and exact subset.
- 02Number of attempted, completed, skipped, and infrastructure-failed tasks.
- 03Pass Rate, Score, and the aggregation rule used.
- 04Model, version, temperature or other relevant parameters, and inference provider.
- 05Harness, prompts, tools, network permissions, and CLI, GUI, or mixed modality.
- 06Limits on time, steps, tokens, and cost; number of repetitions and selection policy.
- 07Disaggregated results where available, and a description of the principal failure modes.
ALE’s limits and the tests still needed before production
ALE does not establish that a system is safe or reliable in a particular organization. A sandbox limits scope and makes final states verifiable, but it does not necessarily reproduce corporate identities, sensitive data, historical permissions, unstable integrations, audit requirements, or effects on customers. The absence of access to real systems may be deliberate and desirable for controlled measurement, while still limiting extrapolation.
Nor does it solve benchmark optimization risk on its own. The availability of public tasks and code supports auditing and research, but it may allow models, prompts, or tools to adapt to regularities in the set. Hidden references and graders reduce one specific form of answer leakage; they do not demonstrate the absence of training-data contamination, familiarity with task patterns, or indirect optimization. The available evidence does not by itself quantify that risk for every model.
Representativeness is another limitation. Tasks are selected and formalized; real processes contain ambiguity, exceptions, conflicting objectives, and quality standards that may evolve while work is under way. A strong result is evidence that an agent met established criteria on selected tasks. Concluding that it works in a specific process requires a local evaluation with data, controls, and errors relevant to that process.
Finally, the metric does not calculate economic value. A deployment decision depends on supervision time, correction rates, error severity, inference and infrastructure cost, speed, traceability, privacy, and accountability. There may be cases where modest performance is useful with human review, and others where a high rate is insufficient because a single failure has severe consequences.
Checklist for a use case of your own
ALE becomes more useful when it is used as a filter rather than as a final verdict. If an agent performs well on tasks close to an organization’s own workflow, there is a reason to design an internal test; if it does not, that may be a signal of risk or a configuration difference worth investigating. In both cases, transfer must be demonstrated rather than assumed.
The internal test should include representative examples, including ordinary cases, rare cases, and recoverable failures. It should assess both the final artifact and the route taken when the process requires traceability. It should also define when a person intervenes, which actions are prohibited, how changes are reversed, and which metrics establish that the system is useful without raising risk beyond an acceptable threshold.
The most responsible outcome is not a declaration of general autonomy, but a bounded statement: a particular configuration can complete an observed proportion of tasks from a known set under published conditions. ALE helps formulate that statement more rigorously than an isolated example. It does not replace the technical, operational, and organizational validation needed to automate part of a real process.
Decision checklist before extrapolating
- 01Do the evaluated tasks resemble the inputs, applications, and deliverables of the target process?
- 02Does the comparison use the same interaction modality and tools that deployment will use?
- 03Is the full-success rate known, rather than only partial credit?
- 04Are observed errors correctable through human review, and at what cost?
- 05Does the internal pilot measure privacy, permissions, traceability, latency, and recovery?
- 06Are there explicit limits on irreversible or high-impact actions?
- 07Does the decision incorporate repeated results and new cases, rather than only a leaderboard score?
Open questions
- The exact total number of tasks and its split between public and evaluable tasks are not specified here because they must depend on a specific version and cutoff date.
- The exact proportion of CLI, GUI, or mixed-interaction tasks is not fixed without consulting the corresponding task-set version.
- No model figures or leaderboard positions are included: without the full configuration, an isolated figure would have limited interpretability.
- Temporal comparability may be affected by the benchmark’s living character and by updates to tasks, environments, graders, or the public corpus.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction