What an AI trace can solve—and what it cannot prove
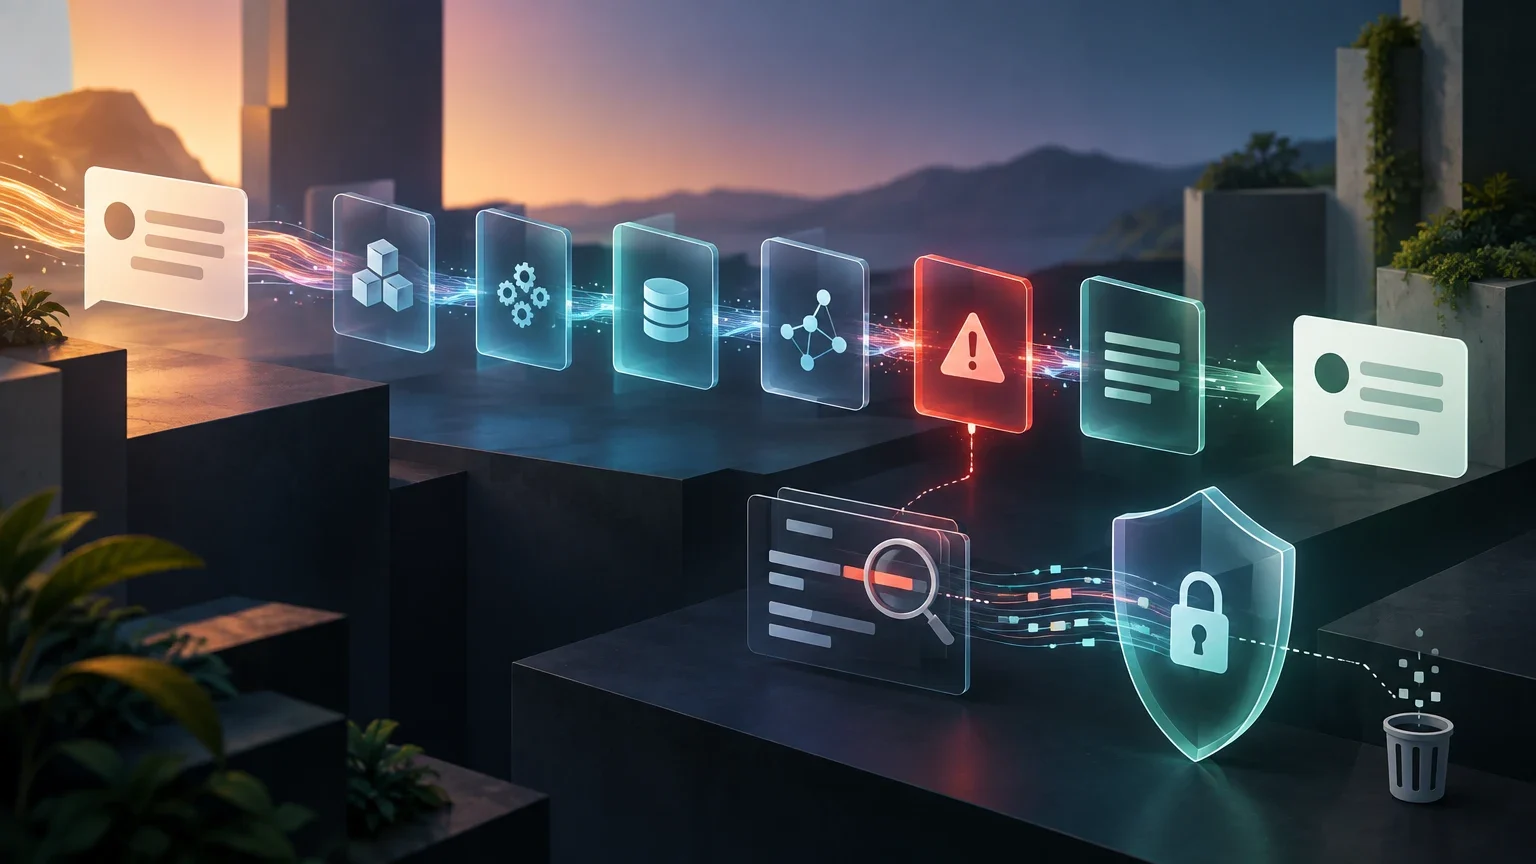
A trace lets you observe the operations that make up a request and how they relate to one another. In an AI application, it can connect the input received by a service, document retrieval, one or more model calls, tool executions, validations, and the response delivered. Its main purpose is to reconstruct the technical path: which steps occurred, in what order, and where a delay, error, or unexpected result arose.
A trace does not, by itself, prove why a model generated a particular phrase, that the response is correct, or that a future execution will produce the same result. It represents what the instrumented system observed and chose to record. If spans, attributes, or events are missing, the path may be incomplete. If sensitive content is excluded, it may also be impossible to inspect the input or response verbatim; that may be a deliberate privacy choice, not a flaw in the trace.
It is useful to distinguish observed facts from hypotheses. “The tool call ended in an error” is an observation that may appear in telemetry. “That error caused the incorrect response” is an interpretation that requires reviewing the flow and, if possible, comparing it with other executions. Tracing helps locate a likely cause; it does not replace testing, quality evaluation, or review of the system's data and instructions.
Traces, metrics, and logs: different signals
A trace represents a related end-to-end execution. Its spans describe operations and may have parent-child relationships; for example, a response operation may contain retrieval and generation, and generation may include a tool call. Events associated with a span add point-in-time occurrences. This structure lets you follow a request without relying only on searches for similar text messages.
A metric summarizes measurements for observing trends or aggregate states, such as duration or error count. It helps detect changes and compare groups of executions, but typically does not explain, on its own, what happened in a particular request. Avoid using unique user, request, or document identifiers as metric dimensions: they create high cardinality and make it harder to maintain manageable aggregations. Use traces for detail and metrics with bounded dimensions for aggregate monitoring.
A log is an independent event or message, such as a validation warning. It may include trace context so it can be linked to an execution, but it does not necessarily preserve the hierarchical structure of every step. In practice, the three signals complement one another: metrics help uncover an anomaly, traces help follow an execution, and logs provide point-in-time context. None requires you to store the full content of a conversation.
Which signal should you consult first?
A practical decision: choose the signal based on the question, and limit identifiable attributes to what is actually needed.
| Question | Primary signal | Recommended use |
|---|---|---|
| Have latency or errors increased? | Metric | View aggregate trends and narrow down the affected period. |
| Which operations did this request go through? | Trace | Inspect spans, relationships, duration, and outcome. |
| What warning did a validator emit? | Log or event | Review the occurrence and link it to the trace when context is available. |
Map out a request
Before instrumenting, map the application's actual flow, not the flow you assume it follows. A simple path might start at the ingress service, validate the request, retrieve documents, build context, call the model, execute a tool if requested, validate the output, and return a response. There may be retries, branches, parallel calls, or a second generation after a tool call; represent these as distinct operations when they matter for diagnosis.
A readable hierarchy might have a root span for the application operation and child spans for retrieval, generation, tool execution, and validation. The parent-child relationship explains which operation contains another; context links can relate operations that do not fit neatly into a simple hierarchy. You do not need a span for every internal instruction: instrument the boundaries where decisions are made, a dependency is called, or an operation may fail.
Assign a correlation identifier to the execution and propagate it to the participating operations, including your own services that accept trace context. Do not make that identifier part of a span name or a metric dimension. Names should describe operations in a bounded and stable way; unique values belong, if needed and safe, in trace attributes subject to access controls.
Minimum fields for reconstructing the flow
A minimal schema should let you answer four questions: What operation occurred? Which execution does it belong to? How long did it take? How did it end? Stable operation names, relationships between spans, timestamps or duration, status, and an error category are often useful for this purpose. Add bounded attributes that help distinguish, for example, an operation type or environment. The specific attributes should match the instrumentation and conventions your team actually adopts.
For generation calls, it may also be useful to collect operational information such as the configured provider or model, duration, status, and available usage counters. The availability and meaning of these fields depend on the integration: do not assume that two instrumentors name the same data in the same way or calculate it identically. Also record whether retrieval, a tool, a retry, or validation took place, using statuses that distinguish “not executed” from “executed and failed.”
To locate a faulty result without retaining the prompt or every document, combine flow metadata, counts, and statuses: number of retrieved results, validation outcome, error type, an identifiable application version, and timings by operation. If inputs need to be compared, consider fingerprints or restricted-access internal references, but assess whether they are reversible or allow personal data to be linked. A fingerprint is not automatically anonymous. Avoid logging names, addresses, access tokens, full tool arguments, and entire documents for convenience.
Minimal capture versus content capture
The minimal-capture column is an engineering starting point, not a universally required set of fields.
| Diagnostic need | Possible minimal capture | Risk of capturing more |
|---|---|---|
| Find the slow step | Duration per span and operation name | Full arguments may expose content without improving the measurement. |
| Determine whether retrieval returned results | Status and result count | Recording entire documents exposes content and personal data. |
| Understand a tool failure | Tool type, status, and error category | Arguments may contain secrets, identifiers, or user text. |
| Compare generation behavior | Identifiable configuration, status, and available usage | Full prompts and responses increase exposure and the cost of protection. |
Sensitive content: minimize, redact, and control
Prompts, responses, retrieved documents, and tool arguments may contain personal data, confidential information, or operational secrets. Treat them as potentially sensitive content even if the application does not classify them that way. For routine diagnosis, the safest option is not to capture them by default. If a specific use case needs excerpts, define which excerpts, who can view them, how long they will be retained, and what approval process applies.
Redaction can remove or replace values before export; filtering can discard data or events that should not leave the process. Decide where these controls apply and verify their effect with test data. A transformation in the Collector can reduce or modify telemetry before it is exported, but that is not the same as preventing the content from having been generated, captured, or stored before it reached that component. Review every stage of the path: instrumentor, buffer, Collector, exporter, and storage.
Restrict access to traces by job function and log access where the platform allows it. Set a short retention period that matches the time needed to investigate incidents, and check that copies, exports, and buffers follow the policy. Sampling can reduce volume, but it does not replace protecting each trace that is retained. Keep a controlled way to temporarily increase detail during an investigation, with authorization, limited scope, and an end date.
Data-reduction process before export
Use these controls as a reference design and verify where they apply in the actual implementation.
- 01Inventory the fields produced by each instrumentor, including arguments, inputs, outputs, and exceptions.
- 02Classify fields as necessary for operations, useful only for specific investigations, or unnecessary.
- 03Disable capture of unneeded content and redact or filter approved fields before export.
- 04Test with dummy values to confirm that redaction covers spans, events, logs, and error paths—not just the normal case.
- 05Verify destinations, permissions, buffers, and deletion timelines; document who can raise the capture level.
Read a trace to find the component that failed
Start with the root span and confirm that it represents the execution you want to investigate. Check its status and follow its children in time order. Look for gaps between operations, spans without outcomes, or dependencies that took unusually long compared with their own history. A high total duration does not identify the component on its own: the cause may be slow retrieval, a model call, waiting on a tool, retries, or work that was not instrumented.
If the response lacks information that should have been retrieved, first inspect the retrieval status and result count, retrieval filters, and context construction. If the context seems suitable but generation fails or takes a long time, review the model span, its status, and retries. If the model requests an action but the final result is wrong, follow the tool span and check whether it failed, returned unexpected data, or was left out of the flow. If the response was generated but did not reach the user, examine validation and the operation that constructs the output.
These paths are working hypotheses, not rules for automatically assigning blame. A tool may return a valid response that the application processes incorrectly; validation may reject a correct output because of its configuration; an incomplete trace may hide an intermediate operation. Note what evidence supports each conclusion and what information is missing. If diagnosis requires looking at content, request temporary, approved capture in a test execution instead of indiscriminately enabling prompt logging for users.
Repeating a request does not mean reproducing it exactly
Running a request again can help you compare changes, but it does not guarantee that the original response will be reproduced. A model may produce variations; in addition, the application state, retrievable documents, index version, external tool content, or service configuration may have changed. A later run may follow similar spans and still not be an exact reproduction.
For a more informative comparison, securely and narrowly record the application version, relevant configuration, model identifiers exposed by the integration, index state or version when known, and versions of your own tools. Also note the time and environment. Keep test inputs controlled, using synthetic or authorized content when the objective allows. If an external dependency does not provide a version or snapshot, state that limitation in the analysis.
Distinguish between rerunning a request against the current system and reproducing a historical execution with the same dependencies and state. The first helps you observe current behavior; the second requires retaining and restoring more conditions, and may be impractical or inappropriate if it involves retaining sensitive data. Do not call a test “reproducible” just because it reuses the same input text. Describe what stayed the same, what may have changed, and what comparison the evidence can support.
OpenTelemetry GenAI: a useful foundation, still in development
OpenTelemetry publishes semantic conventions for generative AI systems that cover events, exceptions, metrics, and spans related to models and agents. Their value is to provide shared vocabulary and make it easier for different instrumentation to represent comparable operations. The project's documentation marks these conventions as “Development.” They are therefore a useful reference for evaluating names and attributes, not a universal contract whose stability or complete adoption can be assumed.
Before building dashboards, alerts, or exports around specific attributes, review the version of the conventions and the implementation used by each SDK. Check which fields are emitted, how they are named, whether they include content, and which settings change capture. Two instrumentors may cover similar hierarchies but differ in names, values, redaction options, export, or buffer management. That variation makes it necessary to test interoperability and document the mapping instead of assuming it.
The OpenAI Agents SDK documentation describes a hierarchy of spans for agents, generations, and tools, along with options related to sensitive data, export, buffering, and redaction. It also warns that disabling tracing does not necessarily remove data already in a buffer. This illustrates a general precaution: an off switch should not be treated as a mechanism for retroactive deletion. Verify behavior in the specific version and consider every place where data may remain.
The available sources do not provide enough information to state what is captured by default in every official SDK or instrumentor, or to compare two implementations and their options exhaustively. That answer must come from the documentation for the deployed version and a controlled test. Until it has been verified, take the cautious approach: inspect exported content and explicitly configure data reduction.
What to check before adopting a convention
The convention guides the schema; testing the implementation confirms its actual behavior.
| Aspect | Practical check | Caution |
|---|---|---|
| Status and version | Identify the versions of the conventions and SDK. | Development status may mean changes are still possible. |
| Coverage | Compare the spans, events, metrics, and exceptions emitted. | A named category does not guarantee that every instrumentor implements it. |
| Sensitive content | Inspect a test export and try redaction. | Do not infer default values from a general description. |
| Export and buffering | Verify what is exported and what may be stored temporarily. | Disabling tracing is not the same as deleting data already stored. |
Checklist for instrumenting an application
Start with a specific operational use case: locating latency, retrieval failures, tool errors, or validation rejections. Map the path and agree on stable span names. Check that context propagates between your own components and that a full request can be followed without putting unique identifiers in names or metrics. Record statuses and durations before considering content capture.
Review every attribute with a straightforward question: What operational decision will this enable? Does it contain sensitive information? How long should it be retained? Who will see it? If there is no clear answer, leave it out. Define redaction and filtering at the appropriate points in the pipeline, and test exceptions, retries, and export failures as well as normal operation. Configure permissions, retention, and sampling in line with risk and diagnostic needs.
Finally, run controlled tests with an empty retrieval result, a simulated tool error, a response rejected by validation, and a normal case. Check that spans distinguish the outcomes and that secrets or unapproved content do not appear in exports. Document known limitations, including the inability to repeat executions exactly when dependencies change. Review the policy regularly: instrumentation that suited one flow may no longer be appropriate after adding agents, tools, or new types of data.
Operational review before deployment
Use this checklist as a review gate and retain evidence of the tests performed.
- 01The path includes input, retrieval, generation, tools, validation, and output wherever they exist.
- 02Each important span has a stable name, an understandable relationship, a duration, and a status.
- 03Metrics use bounded dimensions and do not include unique execution or user identifiers.
- 04Prompt, document, and argument capture is disabled unless there is a justified and approved need.
- 05Redaction and filtering are tested before export, including on error paths.
- 06Access, retention, buffers, destinations, and sampling have documented owners and limits.
- 07The test distinguishes observed facts from hypotheses and records which dependencies prevent exact reproduction of an execution.
Open questions
- The supplied sources do not establish what content is captured by default in each SDK or instrumentor, or provide an exhaustive comparison of two official implementations; review the documentation for the deployed version and test its exports.
- The availability, names, and meanings of attributes for tokens, models, retrieval, or tools depend on the integration and the version of the conventions adopted.
- Exact reproduction cannot be guaranteed when the model or external dependencies do not provide a version or state that can be retained and restored.
- The effective point of redaction depends on the architecture: a Collector transformation may act before export from that component, but does not prove that the data was not captured or stored earlier.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction