One-sentence definition
Entrenamiento que obtiene sus señales de supervisión de la propia estructura de los datos, por ejemplo prediciendo partes ocultas de un texto.
Definition: Supervision Created from Data
Self-supervised learning is a machine-learning approach in which a system obtains its training signal from the structure or content of the data itself, rather than relying on labels specifically annotated by people for every example. One common method is to hide, transform, or split a sample and train the model to predict one part from another. The resulting prediction task is often called a pretext task or a self-supervised objective.
The word “self-supervised” describes where the signal used during a particular stage of training comes from. It does not mean that a model learns without any human involvement, design choices, or evaluation. Someone selected the data, defined the objective, chose which transformations to apply, and decided how to measure the result. Those choices may not require a manual label for each individual item, but they still affect what the system learns.
Nor does the term mean that a dataset contains no labeled information at all. A project can combine stages: first, it can learn representations from unannotated data using self-supervised objectives; later, the model can be fine-tuned or evaluated on labeled examples. It is therefore worth asking which stage the label “self-supervised” describes and which data were used at each stage.
The useful definition is operational: if the training objective is constructed from a sample or from relationships among samples, without requiring a specific human annotation for that objective in every case, the method may be self-supervised. That alone does not determine the architecture, model size, quality of its representations, or performance in a later application.
How It Works: From a Sample to an Evaluatable Representation
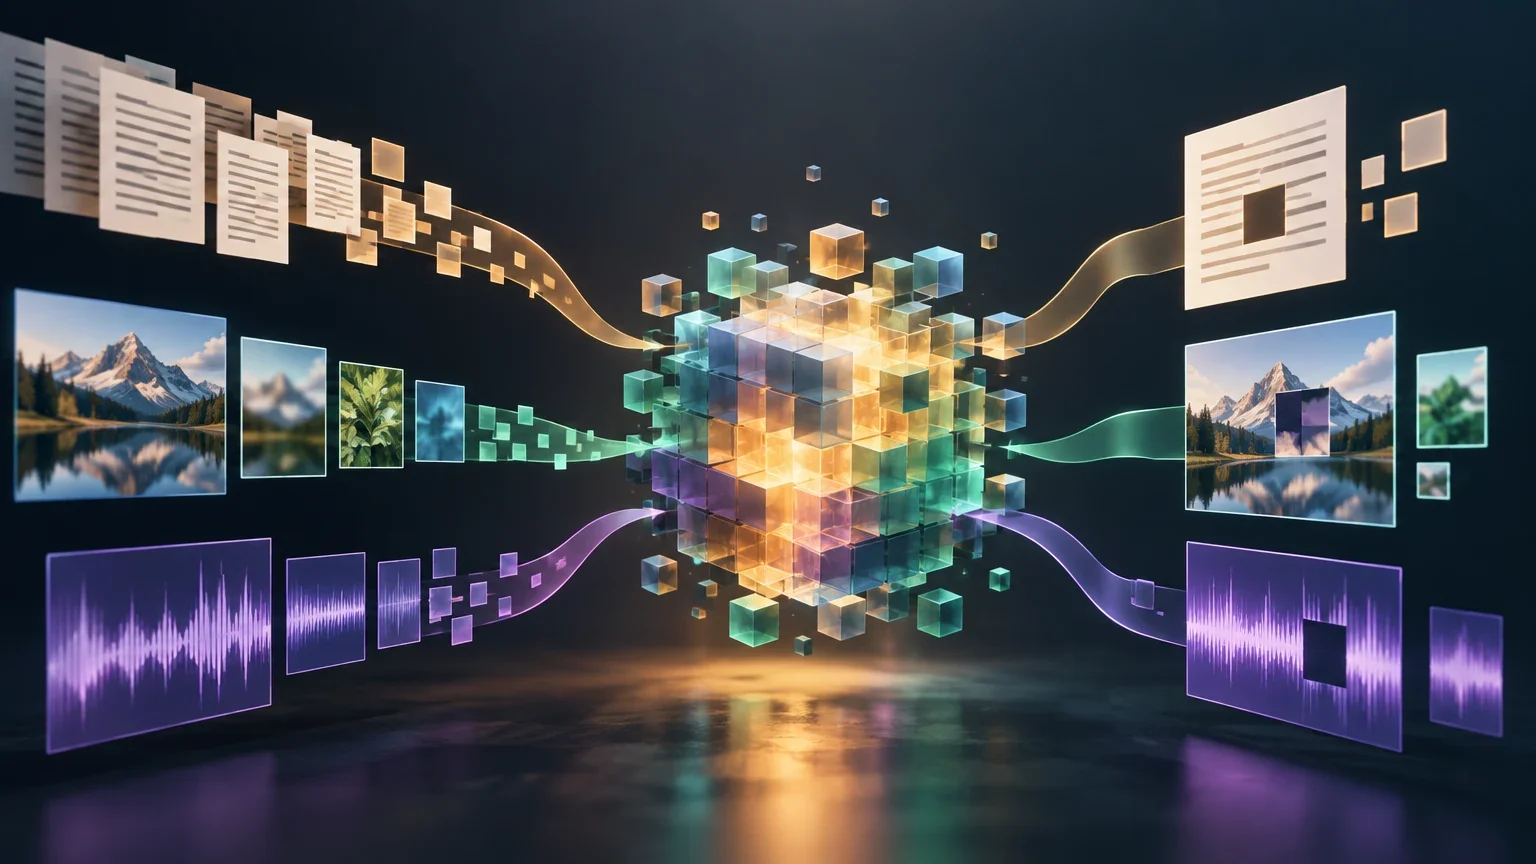
A self-supervised workflow can be described in three steps. First, decide which relationship within the data will be useful for training: for example, which word might occupy a hidden position, which two views come from the same image, or which pieces of audio correspond to a masked representation. Second, the model makes predictions and is optimized to bring them closer to the objective derived from the data. Third, check what it has learned: evaluate the model, reuse its representations, or fine-tune its parameters on data from a specific task.
A learned representation is an internal description of the data that a model uses to solve its training task. It may be useful for other problems, but transfer is not automatic. A representation that helps distinguish the relationships emphasized by a pretext objective may not preserve the information needed for a different task. Later evaluation should therefore match the intended use of the system.
A pretext task is not a neutral formality. If part of the data is hidden, someone chooses what to hide; if two views are generated, someone chooses which transformations to apply; if examples are contrasted, someone defines what counts as positive or negative. These choices emphasize certain regularities. As a practical consideration, the greater the distance between the regularity learned and the performance required by the application, the more important it is to measure transfer directly.
The Workflow
- 01Select the data and define which structure or relationship will serve as the signal.
- 02Construct the objective: hide, transform, pair, or contrast parts of the data.
- 03Train the model to solve that objective without requiring a specific manual label for each example.
- 04Evaluate the representation on relevant tasks and, if appropriate, fine-tune it with labeled data.
- 05Review errors, coverage, and potential differences between the training data and the intended use.
Language Example: Predicting Masked Tokens with BERT
BERT offers a technical example of self-supervised language modeling. In its masked language modeling objective, some tokens in a sequence are hidden, and the model is trained to predict them using the available context. This creates a prediction task from the text itself, rather than asking a person to manually annotate the correct word at every position.
For example, given a sentence such as “The scientist published the result in the [masked]”, the model must use the words around the gap to estimate which token was hidden. This is a schematic example: training processes many pieces of text, and the objective is to recover the masked positions. BERT also presented a next-sentence prediction task in its original pretraining setup; that additional task should not be confused with the general definition of self-supervised learning.
The objective teaches the model to use textual context to make the proposed predictions. It does not, by itself, show that the system understands a sentence as a person would or that it can answer every question accurately. For an application, its behavior would need to be evaluated on relevant tasks, and it would be necessary to check whether later fine-tuning improves the capabilities that matter.
Vision Example: Comparing Image Views with SimCLR
In computer vision, an approach can create two transformed versions of the same image and train a model to relate their representations within a learned space. SimCLR is an example of contrastive learning for visual representations: its objective uses pairs of transformed views, and the composition of those transformations influences the task the model ends up solving.
Imagine a photograph of a bicycle. The method creates two views of it using chosen transformations. Training aims to make the model recognize the relationship between these views as belonging to the same image, in contrast with other samples in the batch. A manual label such as “bicycle” is not necessarily provided to construct this objective. The relationship between the views is the training signal.
The choice of transformations matters. If two versions preserve features relevant to the intended use, the task may encourage representations useful for that use; if they remove or distort important information, the objective may emphasize different properties. This does not let us conclude in advance that any set of transformations will be suitable: their effects on the domain need to be examined, and the model needs to be evaluated on the specific tasks.
Consequently, “the model learned from unlabeled images” is an incomplete description. To interpret the result, it is useful to know which transformations were used, how the comparison was defined, and which later tests were used to measure transfer.
Audio Example: Speech Representations with wav2vec 2.0
Self-supervised learning also applies to speech. wav2vec 2.0 learns representations from audio without requiring transcripts to construct its pretraining objective. At a high level, it calculates latent representations of the audio, masks some of them, and trains the system with a contrastive task to identify the corresponding target representations.
This procedure can learn acoustic regularities from recordings without transcribing every segment. The representations can later be used or fine-tuned for tasks that do require text references, such as automatic speech recognition. Transcribed data may be involved in this later step; the presence of a subsequent labeled stage does not change the fact that the earlier objective was self-supervised.
This distinction matters when describing a complete system. Saying that a speech model was pretrained in a self-supervised way does not tell us how many transcripts were used for fine-tuning, how the model was evaluated, or what performance it achieves across different accents, recording conditions, or languages. Those questions require additional information and tests; they cannot be inferred from the method’s name alone.
Related Concepts That Are Not Synonyms
Unsupervised learning is a broad term for methods that seek structure in data without conventionally supplied target labels. Self-supervised learning is often treated as a related approach: it constructs a prediction signal from the data. The categories can overlap depending on the field and how the terms are used, so it is more precise to explain the specific objective than to rely only on a general label.
Semi-supervised learning combines labeled and unlabeled data in the learning process. It is not synonymous with self-supervised learning. FixMatch, for example, describes a semi-supervised method that uses labeled data and exploits unlabeled data through consistency and pseudo-labels. A self-supervised method, by contrast, can generate its objective from the data without needing a specific manual label for every example used for that objective.
A pseudo-label is a label generated by a model or procedure and used as a target for other examples; it is not automatically equivalent to a self-supervised signal derived directly from the structure of a sample. Some semi-supervised methods use pseudo-labels as part of their strategy. The origin and use of the label are what need to be described.
Pretraining names a stage in a model’s lifecycle, not a single way of learning. It can be carried out using self-supervised objectives, but “pretrained” does not necessarily mean “self-supervised.” Similarly, a self-supervised objective can be used without the word pretraining fully describing the system. A learning paradigm and a training stage answer different questions.
A Guide to Distinguishing the Terms
| Term | Question It Answers | Practical Distinction |
|---|---|---|
| Self-supervised | Where does the training objective come from? | From relationships or structures derived from the data itself. |
| Semi-supervised | What combination of data is used? | Combines labeled and unlabeled data; it may use pseudo-labels. |
| Pseudo-labeling | How is a label assigned to an example? | A generated label is used as a target; this can be part of a semi-supervised method. |
| Pretraining | At what stage is the model trained? | A stage before another use or fine-tuning; it does not, by itself, specify the type of supervision. |
Limitations, Biases, and Common Misconceptions
A self-supervised objective may be easy to optimize and still fail to teach what a final task requires. The quality of a representation or the result on an evaluation of the pretraining task is not universal proof of good performance on later tasks. Transfer needs to be checked with evaluations suited to the intended use, rather than assumed from a single score.
The absence of manual labels for the objective does not eliminate bias either. Data may reflect imbalances in coverage, capture errors, historical conventions, or differences among the populations represented. Corpus filtering, applied transformations, example selection, and evaluation criteria are decisions that can influence results. “Self-supervised” is not a guarantee of neutrality.
Another common mistake is to present this approach as completely autonomous learning. Even when the signal is derived from the data, someone must choose the corpus and objective, train the system, and decide what counts as a satisfactory result. It is also incorrect to infer that a model used no labeled data at any stage just because its pretraining was self-supervised.
Finally, the ability to solve an auxiliary task should not be confused with practical usefulness. Predicting masked tokens, relating visual views, or learning audio representations are defined objectives. Each reveals something about what the system optimized, but none replaces evaluation of accuracy, robustness, or suitability in the target context.
Practical Criteria for Interpreting a Claim
When someone says a model learned in a self-supervised way, first ask what objective was constructed from the data: were elements hidden, transformations compared, or representations masked? Then identify which stage used that objective and whether later fine-tuning used labels. This separation avoids conflating a learning paradigm with a model’s lifecycle.
Next, review which data and transformations were involved. The task may reflect useful regularities, but it may also reflect the limitations of the corpus and design choices. Check which evaluation supports transfer to the application you care about; a pretraining result alone is not enough to establish it.
To compare methods, describe the training signal and evaluation conditions before comparing names. In a glossary comparison or comparison guide, keep the categories of self-supervised learning, semi-supervised learning, and pretraining distinct. To explore other glossary concepts, consult related entries, such as self-supervised learning, and the architecture or evaluation terms that help explain the complete system.
In practice, a rigorous description should specify what served as the objective, which data were used, which transformations or relationships generated the signal, which later stages incorporated labels, and how final performance was evaluated. If any of these pieces is undocumented, conclusions should be limited to what is actually known. The final rule is simple: “self-supervised” explains how a training signal was obtained; it does not guarantee what a model will learn or how it will behave beyond that task.
A Short Checklist
- 01Identify the objective derived from the data.
- 02Separate pretraining, fine-tuning, and evaluation.
- 03Check whether labeled data were used at other stages.
- 04Examine corpus coverage and the role of transformations.
- 05Look for results on later tasks and conditions relevant to the intended use.
- 06State conclusions without turning the method’s label into a guarantee.