One-sentence definition
Situation in which a model overfits the training data and loses performance on new cases.
Precise Definition: The Inability to Generalize
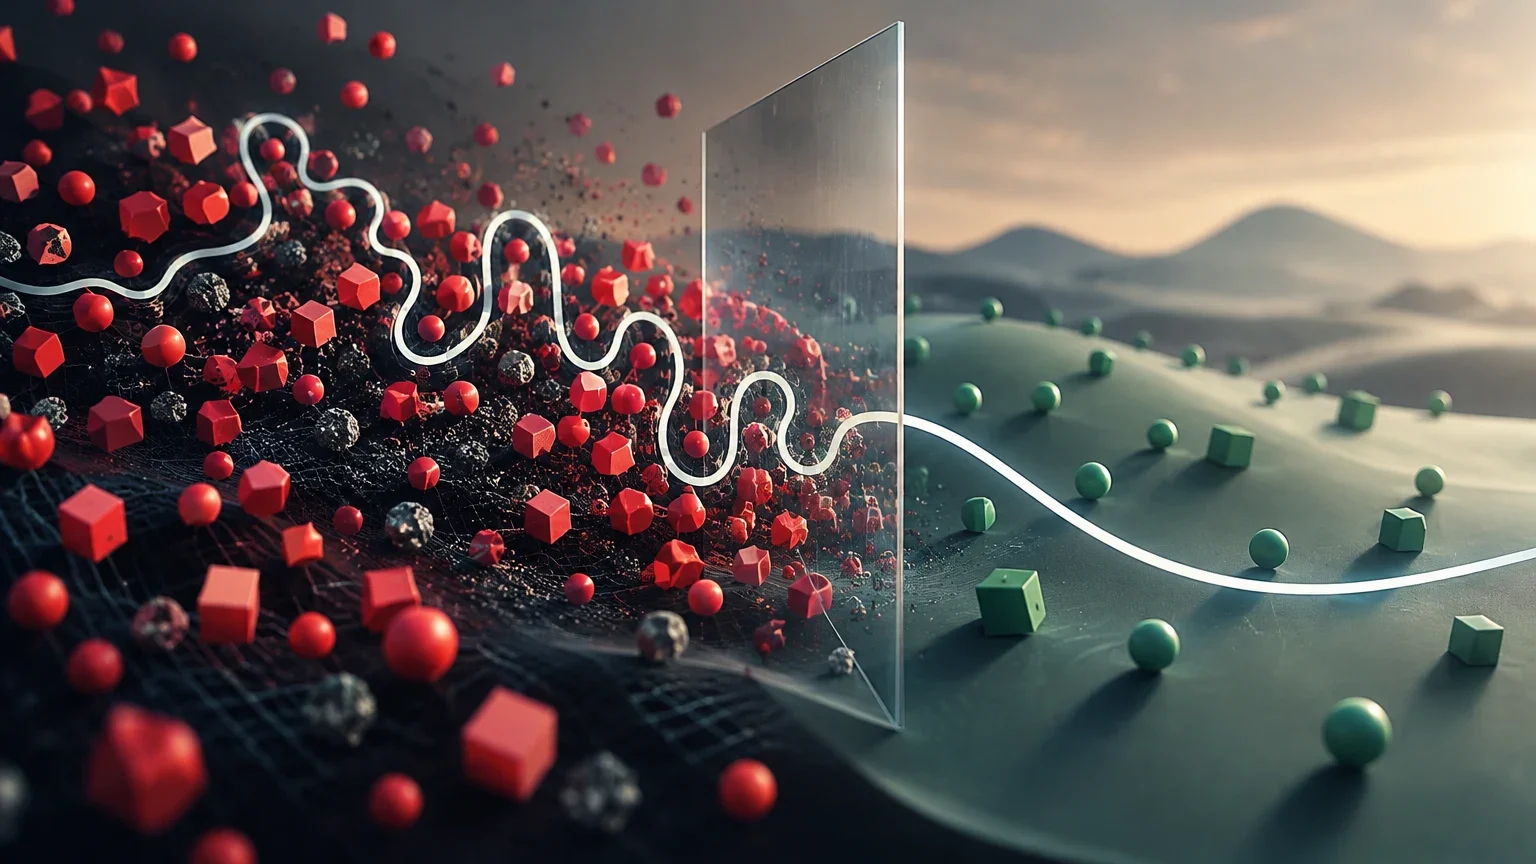
Overfitting is a phenomenon in machine learning where a model fits the training data excessively, capturing not only the underlying signal but also the noise, anomalies, and random patterns specific to that dataset. As a result, the model exhibits excellent performance on the data it was trained on, but its predictive capability degrades significantly when faced with new, unseen data. This inability to generalize negates the fundamental purpose of a predictive model, which is to extrapolate knowledge to real-world situations.
Technically, an overfit model exhibits high variance and low bias. High variance indicates that the model's predictions are extremely sensitive to variations in the training set; small changes in input data can cause large changes in output. Low bias, on the other hand, reflects that the model is flexible enough to capture the complexity of the data, but that same flexibility prevents it from distinguishing between the true trend and statistical noise. Generalization is, therefore, the opposite objective of overfitting: a model generalizes well if its predictions are accurate and consistent on both training and validation/test data.
Technical Mechanism: The Bias-Variance Tradeoff
To understand overfitting, it is necessary to analyze the bias-variance tradeoff. The total error of a predictive model can be decomposed into three components: squared bias, variance, and irreducible noise. Bias measures the error introduced by assuming the form of the target function is simple (e.g., linear) when it is actually complex. Variance measures the model's sensitivity to fluctuations in the training set. A high-variance model will learn different patterns if trained on a slightly different subset of the data.
In practice, as model complexity increases (e.g., adding more layers to a neural network or increasing the depth of a decision tree), bias decreases because the model can capture more complex relationships. However, variance increases. Overfitting occurs when model complexity exceeds the optimal point, known as the 'sweet spot,' where the sum of bias and variance is minimal. In this zone, the model has learned to memorize noise rather than signal, which manifests operationally as a divergence between training and validation metrics.
Comparison of Model Fit States
Decision table to identify the model state based on its metrics and statistical characteristics.
| Model State | Bias | Variance | Training Performance | Validation/Test Performance | Primary Cause |
|---|---|---|---|---|---|
| Underfitting | High | Low | Low | Low | Model too simple or insufficient training |
| Optimal Fit | Low | Low | High | High | Complexity adequate to data signal |
| Overfitting | Low | High | Very High | Low | Model too complex or insufficient/noisy data |
Operational Detection: Learning Curves and Validation
Early detection of overfitting is critical to avoid deploying ineffective models. The most common tool is observing loss curves during training. Two main metrics are plotted: the loss on the training set and the loss on the validation set, as a function of the number of iterations or epochs. In a well-fitted model, both curves converge and remain stable. In an overfit model, the training curve continues to descend (or stays at a very low value), while the validation curve reaches a minimum and begins to rise. This point of divergence is the unequivocal signal that the model has begun to memorize noise.
In addition to curves, cross-validation (k-fold) is a robust method for evaluating model stability. In this process, data is divided into k subsets. The model is trained k times, each time using k-1 subsets for training and the remaining one for validation. If the average cross-validation performance is significantly lower than the performance reported on the full training set, there is a high probability of overfitting. This method is especially useful when the dataset is small, as it maximizes the use of available data for evaluation.
Detection Protocol via Cross-Validation
Steps to implement k-fold cross-validation to diagnose overfitting.
- 01Divide the training dataset into k folds of equal size, ensuring stratified class distribution if it is a classification problem.
- 02For each iteration i (from 1 to k), reserve fold i as the validation set and use the remaining k-1 folds to train the model.
- 03Evaluate the model on the validation fold and record the error metric (e.g., MSE, Accuracy, F1-score).
- 04Repeat the process until each fold has served as the validation set.
- 05Calculate the mean and standard deviation of the obtained metrics. A high standard deviation indicates model instability (high variance).
- 06Compare the cross-validation mean with the training metric. If the difference is significant, overfitting is confirmed.
Applied Examples in Specific Domains
Overfitting is not just a theoretical problem; it has serious operational consequences in critical industries. In financial fraud detection, a model trained on transactions from a specific month may memorize temporal patterns or user idiosyncrasies of that period. If the model is deployed and fraud patterns evolve or market conditions change, the model will fail to recognize new fraud modalities, as it has learned to classify based on the temporal noise of the training set rather than the structural signals of fraud.
In medical image diagnosis, overfitting can be dangerous. A model trained to detect tumors in MRI scans may learn to associate the presence of a tumor with specific scanner artifacts, patient position, or the acquisition protocol of a specific institution. If the model is applied in another hospital with different equipment, it may generate false positives or negatives because it is detecting the 'noise' of the original scanner rather than the actual pathology. Similarly, in logistics demand forecasting, a model that overestimates delivery capacity on holidays due to atypical historical data (such as a one-off strike) will make erroneous inventory decisions in future years, generating overcosts or stockouts.
Common Confusions: Overfitting vs. Underfitting and Data Leakage
It is common to confuse overfitting with underfitting. Underfitting occurs when the model is too simple to capture the complexity of the data. Unlike overfitting, where the model fails on new data but succeeds on training data, underfitting fails on both sets. An underfit model has high bias and low variance; it is unable to learn the dominant trend of the data. The solution to underfitting usually involves increasing model complexity or providing more data, while the solution to overfitting involves reducing complexity or regularizing.
Another critical confusion is between overfitting and data leakage. Data leakage occurs when information from the test or validation set accidentally filters into the training set. This artificially inflates performance metrics, making the model appear to generalize well when it has actually 'seen' the answers. Unlike overfitting, which is a model capacity problem, leakage is a data engineering error. A contaminated model may have low apparent variance and bias, but its real-world performance will be catastrophic because it has not learned to generalize, but to memorize the labels of the test data.
Mitigation and Inherent Limits of Evaluation
Several techniques exist to mitigate overfitting. Regularization (L1/Lasso and L2/Ridge) adds a penalty to the loss function for large coefficients, forcing the model to be simpler. Dropout, in neural networks, randomly deactivates neurons during training, preventing the model from relying on specific pathways. Early stopping halts training when validation loss stops improving, preventing the model from memorizing noise. Data augmentation generates artificial variations of training data, increasing diversity and reducing variance.
However, these techniques have limits. Evaluation on unrepresentative test sets can give a false sense of security. If the test set is not stationary or does not reflect the real distribution of production data, the model may appear to generalize well in validation but fail in production. Furthermore, in problems with non-stationary data (such as financial time series or consumption trends), overfitting is harder to mitigate because the data distribution changes over time. In these cases, time-series cross-validation is preferable to random cross-validation, as it respects the temporal order of the data.
Mitigation Techniques and Their Impact
Summary of the main techniques to combat overfitting and their mechanism of action.
| Technique | Mechanism of Action | Typical Application | Associated Risk |
|---|---|---|---|
| L1/L2 Regularization | Penalizes large coefficients, reducing model complexity. | Linear regression, neural networks. | Can underfit if penalty is excessive. |
| Dropout | Randomly deactivates neurons, forcing redundancy. | Deep neural networks. | Requires fine-tuning of dropout rate. |
| Early Stopping | Stops training when validation worsens. | Iterative models (neural nets, gradient boosting). | Can stop too early if noise is high. |
| Data Augmentation | Generates synthetic data to increase diversity. | Computer vision, NLP. | Synthetic data may not capture real variability. |