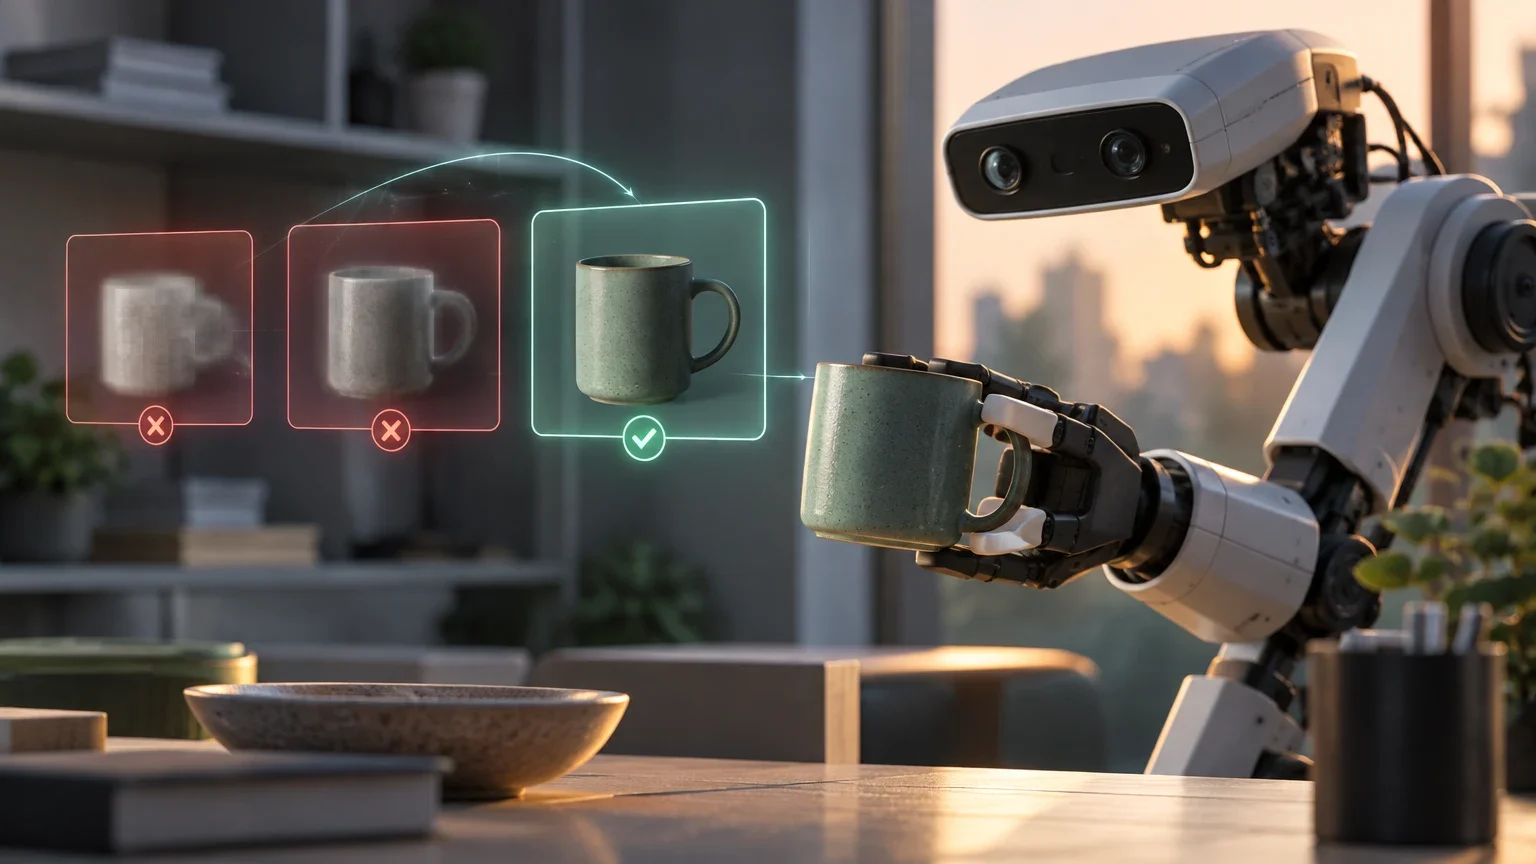
The problem of imprecise robotic memory
In an emergency scenario, a robotic assistant might need to locate a wall-mounted defibrillator. However, if the robot has incorrectly labeled that device as a fire extinguisher in its stored memory, it will not know where to find the life-saving equipment. This type of perceptual error persists if the system lacks a mechanism to correct itself.
Mobile robots capture images of their environment with onboard cameras, but they often see objects partially, from a distance, or under poor lighting conditions. In these cases, computer vision models can generate erroneous descriptions, such as mistaking a gray chimney for a squirrel on a rooftop. Without a way to rectify this, the incorrect memory impacts the robot's downstream applications.
A mistaken label can therefore become more than a one-time vision error: it can persist as part of the robot’s stored map and shape later decisions. The emergency example shows why the distinction between recognizing an object and remembering where it is matters. If the stored description is wrong and the system has no way to revisit or revise it, the robot may fail to retrieve the relevant location when it needs that information.
Partial views, distance, and poor lighting make the robot’s observations incomplete, so a description may reflect uncertainty in what the camera captured rather than the object itself. Once that description enters memory, later applications can rely on it as though it were correct. The central problem is thus not only an initial misidentification, but also the persistence of that error in a map used by the robot.
UQ-DAAAM architecture
The new system, named UQ-DAAAM (Uncertainty Quantification for Describe Anything, Anywhere, at Any Moment), builds on the prior work DAAAM. The latter uses a vision-language model (VLM) to richly describe objects in scenes captured by the robot and stores these descriptions in a 3D map-based representation.
UQ-DAAAM integrates uncertainty quantification into this framework. The system compares multiple descriptions of the same object seen from different angles to measure the robot's confidence in what it saw. By fusing the VLM's confidence and the consistency between views, the system generates a single number that captures the global certainty about the object.
The 3D map-based representation connects descriptions to objects and their positions in the robot’s mapped environment. UQ-DAAAM retains this descriptive-memory foundation and adds a way to assess whether different observations support the same account. Agreement across views and the VLM’s confidence are combined, rather than treating one description as sufficient on its own.
The resulting certainty value summarizes the system’s assessment of an object, but it does not make the original observation infallible. Its role is to indicate when the stored description may need further refinement. This distinction matters because uncertainty quantification identifies a possible weakness in memory; the later refinement process is what attempts to address it.
Detection and correction mechanism
When the uncertainty number exceeds a certain threshold, UQ-DAAAM activates a refinement process. The system uses a mathematical heuristic to select additional views that will reduce uncertainty without needing to re-run the full vision-language model, which drastically reduces the computational load.
Once the additional views are identified, the system employs a large language model (LLM) to fuse the new descriptions with the existing ones. To improve accuracy, the LLM gives more weight to the new descriptions and those with less ambiguity. This process allows the robot to update its memories in real time as it moves through the environment.
The threshold provides the condition for starting refinement: the system does not invoke the additional-view process for every stored description, but when its uncertainty measure is high enough. The heuristic then selects views intended to reduce that uncertainty. This is a targeted selection step, not a claim that the selected images will always remove ambiguity.
The computational saving comes from selecting additional views without rerunning the full vision-language model. After those views produce new descriptions, the LLM combines them with the existing descriptions, giving greater weight to newer and less ambiguous descriptions. The robot can then update its stored account while it continues moving, although the stated process does not by itself guarantee that every update is correct.
Memory correction flow
Step-by-step process for correcting object descriptions.
- 01The robot captures multiple images of the same object from different angles.
- 02The system calculates the VLM's confidence and the consistency between descriptions.
- 03If uncertainty exceeds the threshold, additional frames are selected via heuristic.
- 04An LLM fuses the descriptions, prioritizing those with less ambiguity.
- 05The robot's memory is updated with the corrected description.
Results and accuracy
In the tests conducted, the refinement step was able to resolve ambiguities for approximately 92 percent of the objects in the robot's environment. This process only required two additional descriptions per object to achieve the correction.
Compared to baseline methods, UQ-DAAAM increased the robot's confidence and improved the accuracy of its answers to questions about objects, their locations, and when it last saw them. The accuracy of object descriptions increased by 5 percent compared to the previous state of the art.
The reported 92 percent refers to objects for which the refinement step resolved an ambiguity in the tested robot environment; it is not a general success rate for all objects or operating conditions. The reported requirement of two additional descriptions per object describes the process used to obtain those corrections. Both figures characterize the reported tests, rather than guaranteeing the same outcome in other settings.
The five percent improvement concerns the accuracy of object descriptions compared with the previous state of the art. Separately, the researchers report better answers to questions about objects, their locations, and when the robot last saw them. These results describe different aspects of performance: a change in description accuracy and improvements in answers about remembered objects and observations.
UQ-DAAAM performance metrics
Comparison of results reported by the researchers.
| Metric | Reported result |
|---|---|
| Objects with resolved ambiguity | 92% |
| Additional descriptions per object | 2 |
| Improvement in description accuracy | 5% over state of the art |
Applications and limitations
Luca Carlone, an associate professor at MIT and the senior author, emphasizes that allowing a robot to know what it does not know is essential for this technology to be deployed safely. Unlike conversational language models, in physical AI a disclaimer is not enough; the robot must actively manage its uncertainty.
The researchers plan to apply UQ-DAAAM to different types of robots, such as mobile manipulators, and use uncertainty quantification to identify areas of high uncertainty that the robot could revisit. The work was presented at the Conference on Neural Information Processing Systems (NeurIPS) and is supported in part by the U.S. Army Research Laboratory and the U.S. Office of Naval Research.
For a robot acting in the physical world, identifying uncertainty can inform whether its memory should be treated cautiously or refined, rather than relying on a verbal disclaimer. Carlone’s point is that the robot needs to manage uncertainty actively. The approach described here does so by detecting uncertain descriptions and initiating a process to gather and combine additional views.
The researchers’ planned applications include mobile manipulators and revisiting areas that the system identifies as highly uncertain. These are stated directions for applying the method, not results that establish performance across different robot types. The work’s presentation at NeurIPS and its partial support from the U.S. Army Research Laboratory and the U.S. Office of Naval Research provide context for the research, but do not by themselves establish deployment readiness.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction