Introduction: What is AA-LCR and Why It Matters
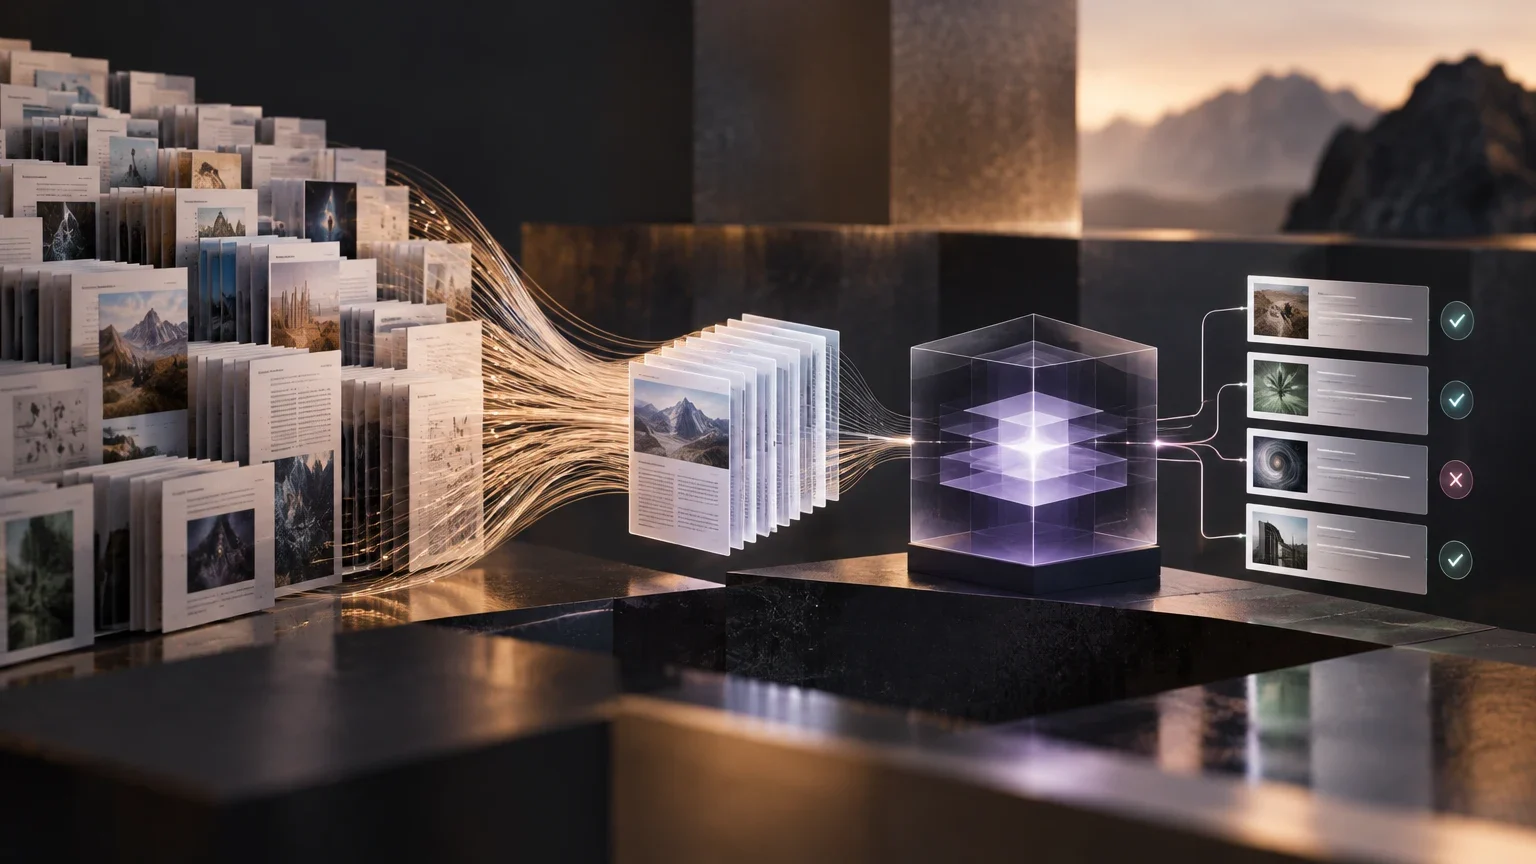
The Artificial Analysis Long Context Reasoning (AA-LCR) benchmark is designed to evaluate the ability of language models to perform reasoning over extensive contexts, going beyond simple information retrieval. Unlike retrieval tests, which measure the capacity to locate a specific data point within a text, AA-LCR requires the model to synthesize information scattered across multiple sources to arrive at an answer that is not explicitly present in any individual document.
This distinction is crucial for engineers and system architects implementing document analysis tasks, understanding complex codebases, or multi-step workflows. The relevance of AA-LCR lies in its focus on real knowledge work, where cross-inference is more valuable than mere data extraction. By replicating these tasks, the benchmark offers a metric closer to production applications than traditional long-context tests.
The cognitive demand placed on the model extends beyond simple logical deduction to encompass the management of conflicting or redundant information inherent in real-world document sets. Unlike synthetic benchmarks where data points are isolated, AA-LCR forces the system to navigate a dense web of interrelated facts, requiring the model to filter out noise and identify the specific subset of data relevant to the query. This mirrors the complexity of professional environments where information is rarely presented in a clean, linear format, but rather scattered across disparate reports, legal filings, and marketing materials that may contain contradictory figures or overlapping narratives.
For system architects, this distinction highlights a critical gap in traditional long-context evaluations that often fail to capture the nuance of multi-document synthesis. The ability to perform cross-inference is not merely a matter of processing speed or memory capacity, but a reflection of the model's underlying reasoning architecture. By focusing on tasks where the answer is not explicitly stated, AA-LCR provides a more robust indicator of a model's potential to handle complex, multi-step workflows in production settings, where the value of the system lies in its ability to derive new insights from existing data rather than simply retrieving it.
Benchmark Architecture: Documents and Questions
The structure of AA-LCR is based on a set of 100 high-difficulty questions that require the processing of approximately 100,000 input tokens per question. These tokens come from a corpus of around 230 to 234 real documents, covering seven main categories: company reports, industry reports, government consultations, academia, legal, marketing materials, and surveys.
The design of the questions is rigorous: each one has been verified by humans to ensure it requires genuine inference. For example, a question might ask for the adjusted EBITDA of a specific company after a 13.5% drop in operating income, forcing the model to cross-reference financial data from multiple quarters and press documents. This complexity ensures that only models with context windows of at least 128K tokens can participate competitively.
The selection of the seven document categories is deliberate, aiming to replicate the heterogeneity of information sources encountered in enterprise and research contexts. Company reports and industry analyses provide structured financial and operational data, while government consultations and legal documents introduce regulatory and compliance nuances. The inclusion of academic papers and marketing materials further diversifies the linguistic and structural patterns the model must process, ensuring that the benchmark tests not only numerical reasoning but also the ability to interpret varied rhetorical styles and document formats.
The requirement for a minimum 128K token context window is not arbitrary but is directly tied to the density of the corpus. With approximately 100,000 tokens per question, the model must maintain a coherent understanding of the entire document set to perform the necessary cross-referencing. This constraint effectively filters out models that rely on short-context approximations or retrieval-augmented generation techniques that might miss critical details buried deep within the input. The human verification of each question ensures that the inference required is genuine, preventing the benchmark from degenerating into a simple lookup task that could be solved by less sophisticated models.
AA-LCR Corpus Structure
Summary of the main components of the benchmark according to the official methodology.
| Component | Detail |
|---|---|
| Questions | 100 text-based reasoning questions |
| Documents | ~230-234 real documents from 7 categories |
| Tokens per question | ~100,000 input tokens |
| Context requirement | Minimum 128K token context window |
v1.1 Evaluation Methodology and the Role of the Judge
The evaluation of AA-LCR is conducted independently by Artificial Analysis, ensuring the neutrality of the process. A fundamental technical aspect is the use of a language model as a judge (LLM-as-a-judge). In version v1.1, it has been observed that some providers, such as NVIDIA with its Nemotron Labs Dory 1.0 4B model, use corrected answer keys from version v1.1 but maintain an older judge model, introducing nuances in comparability.
The scoring protocol normalizes results on a scale from 0 to 1 (or percentage). The independence of the evaluation is key, although variability between judge model executions and potential preference for longer or specific style responses are inherent biases of this method. Reproducibility is affected if both the answer keys and the version of the judge model used for grading are not standardized.
The reliance on an LLM-as-a-judge introduces a layer of complexity that goes beyond simple binary scoring. The judge model must not only verify the factual accuracy of the answer but also assess the logical coherence of the reasoning process, a task that is inherently subjective and prone to variability. In version v1.1, the observation that some providers use corrected answer keys while retaining older judge models highlights a significant methodological challenge. This mismatch can lead to discrepancies in scoring that are not attributable to the candidate model's performance but rather to the evolving standards of the evaluation framework itself.
The normalization of scores to a 0-1 scale attempts to standardize results across different models and providers, but it does not fully eliminate the biases inherent in the judge's decision-making process. Variability in the judge's interpretation of ambiguous answers or its preference for certain response styles can introduce noise into the final scores, particularly in cases where the correct answer is not unique or where the reasoning path is complex. This underscores the importance of standardizing both the answer keys and the judge model version to ensure that comparisons are meaningful and that the benchmark remains a reliable tool for evaluating long-context reasoning capabilities.
AA-LCR Evaluation Flow
General steps of the scoring process in the benchmark.
- 01The candidate model processes the ~100k tokens of documents.
- 02The model generates an answer to the reasoning question.
- 03A judge model (e.g., Qwen3) evaluates the answer against the answer key.
- 04The score is normalized and aggregated to obtain the model's final score.
Limits and Biases in Long-Context Evaluation
The use of LLMs as judges introduces significant biases. These models may show a preference for more extensive answers or certain writing styles, which does not always correlate with factual accuracy. Additionally, variability between judge executions can generate noise in the scores, especially in questions where the answer is ambiguous or complex.
Another critical limit is data contamination. Since the AA-LCR documents are real and public, there is a risk that frontier models have seen these texts during their training. Although Artificial Analysis attempts to mitigate this, the generalization of results to unguaranteed production tasks is limited. The saturation of the leaderboard, where frontier models cluster in a narrow range of points, suggests that the benchmark is reaching its limits of discrimination.
The issue of data contamination is particularly acute in AA-LCR due to the use of real, public documents. Unlike synthetic datasets that are generated specifically for the benchmark, the corpus in AA-LCR consists of texts that are widely available on the internet and likely included in the training data of many frontier models. This creates a risk that the models being evaluated have already encountered the specific documents and questions, leading to inflated scores that do not reflect their true ability to reason over new, unseen contexts. While Artificial Analysis attempts to mitigate this risk, the extent of contamination remains difficult to quantify, and its impact on the generalizability of the results is a significant concern.
The saturation of the leaderboard, with top models clustering within a narrow range of points, further complicates the interpretation of results. When the differences between models are small, the noise introduced by judge variability and data contamination becomes more pronounced, making it difficult to distinguish between genuine improvements in reasoning capability and artifacts of the evaluation process. This saturation suggests that AA-LCR may be reaching its limits as a differentiator for frontier models, and that additional metrics or more challenging tasks may be needed to provide a more granular assessment of long-context reasoning performance.
Interpreting Results and Valid Comparisons
To interpret the AA-LCR leaderboard, it is essential to consider the execution conditions. Comparisons are valid only if performed under the same version of the benchmark and with identical inference conditions. Differences in quantization, the number of iterations (loops) in recurrent architectures, or the version of the judge model can invalidate direct comparisons.
In the case of NVIDIA Nemotron Labs Dory 1.0 4B, the model card indicates that the AA-LCR results (63/71/73 for 1/2/4 loops) are internal estimates that may deviate from the official Artificial Analysis scores. This underscores the need to complement AA-LCR with other metrics and to verify the independence of the evaluation before making deployment decisions based solely on this ranking.
The case of NVIDIA's Nemotron Labs Dory 1.0 4B illustrates the practical challenges of comparing results across different evaluation setups. The model's internal estimates, which show a significant improvement with increased loop counts, are based on a specific configuration of answer keys and judge models that may not align with the official Artificial Analysis leaderboard. This discrepancy highlights the importance of verifying the independence and standardization of the evaluation process before making deployment decisions. Relying solely on a single benchmark, especially one with known methodological uncertainties, can lead to suboptimal choices in model selection and system design.
To ensure valid comparisons, it is essential to consider the full context of the evaluation, including the version of the benchmark, the inference conditions, and the specific judge model used. Differences in quantization, loop counts, or judge versions can have a significant impact on the final scores, and these factors must be accounted for when interpreting the results. By complementing AA-LCR with other metrics and verifying the independence of the evaluation, engineers and architects can gain a more comprehensive understanding of a model's capabilities and make more informed decisions about its suitability for specific production tasks.
Open questions
- An exact and public normalization formula for the Qwen3 judge score in v1.1 that guarantees absolute reproducibility has not been confirmed.
- The degree of data contamination in the 234 documents used is not quantified in the available primary sources.
- The exact comparability between provider internal evaluations (such as NVIDIA's) and official Artificial Analysis evaluations remains a methodological uncertainty.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction