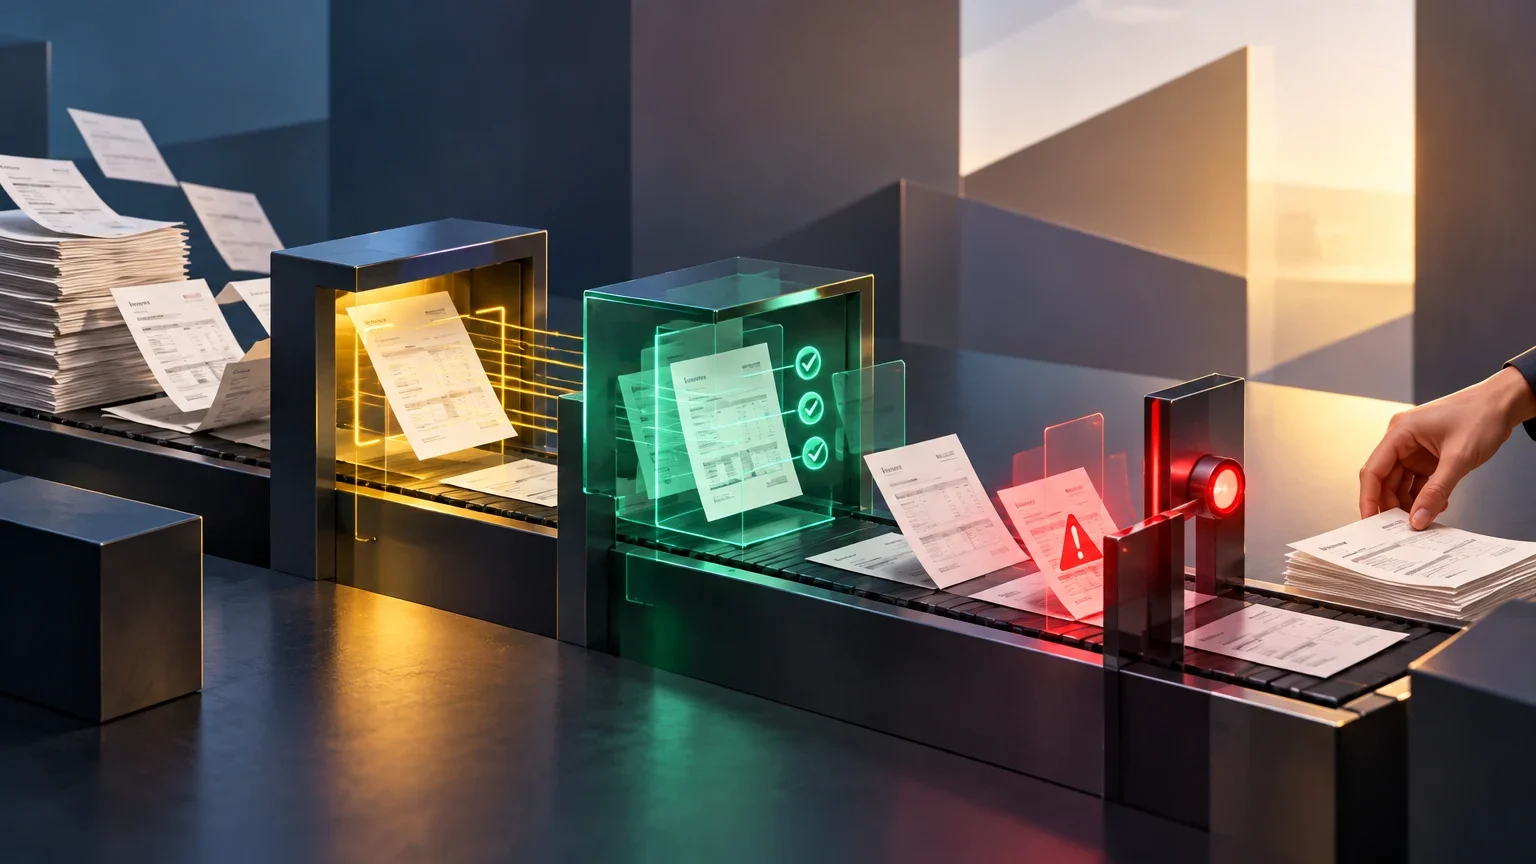
The financial workflow has four distinct stages
Automating invoice processing does not mean letting a model decide on its own what to record and pay. The workflow has four stages that should be kept separate: capturing the document, extracting data, validating that data, and approving or recording the transaction. Extraction turns a PDF or image into structured fields; validation checks those fields against business rules and systems; approval authorizes a decision that can affect money and accounting records.
This separation applies to both accounts payable (AP) and accounts receivable (AR), although the specific controls differ. AP often depends on the supplier, purchase order, delivery receipt, taxes, and spending authorization. AR may focus on the customer, agreed terms, and matching the invoice to the underlying transaction. In either case, a model can propose information, but deterministic rules and accountable staff should retain control over financial decisions.
A supplier invoice’s journey
Each stage should leave enough evidence to explain what happened and why the document proceeded or stopped.
- 01Receipt: retain the original document, identify its source channel, and prevent the same file from being processed twice.
- 02Extraction: convert relevant fields into structured data and preserve a reference to the source document.
- 03Validation: check calculations, supplier details, duplicates, applicable taxes, purchase orders, and defined tolerances.
- 04Approval and posting: authorize the transaction under internal policy and post it only after the required controls have passed.
First, classify document variability
Before choosing a technology, examine the actual corpus: what proportion consists of structured e-invoices, digital PDFs, scans, credit notes, multilingual documents, and unusual formats? The useful question is not whether an invoice “looks standard,” but whether its fields appear consistently enough to extract and validate with a predictable method. The available evidence does not support a universal percentage for documents with fixed structures; each organization should calculate its own figure from a representative sample of suppliers and accounting periods.
For stable, structured documents, a data import or direct integration may be simpler than adding a generative model. For PDFs and images with varying layouts, OCR and document-processing models can help locate fields and line items. Credit notes, poor-quality scans, documents with multiple tax rates, and new formats should be treated as distinct risk categories—not as variations the system can always handle without review. Microsoft documents fields its prebuilt model can extract and provides for custom models when standard fields are insufficient. That describes a specific tool, not a general guarantee for every document.
OCR, document models, and rules serve different purposes
OCR recognizes text in an image or document. A document-processing model can identify which text corresponds to an invoice number, supplier, or amount even when the visual layout changes. The structured output should be reviewable: some products provide confidence scores for individual fields, which can help route doubtful cases to a review queue. A confidence score does not prove that a value is true, nor does it automatically equal the actual probability that an invoice can be paid without risk.
Generative models can be useful for interpreting variable documents or proposing structured fields, but they are not the first choice for every task. Checking that the subtotal plus tax equals the total, or that an invoice exceeds an approval limit, is easier to reproduce and audit with a deterministic rule. A more cautious design combines flexible extraction where needed with explicit validation and an approval system; it does not replace financial controls with generated answers.
Which tool fits each task?
This is a design guide, not a performance benchmark. Test the selected configuration with your own documents.
| Task | Starting option | When to escalate or change |
|---|---|---|
| Read a scanned PDF | OCR or document processing | Review if the image is illegible or critical fields are not recognized. |
| Process a stable electronic format | Structured import or integration | Use document extraction if fields are missing or the format varies. |
| Validate calculations, limits, or duplicates | Deterministic rules | Route ambiguous matches or unanticipated exceptions for review. |
| Interpret a variable field or description | Document or generative model with structured output | Require downstream validation before recording financial data. |
| Authorize payment or resolve a discrepancy | Approval under policy by an assigned decision-maker | Do not delegate a material exception to automated extraction. |
Validate results with explicit rules
Validation should compare extracted data with internal sources the organization treats as authoritative: the supplier master, purchase order, delivery receipt, contract, chart of accounts, and tax rules applicable to the transaction. Useful controls include checking that required fields are present, recalculating amounts, detecting potential duplicates using multiple identifiers, and matching the invoice to the order and receipt when those records exist. Rules should be versioned and have an owner; an undocumented tolerance can become an automatic approval that is difficult to explain later.
Not every tax check is an arithmetic operation. Line totals can be verified deterministically, but tax treatment may depend on the transaction type, jurisdiction, and available documentation. If a rule has not been modeled and reviewed by the appropriate team, the workflow should stop or request human validation rather than treating the model’s interpretation as definitive tax guidance. Similarly, a potential duplicate should be held or blocked for review; an approximate match alone does not prove that two invoices are duplicates.
Deterministic controls before approval
Define the rules before enabling automatic posting to the ERP. At every stop, record the reason and the data used.
- 01Check that required supplier, invoice number, date, currency, and total fields are present.
- 02Recalculate line and tax totals under the rules applicable to the transaction, without replacing tax review for special cases.
- 03Search for duplicates using multiple fields and review uncertain matches.
- 04Match against a purchase order, receipt, or contract when that information is available.
- 05Check spending limits, segregation of duties, and required approvals.
- 06Record the result of each control and send exceptions to the responsible person or team.
Design human review around risk
Human review does not have to mean re-entering every invoice by hand. It can focus on critical fields, poor-quality documents, new suppliers, discrepancies, changes to bank details, and transactions above an approved limit. A useful exception queue should show the original document, extracted fields, completed validations, and the specific reason for escalation. If reviewers have to reconstruct the case from scratch, the workflow shifts work rather than reducing it.
Approval policy should be independent of model confidence. A high extraction score does not, by itself, authorize spending or remove controls such as dual approval or segregation of duties. For high-value or high-impact transactions, review may be mandatory even when all fields were read correctly. Conversely, a non-critical field may allow a later check if it can be corrected safely and does not put payment or the accounting entry at risk.
Measure the pilot before setting thresholds
The available sources do not establish a universal accuracy rate for extracting invoice amounts or a confidence score that works for every organization. There is also insufficient evidence to set a common monthly invoice volume, maximum latency, or error cost. Product documentation can describe recognized fields, supported formats, and technical limits; it does not prove that the product will perform the same way with a different corpus, configuration, or accounting process.
Establish a baseline and run the workflow in test mode or in parallel with human review before allowing automatic posting. Measure extraction errors by field, errors missed by controls, the proportion of documents routed for review, exception-resolution time, and correction costs. Weight errors by impact: misreading a descriptive note is not equivalent to changing the total, tax, currency, or supplier. Repeat the measurement across suppliers and document types, and retain corrections so later failures can be investigated.
Metrics for deciding whether to expand automation
Define the period, sample, and unit of measurement before comparing the pilot with the previous process. Do not use a single aggregate figure to conceal failures in critical fields.
| Metric | What it reveals | Decision it helps inform |
|---|---|---|
| Extraction error by field | Which values are read incorrectly and how often in the sample | Keep critical fields under review or adjust the extractor. |
| Errors missed by validation | Which failures reached a later stage | Add controls or stop automatic posting. |
| Exception rate and reasons | How much of the workflow requires judgment, missing data, or correction | Review the rules, data quality, or pilot scope. |
| Time and cost of correction | How much effort is being shifted to staff | Compare net benefit, not just reading time. |
| Incidents after posting | Which errors escaped and how significant they were | Reduce automation and reassess controls. |
| End-to-end latency | How long the workflow takes from receipt to final status | Determine whether performance meets the organization’s operational needs. |
Final matrix: automate, assist, or keep manual
The decision should consider two factors: how consistent the documents are and how serious an error would be. High volume can make automation attractive, but it does not make a payment error acceptable. If the structure is stable, rules are documented, and an error is reversible and low-impact, it may be reasonable to automate more steps after testing them. If formats vary but controls are clear, AI can assist with extraction while rules validate fields and people resolve exceptions.
If the document is unusual, the supplier is unidentified, the transaction has special tax implications, or the cost of an error has not been assessed, mandatory review is preferable. Manual processing may be the most sensible option for low-volume, exceptional, or not-yet-measured workflows. The goal is not to achieve the highest possible automation percentage; it is to reduce repetitive work without compromising accounting-data integrity, traceability, or approval accountability.
Operational decision matrix
Use these categories as a starting point and adjust the policy based on pilot results and finance approval.
| Structure and controls | Impact of an error | Recommended approach |
|---|---|---|
| Stable format, verifiable rules, and available internal data | Low and correctable | Automate extraction and validation; allow posting only after the tested controls pass. |
| Variable format, legible fields, and clear controls | Moderate | Use OCR or AI to assist extraction; review critical fields and route exceptions. |
| New supplier, changed bank details, or commercial discrepancy | High | Stop the transaction and require an independent human check. |
| Unmodeled tax or contractual rule, illegible document, or incomplete evidence | High or unknown | Keep human review mandatory until a validated rule and sufficient testing are in place. |
| Low volume or a process without a baseline | Unquantified | Organize and measure the process before buying or building more automation. |
Sources and evidence limitations
Microsoft Learn documentation provides primary information about the capabilities of a specific prebuilt model: its output fields, confidence scores, supported formats, and documented technical limits. It also describes custom options for cases where standard fields are not extracted adequately. It is not an independent comparative study and does not provide a universal accuracy rate for all invoices or configurations.
The available business guides help describe common stages—receipt, extraction, validation, approval, posting, and exception handling—but their savings or accuracy percentages are not presented here as general results because the supplied evidence does not independently validate them. Quantitative thresholds should therefore come from each organization’s pilot and financial policy, not from a promotional figure or an isolated model score.
Open questions
- The supplied evidence contains no independent results establishing model accuracy for invoice amounts across suppliers, languages, and scan quality levels.
- There is insufficient evidence to quantify what proportion of an organization’s corpus has a fixed structure or can be processed without human intervention.
- Acceptable error costs, minimum profitable volume, and maximum latency depend on each financial workflow and must be measured locally.
- The capabilities and limits described in Microsoft Learn apply to a specific product and should not be generalized to other models or configurations.
- The selection and validation of tax rules depend on jurisdiction and transaction details; this guide is not tax advice.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction