Generating One Token at a Time: The Cost This Technique Tries to Reduce
In conventional autoregressive generation, the model produces a token and then runs again to produce the next one, conditioned on the tokens that came before it. The sequence of steps limits how much computation can be parallelized within a single response: the next token depends on the state left by the previous one. This does not mean that every operation in a run is strictly sequential, but generation does impose a chain of dependencies between tokens.
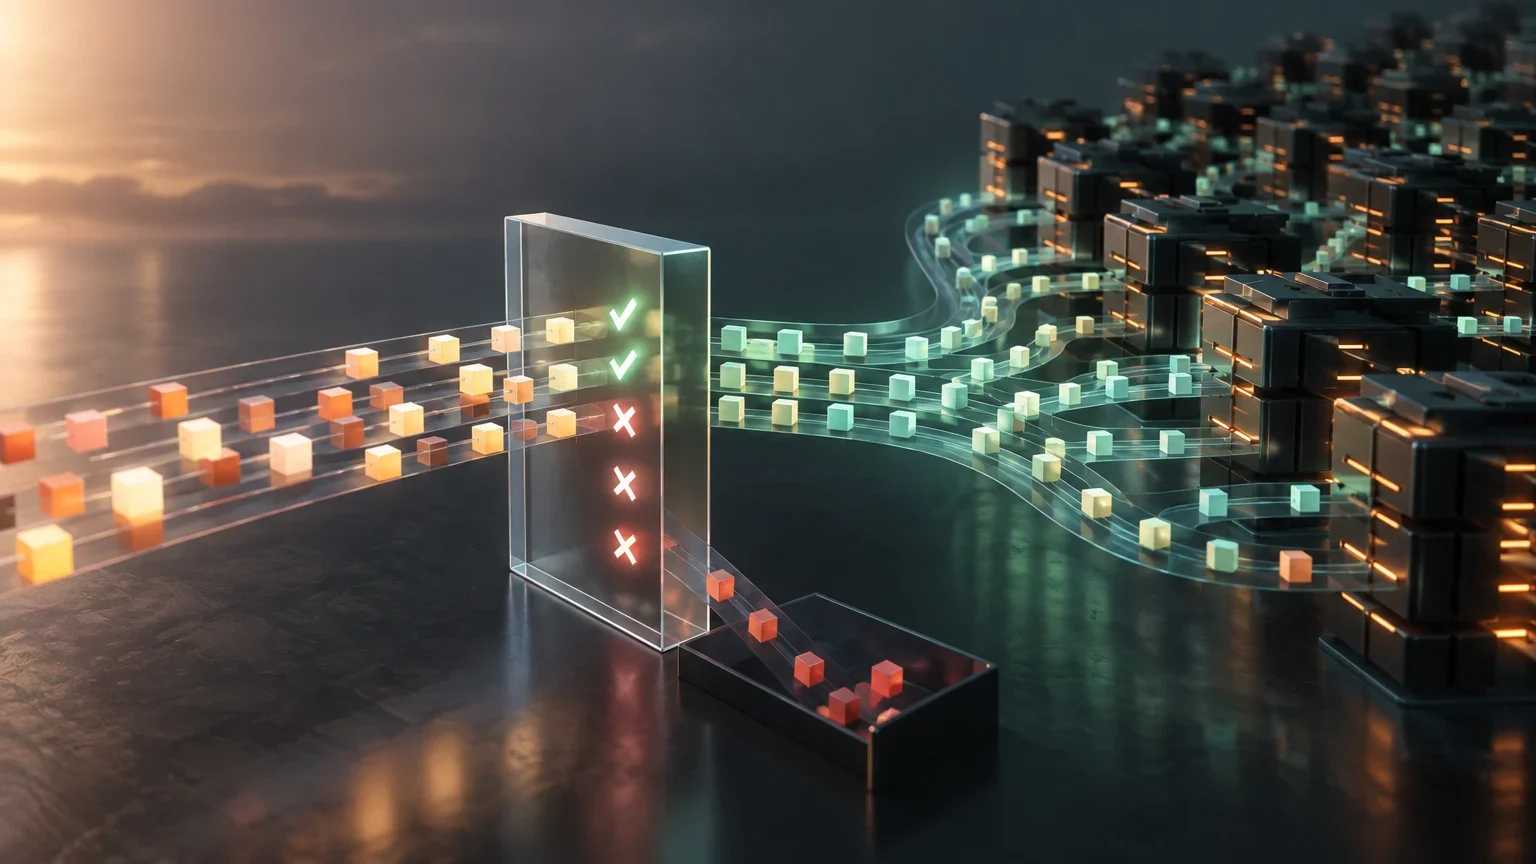
Speculative decoding aims to exploit an asymmetry: it may be cheaper to propose several tokens with an auxiliary model or mechanism and check them together with the target model than to generate each output token with another pass of the target model. The idea does not eliminate the target model’s work. It reorganizes that work so that, when the candidates are useful and verification is efficient, one execution can validate more than one token.
The performance question is therefore not just how many tokens the draft proposes or how many the target accepts. It also matters how much it costs to prepare the candidates, how much work is required to verify them, and how the runtime schedules those operations. A technique can reduce sequential steps while also adding computations that cancel out the savings.
How Draft-and-Verify Works
In the basic scheme, a draft proposes a sequence of candidates. The target model calculates the distributions for the positions in that sequence, and the verification procedure decides which candidates can be retained. If a candidate does not pass the check, the step is corrected and generation continues from the appropriate result. Verifying several candidates in one execution makes it possible to seek more parallelism than in token-by-token generation.
The draft proposal does not always have to match what the target would have generated. The key to the sampling procedure is that candidate acceptance and correction are designed so that, under the method’s conditions, the final result has the target model’s distribution. This is why the method should not be described as an approximate replacement for the target model: the target still determines the output distribution.
The number of accepted tokens is one part of the calculation, not a complete measure of speed. A high acceptance rate can come with costly verification; a lower rate can still be competitive if the draft is inexpensive and the runtime executes the additional work efficiently. The length of the speculative sequence is also a trade-off: proposing more candidates can increase both draft and verification work.
A Simplified Proposal-and-Verification Cycle
- 01The draft mechanism proposes one or more candidate tokens.
- 02The target model evaluates the candidates and calculates the distributions needed to verify them.
- 03The procedure accepts candidates compatible with speculative sampling and corrects the point of rejection when necessary.
- 04Generation continues from the validated sequence; any savings depend on the total cost of this cycle compared with the baseline method.
Preserving the Distribution Does Not Guarantee a Speedup
The work by Leviathan and co-authors presents speculative decoding as a way to accelerate inference without changing the distribution of the target model’s outputs. This guarantee depends on the sampling procedure and the method’s mathematical conditions; it does not claim that every generated answer will be identical to a particular answer from ordinary decoding. It concerns the distribution of outputs, not a requirement that each random trajectory match exactly.
Nor does the guarantee say that every configuration will be faster. It does not, by itself, determine the cost of the draft, the efficiency of operations on the accelerator, how the scheduler behaves with concurrent requests, or how much memory is available. Those factors belong to execution. In practice, sampling correctness and operational usefulness must be tested separately.
This distinction prevents a common but incorrect interpretation: that preserving the target distribution means the method “speeds up the model” universally. The more limited and accurate claim is that the method can preserve the distribution and deliver a speedup when the proposal, verification, and implementation work well under the conditions measured.
From EAGLE to EAGLE-3: The Proposal Changes, Not the Evaluation Criteria
EAGLE reframes speculative prediction by using information from internal features, rather than treating the draft solely as an independent source of tokens. The paper presents an approach focused on uncertainty in those features. This design difference matters because the proposal mechanism affects which candidates reach verification and how much it costs to generate them.
EAGLE-3 is a later variant whose paper focuses on scaling inference acceleration through an approach called “training-time test” in the paper’s title. Its reported numbers should not be presented as directly comparable with those from every EAGLE implementation or from the basic scheme. A valid comparison requires identifying the model, runtime, hardware, generation configuration, and workload for each experiment.
In particular, a result reported for SGLang should not simply be transferred to vLLM, and a result at a particular batch size should not be read as a prediction for a different traffic pattern. Differences in method matter, but infrastructure and evaluation protocol are also part of the result.
What to Keep Separate When Comparing Variants
| Aspect | Question to Ask | Why It Matters |
|---|---|---|
| Method | Is this basic speculative decoding, EAGLE, EAGLE-3, or another variant? | Proposal strategies and their costs are not necessarily the same. |
| Runtime | Was the measurement made with vLLM, SGLang, or another environment? | Scheduling and implementation can change the work actually performed. |
| Workload | Which batch sizes, concurrency levels, and request patterns were measured? | An improvement on one workload does not establish an improvement on another. |
| Metric | Does the report give latency, throughput, acceptance, or another measure? | Each metric answers a different question. |
What the 2026 Study Adds—and What It Cannot Establish
The preprint “Speculative Decoding: Performance or Illusion?” describes a systematic study of speculative decoding variants in vLLM across different models, workloads, and batch sizes. Findings highlighted in the paper’s description include that target-model verification can dominate a significant part of execution and that token acceptance varies by position, request, and dataset. These observations challenge the use of a single average acceptance rate as a sufficient indicator.
The useful takeaway is not that the technique never accelerates, but that the result depends on where the time is spent. If verifying candidates accounts for a large share of computation, the benefit of accepting several tokens can be reduced. And if acceptance varies across positions or requests, an aggregate average may hide cases where the extra draft work is not recovered.
The verified information available for this article does not allow us to list precisely every variant, model, workload, batch size, primary metric, or exact configuration in the preprint. Nor is it enough to reproduce the values from each experiment. For that reason, this article attributes no figures and does not claim that a particular variant wins in every scenario. A quantitative reading requires checking those details in the full text and the configuration for each experiment.
The preprint and the foundational paper answer different questions. The former studies the behavior of implementations and workloads in a runtime; the latter supports the possibility of preserving the distribution through the sampling procedure. Using the foundational paper’s mathematical result as proof of the performance of a vLLM configuration would conflate different levels of evidence.
Why Acceptance Alone Does Not Explain Speed
An acceptance rate or acceptance length describes how much of the proposal survives verification, but leaves out other costs: running the draft, preparing the necessary states, verifying candidates, and coordinating operations within the runtime. By itself, it also does not tell us how long a complete request takes or how many requests the system can serve per unit of time.
Concurrency makes this distinction more important. A shared service processes requests that compete for resources and can have different lengths. As batch size or concurrency increases, the useful work per execution can change, as can pressure on memory and scheduling. A latency improvement measured at a small batch size does not prove lower queueing latency in a concurrent service, nor does it establish higher service capacity.
It is useful to separate at least three outcomes. End-to-end latency answers how long a request waits before completion; per-token latency describes the generation pace under a measurement definition that must be made explicit; throughput measures the amount of work completed per unit of time. These are not interchangeable, and an optimization can favor one measure without improving the others by the same amount.
How to Evaluate a Claim of Acceleration
The comparison should start with a clear baseline: the autoregressive decoding that would use the same model in the same environment. If the runtime, hardware, or configuration also changes, it is not possible to confidently attribute the difference to the speculative technique. Generation conditions must also be specified, since they affect the distributions being verified and the resulting work pattern.
Next, the team should select metrics aligned with its objective. For an individual interaction, perceived latency may matter; for a service with variable demand, the latency distribution and capacity under concurrency may matter; for overall capacity, throughput may be the priority. Token acceptance and verification cost help explain the result, but do not replace service-level metrics.
The official vLLM documentation notes that results depend on the model, traffic, hardware, and configuration, and recommends measuring in the intended environment. That advice does not remove the need to publish the protocol: the protocol establishes the context to which a result applies and whether reproduction is reasonable.
A Practical Evaluation Protocol
- 01Fix the target model, baseline method, runtime, hardware, and generation configuration.
- 02Define a representative workload, including the batch size and concurrency levels to be evaluated.
- 03Measure latency and throughput appropriate to the service objective; also record acceptance and verification cost to help explain the result.
- 04Repeat measurements under the same conditions and document differences across batch sizes and traffic patterns.
- 05Report results for each variant and environment separately, without combining figures from different protocols into a single ranking.
Conclusion: Valid Evidence Is Evidence About the Complete System
Speculative decoding offers a strategy for reducing the sequential cost of token generation: propose several candidates and verify them with the target model. The sampling procedure can preserve the target’s output distribution, but that property does not, by itself, promise lower latency, higher throughput, or lower operating cost.
The foundational paper, variants such as EAGLE and EAGLE-3, and the 2026 study provide different kinds of evidence. Sampling theory explains a guarantee; variant papers describe different mechanisms and their evaluations; the vLLM study examines how methods, workloads, and batch sizes interact in a runtime. Their results should not be combined as if they came from one controlled test.
For a production decision, the central question is whether the specific combination of model, proposal mechanism, runtime, accelerator, and request pattern improves the metrics that matter to the service. The minimum evidence is a reproducible comparison against an equivalent baseline under the expected concurrency. Until that evidence is available, acceleration observed in a limited test is a hypothesis to validate, not a guarantee of capacity.
A Decision Guide for Inference Teams
| If the question is… | The evidence needed |
|---|---|
| Is the target distribution preserved? | The sampling procedure and the conditions under which it is correct. |
| Does the latency of an individual request decrease? | A latency measurement using an equivalent baseline and configuration. |
| Does service capacity improve? | Throughput measured under the expected concurrency and traffic pattern. |
| Can the result be generalized? | Tests on the models, runtime, hardware, and workloads where the technique is intended to be used. |
Open questions
- The verified information available for this article does not break down every variant, model, workload, batch size, or primary metric evaluated in the 2026 preprint.
- No experimental figures or sufficient details to independently reconstruct each comparison in the 2026 study are provided here.
- The magnitude of acceleration and how it changes with concurrency depend on the specific configuration; the summarized sources do not support inferring a universal quantitative trend.
- The EAGLE and EAGLE-3 evaluations were conducted under conditions that should not be assumed equivalent to each other or to those in the vLLM study.
Keep exploring
Sources consulted
Corrections and transparency
If you spot incorrect or outdated information, send us a correction with the page and source we should review.
Submit a correction