One-sentence definition
Degree of lack of certainty about a prediction, a response, available evidence, or the validity of a measurement.
Definition and concepts that should not be confused
Uncertainty is the degree of lack of certainty about a prediction, a response, the available evidence, or the validity of a measurement. In the context of statistics and machine learning, it is not a single error point, but a measure of the potential variability of results. As statistician George Box noted, "All models are wrong, but some are useful"; uncertainty allows quantifying how much a model deviates from reality and, therefore, determining its practical utility.
It is crucial to distinguish uncertainty from precision and accuracy. Accuracy refers to the approximation of a prediction to a known value, while uncertainty describes how much predictions and target values can vary. A system can be precise (repeatable) but inaccurate, or vice versa. Uncertainty quantification (UQ) transforms the vague statement that "a model could be wrong" into specific and quantifiable information about the degree and nature of the possible error, which is vital in fields where reliability is paramount, such as medicine or engineering.
Key differences between related concepts
Comparative table to distinguish concepts that are often confused in model evaluation.
| Concept | Definition | Can it be reduced with more data? |
|---|---|---|
| Aleatoric uncertainty | Inherent noise in the data generation process (stochastic). | No, it is irreducible. |
| Epistemic uncertainty | Lack of knowledge about the optimal model or insufficient data. | Yes, theoretically reducible. |
| Accuracy | Closeness of the prediction to the true value. | Depends on the quality of the model and data. |
| Precision | Consistency of predictions among themselves (repeatability). | Yes, with better calibration. |
Step-by-step functioning: from prediction to distribution
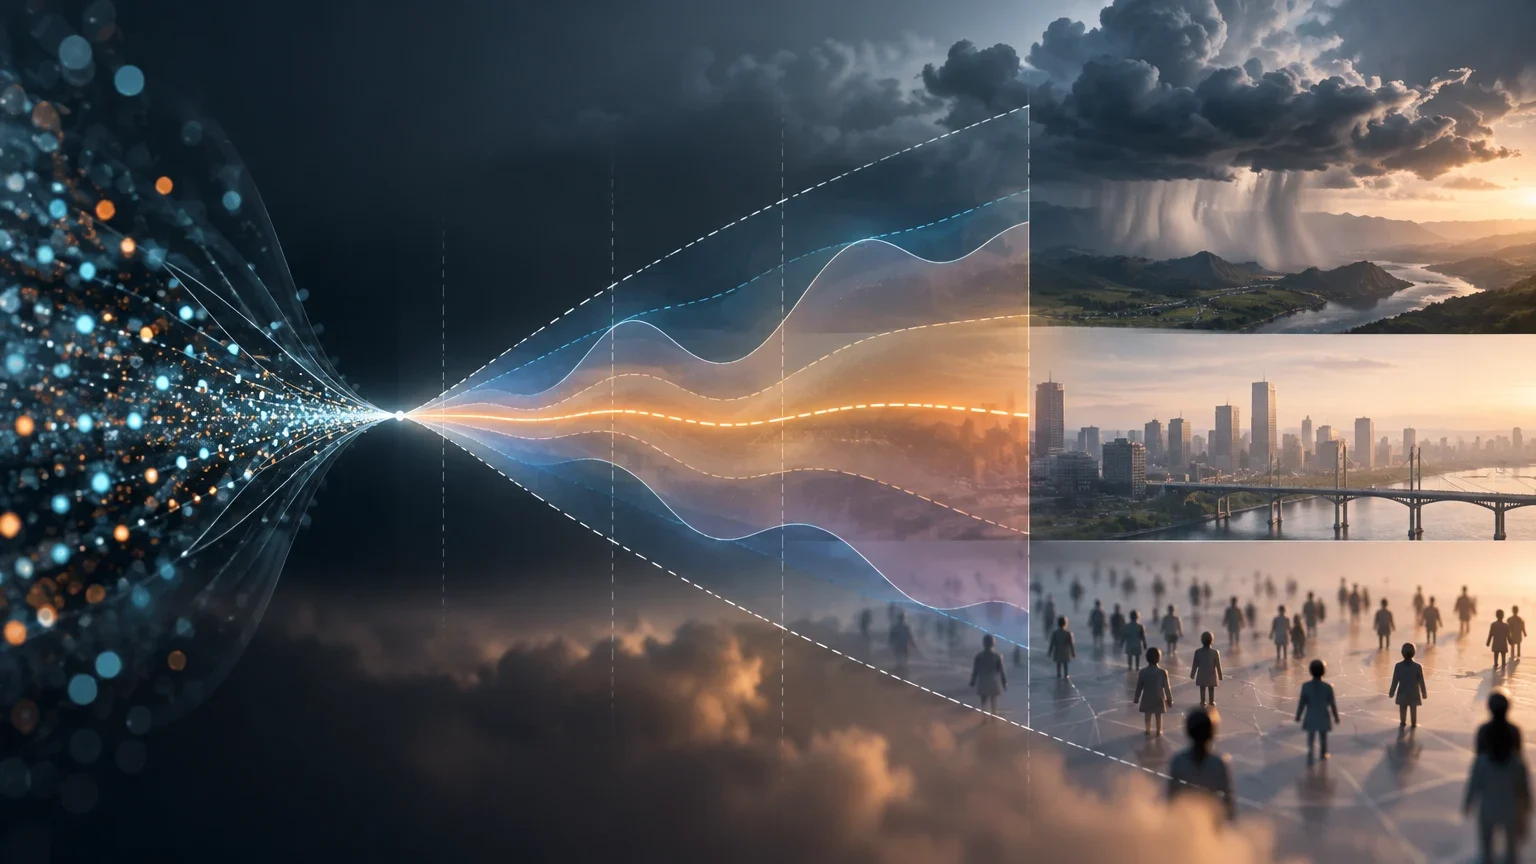
The functioning of uncertainty quantification starts by treating model outputs not as fixed values, but as random variables. Instead of generating a single point estimate, the model produces a probability distribution. The width of this distribution is the direct measure of uncertainty: the wider the distribution, the greater the uncertainty associated with the result.
There are two main sources of this variability. The first is aleatoric uncertainty, which arises from stochastic processes or random characteristics in the system. For example, the natural variability in the response of a material to a force. The second is epistemic uncertainty, which comes from incomplete knowledge, such as the lack of training data in certain regions of the feature space. UQ methods seek to separate or estimate these components to determine the confidence that should be placed in a specific prediction.
Basic flow of uncertainty quantification
General process for estimating uncertainty in a predictive model.
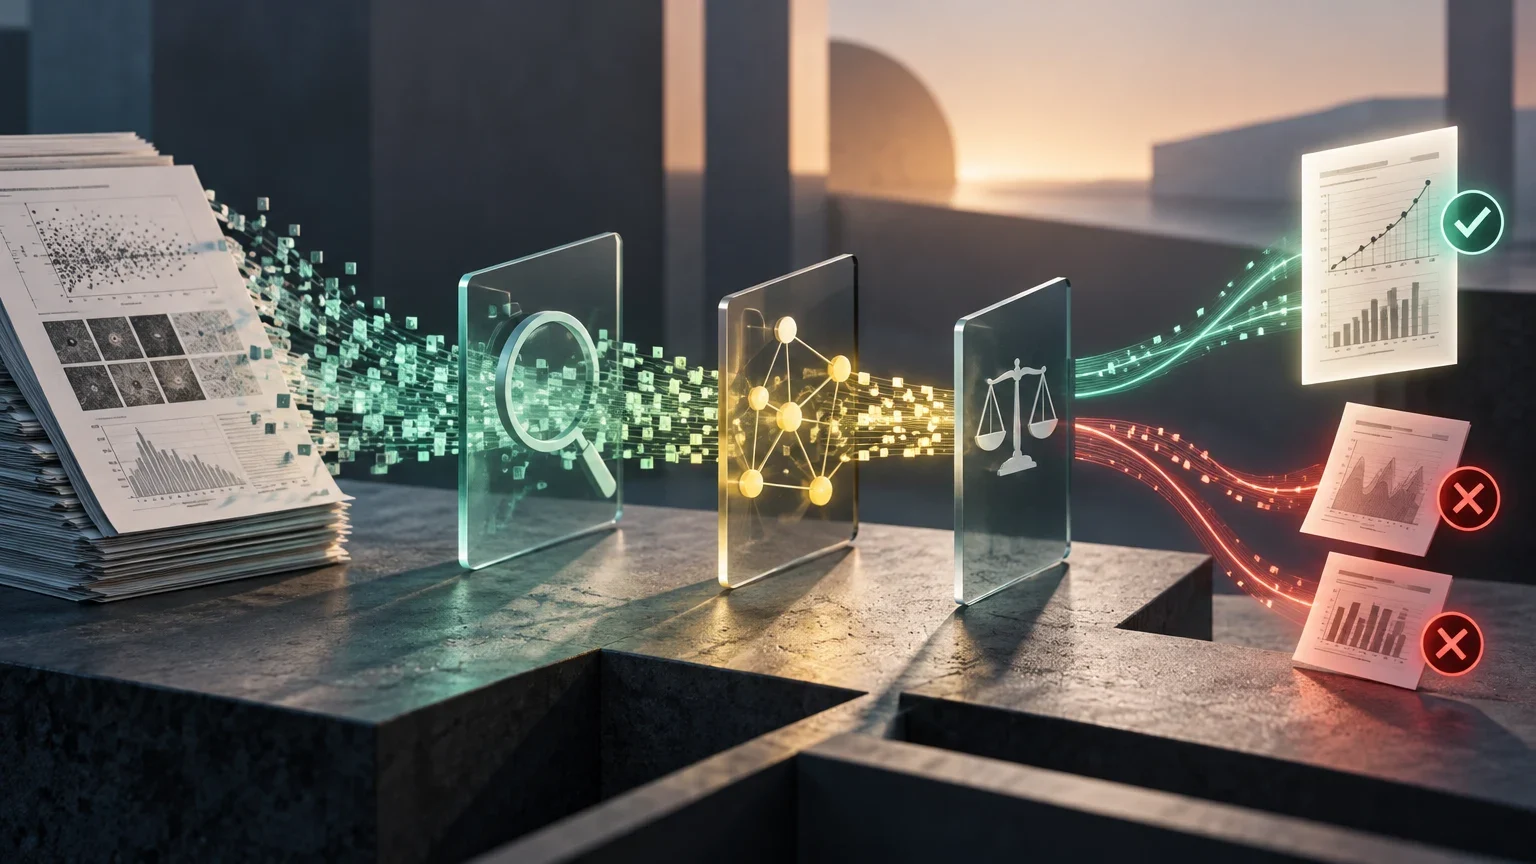
- 01Define the base model and training data.
- 02Identify sources of variability (aleatoric vs. epistemic).
- 03Apply a quantification method (e.g., sampling, Bayesian, or ensemble).
- 04Generate a distribution of predictions instead of a single value.
- 05Calculate dispersion metrics (variance, confidence intervals) to quantify uncertainty.
- 06Evaluate model calibration by comparing predicted confidence with the observed frequency of correct outcomes.
Three developed examples in relevant fields
In meteorology, a model may predict a 70% probability of rain. Uncertainty quantification helps determine whether that 70% is based on solid data or if the uncertainty is so high that the actual probability could range between 50% and 90%. This allows users to make more informed decisions, such as whether to bring an umbrella or postpone outdoor events, based on the range of possible outcomes rather than a single figure.
In engineering, consider a model that predicts how many times a hinge can be opened and closed before it fails. Aleatoric uncertainty captures the inherent material variability, while epistemic uncertainty reflects the lack of testing under extreme conditions. A computer vision system that classifies only red or green apples has much less inherent uncertainty than one that classifies all fruits in the world, due to the greater complexity and variability of the data in the latter case.
In social sciences and economics, uncertainty affects the validity of quantitative predictions. Machine learning models applied to social data must consider epistemic uncertainty derived from the complexity of human interactions and the limitation of historical data. Distinguishing between random noise in the data and the lack of knowledge about causal mechanisms is essential to avoid overfitting and to correctly interpret the limitations of predictive models in dynamic contexts.
Quantification methods: sampling, Bayesian, and ensembles
Sampling-based methods, such as Monte Carlo simulation, are widely used because they can handle any model complexity. They run thousands of simulations with randomly varied inputs to build a statistical picture of likely outcomes. An efficient variant is Latin hypercube sampling, which covers the input space well with fewer runs. Monte Carlo Dropout is another technique that keeps the dropout layer active during inference, generating multiple forward passes to obtain an output distribution without needing to retrain the model.
Bayesian methods assign probability distributions to model parameters instead of fixed values. They use Bayes' theorem to combine prior beliefs with observed data. Bayesian neural networks (BNNs) treat network weights as probability distributions, allowing for rigorous uncertainty quantification. Ensemble methods are based on the idea that if several independently trained models do not agree, that disagreement indicates uncertainty. The variance of the ensemble's predictions is used as a measure of uncertainty, although this approach has a high computational cost.
Comparison of uncertainty quantification methods
Summary of advantages and limitations of the main methods.
| Method | Main advantage | Main limitation |
|---|---|---|
| Monte Carlo | Flexible, handles any complexity. | Computationally expensive (thousands of runs). |
| Bayesian (BNN) | Rigorous, separates aleatoric and epistemic. | Complex to implement, requires MCMC or variational inference. |
| Ensembles | Intuitive, measures disagreement between models. | Very expensive (training N full models). |
| Gaussian Processes (GPR) | Efficient, expresses uncertainty inherently. | Limited scalability with large datasets. |
Common errors and limits of quantification
A frequent error is assuming that uncertainty is always reducible with more data. Aleatoric uncertainty is irreducible; it comes from the stochastic nature of the phenomenon. Trying to reduce it by adding more data only increases the cost without improving fundamental accuracy. Another error is confusing calibration with accuracy. A model can be well-calibrated (its confidence reflects the actual probability of being correct) but be inaccurate in its point predictions.
The limits of uncertainty quantification include computational cost, especially in high-dimensional deep learning models. Furthermore, the choice of quantification method depends on the characteristics of the model and the scenario. There is no universal method; most real-world applications combine multiple approaches. It is important to remember that quantified uncertainty is an estimate, not an absolute truth, and must be interpreted in the context of the model's assumptions.
Frequently asked questions and primary sources
What is the main difference between aleatoric and epistemic uncertainty? Aleatoric uncertainty is the inherent noise in the data, irreducible. Epistemic uncertainty is the lack of model knowledge, reducible with more data or better modeling. What metrics are used to evaluate uncertainty? Proper scoring rules (such as Negative Log-Likelihood, NLL) and calibration metrics (such as Expected Calibration Error, ECE) are used. NLL measures the fit of the predicted distribution to observed outcomes, while ECE measures the difference between predicted confidence and the observed frequency of correct outcomes.
Is conformal prediction useful for black-box models? Yes, conformal prediction is a model-agnostic technique that provides valid coverage guarantees with minimal assumptions. It is especially useful when working with pre-trained black-box models, as it allows establishing prediction intervals without needing to know the internal structure of the model. Primary sources include the work by Hüllermeier and Waegeman on the conceptual distinction and the paper by Chavare and Mourelatos on quantification methods in engineering.