One-sentence definition
Division of documents into retrievable units that retain enough context to answer questions.
Definition and Concepts to Distinguish
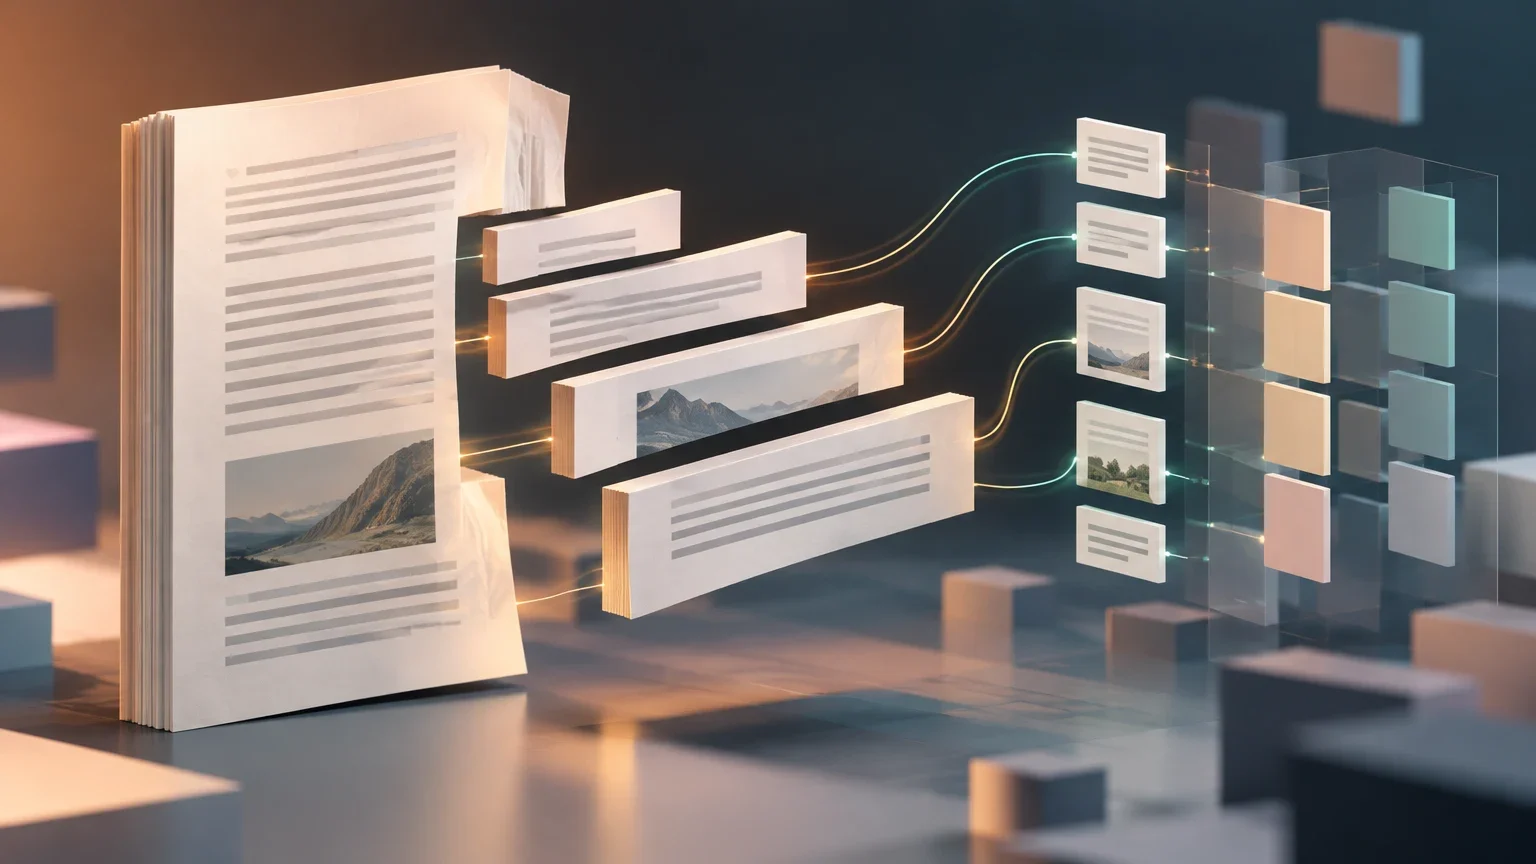
Document chunking is the process of dividing a document or information source into smaller units, known as chunks. The goal is to facilitate the storage, processing, and retrieval of information in artificial intelligence systems, particularly in Retrieval-Augmented Generation (RAG) architectures. In these systems, instead of processing entire documents, specific fragments are retrieved to provide the necessary context for generating a coherent response.
It is fundamental to distinguish chunking from other related processes. Chunking creates the content units; indexing organizes that information so it can be located; and passage retrieval determines which of those units are pertinent to a specific query. Confusing these stages can lead to optimizing fragment size without improving the quality of the final answer, as retrieval also depends on the search algorithm, the quality of embeddings, and the formulation of the query.
Chunking is one stage in a larger retrieval pipeline, so its output should be understood as a set of candidate information units rather than as answers in themselves. Indexing makes those units findable, while passage retrieval selects units in response to a particular query. RAG then uses retrieved information when generating a response. Keeping these roles distinct helps explain why changing chunk boundaries alone cannot guarantee a better result: the search algorithm, embedding quality, and query formulation also affect which passages are found and how useful they are.
A chunk therefore needs to be small enough to be located and used as a relevant piece of content, but it also needs to retain enough surrounding information to be interpreted correctly. These requirements can pull in different directions. Smaller units may make retrieval more precise, while broader units may preserve context that would otherwise be separated from the statement it qualifies. The appropriate balance depends on the document and the query, rather than on a universal definition of the ideal chunk.
Differences Between Key Concepts
Table distinguishing the function of each process in the retrieval pipeline.
| Concept | Primary Function |
|---|---|
| Chunking | Divides content into smaller units. |
| Indexing | Organizes information for location. |
| Passage Retrieval | Finds fragments pertinent to a query. |
| RAG | Uses retrieved information to generate responses. |
Step-by-Step Functionality
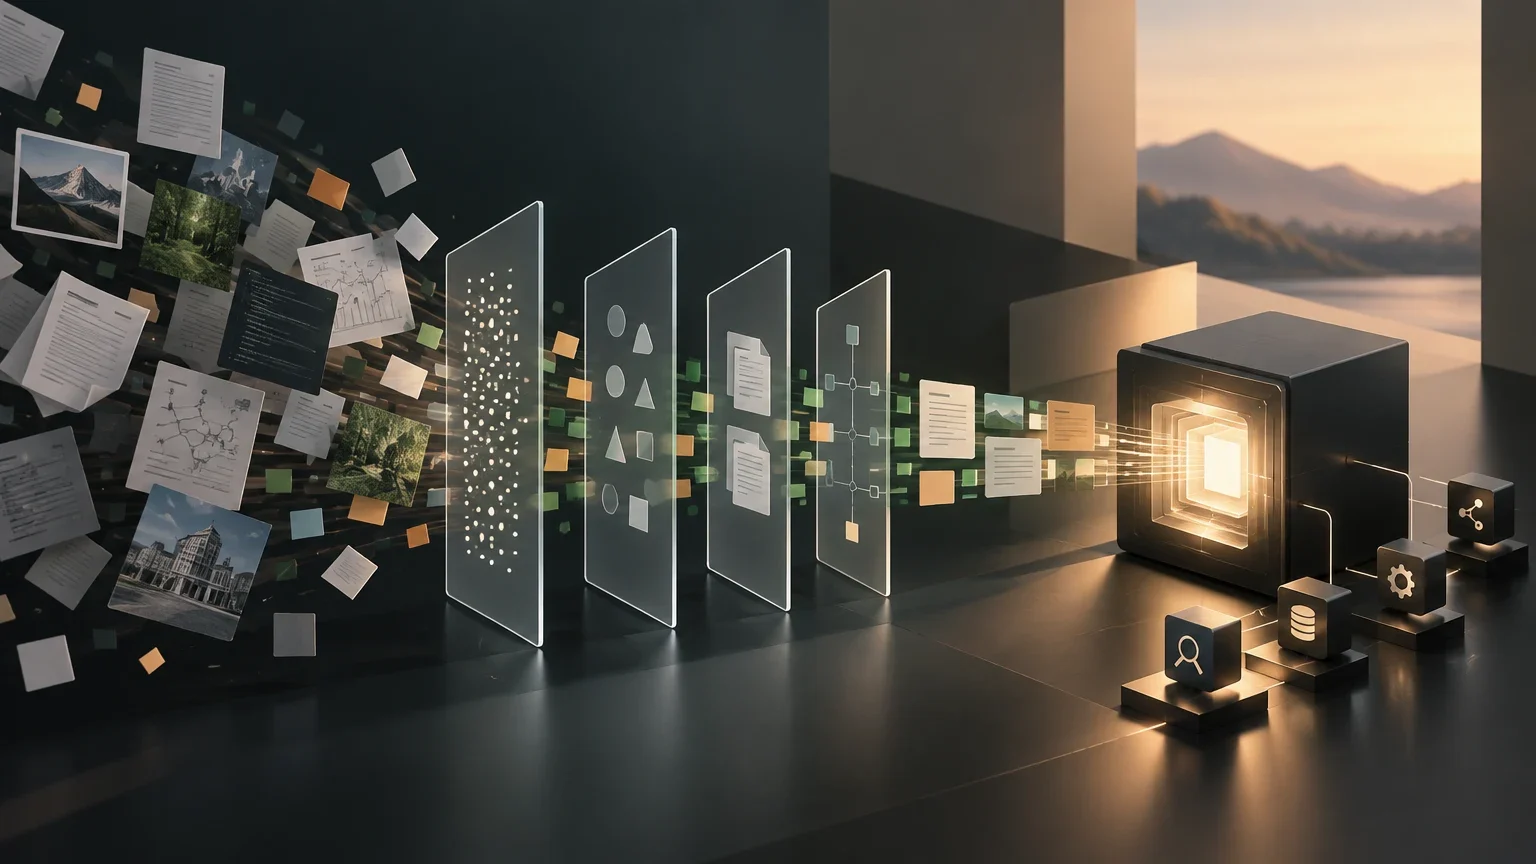
The chunking process typically follows a logical sequence that begins with content preparation. Before splitting the text, the system extracts the original structure, including titles, paragraphs, tables, and metadata. The quality of this extraction is critical: if the document hierarchy is lost, the resulting fragments may lack the context necessary for correct interpretation.
Next, a chunking strategy is selected, determining how the text will be split. This decision directly influences the length of the fragments and which information is kept together. Once the rules are defined, the fragments are generated, assigned identifiers, and tagged with metadata such as the source URL or position within the document. Finally, these fragments are indexed, often through the creation of vector embeddings, making them ready for retrieval when a user query arrives.
Preserving structure during preparation matters because the meaning of a passage can depend on more than its words in isolation. A heading may identify the subject that a paragraph elaborates, and a table may encode relationships that are not apparent if its contents are extracted as an undifferentiated sequence. If those relationships or hierarchy are lost before chunking begins, later splitting and retrieval cannot reliably restore the missing context. Preparation is therefore not merely a text-extraction step; it establishes the structure on which subsequent choices depend.
The sequence also separates the creation of chunks from their later use. Strategy rules determine how content is grouped, and generation turns those rules into units with identifiers and metadata. Indexing then makes the units available to search, while retrieval occurs in response to a query. Metadata such as a source URL or document position can help preserve information about where a chunk came from, but it does not by itself establish that the chunk is relevant. Relevance still depends on the retrieval stage and the query presented to the system.
Chunking Pipeline Stages
Sequence of operations to transform a document into retrievable units.
- 01Preparation: Extraction of text and structure (titles, tables, metadata).
- 02Strategy: Selection of the splitting method (fixed, semantic, hierarchical).
- 03Generation: Creation of chunks with identifiers and metadata.
- 04Indexing: Storage in vector databases or search indexes.
- 05Retrieval: Selection of relevant chunks upon a query.
Main Chunking Strategies
There is no single correct way to chunk a document. The choice of strategy depends on the type of content, the complexity of expected queries, and available computational resources. The most common strategies include fixed-length chunking, which is simple but can cut ideas in half; structure-based chunking, which respects headers and paragraphs; and semantic chunking, which detects topic changes to keep related ideas together.
Semantic and hierarchical chunking are particularly useful for complex documents. Semantic chunking uses language models or embeddings to identify where meaning changes, avoiding arbitrary divisions. Hierarchical chunking, on the other hand, organizes content into levels (document, section, paragraph), allowing the retrieval of a small unit for search precision while using its parent section to provide broad context to the generative model.
The strategies differ chiefly in what they use to decide where one unit ends and another begins. Fixed-length chunking applies a simple size rule, which makes it straightforward to control but does not ensure that a sentence or complete idea will remain intact. Structure-based chunking instead uses elements such as headers and paragraphs as boundaries, so the result depends on whether the document structure has been extracted correctly. Semantic chunking seeks changes in meaning rather than relying only on a fixed boundary, while hierarchical chunking retains relationships between levels of the document.
These approaches should not be treated as a ranking from universally worse to universally better. A method that preserves a document's headings may be suitable when those headings express meaningful divisions, but it relies on the quality of that structure. Semantic divisions can keep related ideas together, yet identifying changes in meaning may require language models or embeddings and can involve greater computational cost and complexity. Hierarchical organization can support both focused retrieval and broader context, but it also adds complexity to the retrieval pipeline. The choice remains dependent on the content, expected queries, and available computational resources.
A useful way to reason about the choice is to ask what information a boundary might separate. If a fixed boundary could split an idea, sentence, or necessary explanation, another strategy may better preserve the relationship. If the document has reliable headings and paragraphs, those divisions can provide meaningful units; if topic changes do not align with visible structure, semantic chunking may be relevant. For complex documents, a hierarchy can allow a small unit to be retrieved while its parent section supplies broader context. These are considerations for selecting and testing a strategy, not evidence that one method always produces better responses.
Comparison of Chunking Strategies
Summary of advantages and limitations of the most used methods.
| Strategy | Main Advantage | Main Limitation |
|---|---|---|
| Fixed Length | Simple to implement and control. | Can cut sentences or complete ideas. |
| Structure-Based | Preserves thematic context of sections. | Depends on the quality of the document structure. |
| Semantic | Keeps related ideas together by meaning. | Higher computational cost and complexity. |
| Hierarchical | Balances search precision and broad context. | Adds complexity to the retrieval pipeline. |
Three Developed Examples in Relevant Fields
In the field of technical documentation, header-based chunking is often the most effective. A software manual, for example, is divided by sections and subsections. This allows a fragment about 'Network Configuration' to retain the context of the 'Networks' section, preventing the model from interpreting instructions without knowing which system they apply to. If fixed chunking were used, a critical instruction might be separated from its preamble, generating an incomplete response.
For legal contracts, chunking must respect the clause structure. A contract is divided by articles and legal paragraphs. Here, precision is vital: a liability exclusion clause must be retrieved along with its legal context. Semantic chunking can be useful if the contract jumps between topics, but hierarchical structure is usually more reliable for maintaining the integrity of legal obligations. In this case, overlap is less relevant than the integrity of the legal unit.
In customer service systems with FAQs, chunking may be unnecessary if the entries are already short and self-contained. Each question and its answer form a natural chunk. Forcing an additional division only adds noise. However, if the answers are extensive, a recursive chunking that respects paragraphs allows retrieving the specific part of the answer that addresses the user's doubt, without loading the model with irrelevant information from other questions.
The examples show why chunking decisions are tied to the internal organization of the material. In technical documentation, a heading-based unit can keep an instruction connected to the section that identifies the system it concerns. In a legal contract, the clause and its surrounding legal context matter to the interpretation of an obligation. In FAQs, a question and its answer may already form a complete unit, making further division unnecessary when entries are short. The same operation—splitting text—therefore has different consequences depending on whether the source is organized around sections, clauses, or self-contained entries.
These examples also distinguish between preserving a complete unit and adding overlap. For a legal clause, keeping the clause intact is described as more relevant than overlap. In a long FAQ answer, by contrast, recursive division that respects paragraphs can make a specific part retrievable without including unrelated answers. Neither example establishes a universal rule for every document: they illustrate how the structure and completeness of the information affect the choice. A chunking decision should retain the relationships needed to interpret the retrieved passage, rather than split content merely to make every unit the same size.
Evaluating Results and Common Errors
Evaluating a chunking strategy should not be based on intuition, but on retrieval and response quality metrics. It is necessary to measure whether relevant fragments appear among the top results (Recall@k), whether they contain all the information necessary to answer (evidence coverage), and whether the system generates responses faithful to the sources. Latency, storage cost, and ease of maintenance when documents are updated must also be considered.
A frequent error is assuming that there is a universal optimal fragment size. In reality, the appropriate size depends on the type of document and the queries. Another common mistake is ignoring overlap or using it excessively. Moderate overlap can help preserve information that crosses fragment boundaries, but excess generates redundancy and can confuse the model. Finally, treating tables and structured data as plain text can alter the relationships between values and labels, requiring specific preprocessing strategies.
Evaluation should connect the mechanics of chunking to what the retrieval and generation stages actually need. Recall@k asks whether relevant fragments appear among the top results, while evidence coverage asks whether those fragments include the information needed to answer. Response faithfulness addresses whether the generated answer remains faithful to its sources. Together, these checks help distinguish a boundary problem from a retrieval or answer-quality problem: a relevant passage may be absent from the results, may appear without enough context, or may be retrieved but not reflected faithfully in the response.
The evaluation should also account for operational considerations named in the original description: latency, storage cost, and the ease of maintaining the system as documents are updated. A choice that performs acceptably on retrieval and response measures still has to be considered alongside these costs. This does not make one fixed chunk size or strategy optimal in every setting; it means the strategy should be assessed against both information quality and the practical requirements of the pipeline.
Overlap illustrates why design choices need measurement rather than a preset rule. Repeating some content across neighboring chunks can preserve information that crosses a boundary, but it also repeats material and may introduce redundancy that confuses the model. The useful amount depends on the content, and there is no universal percentage. Likewise, tables and other structured data require care because treating them as continuous prose can obscure which values belong with which labels. Preprocessing and chunk boundaries should preserve those relationships so that retrieved fragments remain interpretable.