One-sentence definition
Sampling parameter that modifies the probability distribution used to select the next tokens.
Technical Definition: The Sampling Parameter
In the context of large language models (LLMs), temperature is an inference parameter that adjusts the probability distribution of generated tokens. It is not a measure of the model's intrinsic 'quality' nor a physical variable, but a mathematical control that determines how random or deterministic the selection of the next token will be.
Models assign a numerical value, known as a logit, to each possible token in the vocabulary. These logits are normalized using a softmax function to create a probability distribution where the sum of all probabilities is one. Temperature intervenes in this process by dividing the logits by a value T before applying the softmax function, thereby modifying the shape of the final distribution.
The distinction between temperature as a mathematical control and the model's intrinsic capabilities is critical for accurate system design. It is essential to recognize that this parameter does not alter the underlying weights of the neural network or the knowledge encoded during the pre-training phase. Instead, it operates exclusively at the inference stage, acting as a post-processing filter on the raw scores generated by the model. This separation ensures that the model's core understanding remains static, while the output behavior is dynamically adjusted to fit specific operational requirements without requiring retraining or fine-tuning of the architecture itself.
Understanding the role of logits as pre-activation scores provides further clarity on the mechanism. These values represent the model's confidence in each token before normalization. By manipulating these scores through division by T, the system effectively rescales the confidence levels. This rescaling is a linear operation on the log-probabilities, which translates into a non-linear transformation of the final probabilities after the exponential function is applied. This mathematical property explains why small changes in temperature can have disproportionately large effects on the tail of the distribution, particularly when the initial logits are close in value.
Mechanism of Action on the Distribution
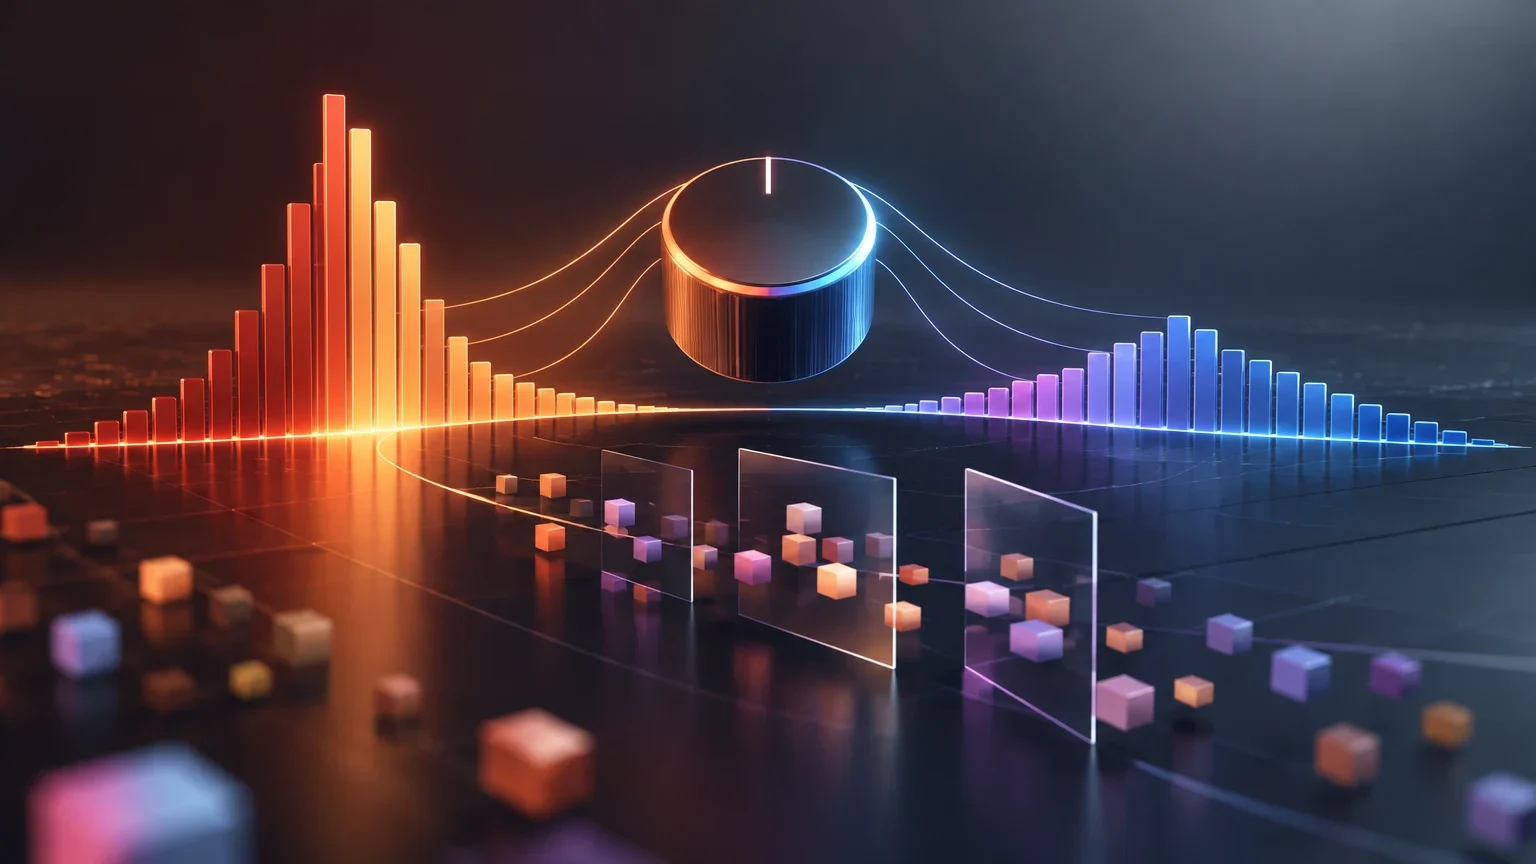
Mathematically, the softmax function with temperature is expressed as $P(x_i) = \frac{e^{z_i/T}}{\sum_{j} e^{z_j/T}}$, where $z_i$ is the logit of token $i$ and $T$ is the temperature. As $T$ approaches zero, the distribution becomes increasingly peaked, favoring almost exclusively the token with the highest logit (greedy decoding).
As $T$ increases, the distribution flattens. This increases the entropy of the system, allowing tokens with initially low probabilities to have a significant chance of being selected. This mechanism is fundamental to understanding why high temperature introduces variability and low temperature promotes consistency.
The behavior of the distribution as T approaches zero is asymptotic rather than instantaneous. In practical implementations, a temperature of exactly zero is often treated as a special case that bypasses the probabilistic sampling entirely, forcing the selection of the token with the highest logit. This greedy approach eliminates randomness but can lead to degenerate loops where the model repeatedly generates the same sequence of tokens because it is always choosing the locally optimal next step without considering global context or diversity. This phenomenon highlights the trade-off between local coherence and global variety in deterministic decoding strategies.
Conversely, when T exceeds one, the flattening of the distribution introduces a significant risk of selecting tokens that are semantically unrelated to the context. As the entropy increases, the probability mass is spread across a wider range of tokens, including those with very low initial confidence. This can result in outputs that are syntactically valid but semantically incoherent, as the model may select words that fit the grammatical structure but do not align with the logical flow of the conversation or task. This risk is particularly pronounced in tasks requiring strict factual accuracy or logical consistency.
Effect of Temperature on the Distribution
Qualitative comparison of probability distribution behavior according to the value of T.
| Value of T | Distribution Behavior | Expected Result |
|---|---|---|
| T ≈ 0 | Highly concentrated distribution (sharp peak) | Deterministic, repetitive output, high local coherence |
| T = 1 | Original model distribution | Standard balance between probability and variability |
| T > 1 | Flattened distribution (high entropy) | Diverse, creative output, higher risk of incoherence |
Applied Examples in Different Domains
The choice of temperature depends directly on the task. In creative generation, such as scriptwriting or brainstorming, high values (0.7 to 1.2) are typically employed to encourage novelty and avoid repetitive patterns from training data.
In structured data extraction or code generation, precision is paramount. Here, very low temperatures (0.0 to 0.2) are used to ensure the model always selects the most probable option, minimizing syntactic or formatting errors. In benchmark evaluation, a temperature of zero or near-zero is recommended to ensure comparability of results across different models or versions.
The application of temperature in creative generation requires a nuanced understanding of the balance between novelty and coherence. While high values encourage the exploration of less frequent tokens, they do not guarantee high-quality creative output. The model may produce unusual combinations that are grammatically correct but contextually nonsensical. Therefore, the choice of temperature in creative tasks is often iterative, requiring human evaluation to determine the optimal level of variability that enhances the narrative without compromising the logical integrity of the text. This iterative process is crucial for achieving the desired tone and style in applications such as scriptwriting or brainstorming.
In the context of structured data extraction, the use of low temperatures is not merely a preference but a necessity for maintaining data integrity. The downstream systems that consume the extracted data often rely on strict schema validation. Any deviation from the expected format, such as inconsistent key names or non-standard date representations, can cause parsing errors and data loss. By minimizing the probability of selecting alternative tokens, low temperatures ensure that the output adheres strictly to the predefined structure, thereby reducing the need for post-processing corrections and improving the reliability of the data pipeline.
Common Confusions and Related Concepts
It is a common error to confuse temperature with the 'creativity' or 'intelligence' of the model. Empirical studies, such as Peeperkorn et al. (2024), indicate that the correlation between temperature and novelty is weak, while the relationship with incoherence is moderate. Increasing temperature does not make the model more 'intelligent,' but rather expands the range of tokens considered.
Temperature interacts with other sampling parameters such as top-k and top-p (nucleus sampling). Top-k limits selection to the k most probable tokens, while top-p selects the smallest set of tokens whose cumulative probability exceeds a threshold (e.g., 0.9). These parameters act as filters that restrict the search space before or after applying the temperature transformation, allowing finer control over quality and diversity.
The interaction between temperature and top-p sampling is particularly important in scenarios where the vocabulary size is large. Top-p sampling dynamically adjusts the set of candidate tokens based on the cumulative probability, which means that the effective number of tokens considered can vary from one generation step to the next. When combined with temperature, this dynamic filtering can lead to unpredictable changes in the diversity of the output. For instance, a high temperature might flatten the distribution, causing top-p to include a larger set of tokens, thereby increasing the variability of the output. This interplay requires careful tuning to avoid unintended fluctuations in output quality.
The misconception that temperature directly controls creativity is further complicated by the fact that creativity is a subjective and multifaceted concept. Empirical studies have shown that the relationship between temperature and perceived creativity is not linear and can vary depending on the specific task and the evaluator's criteria. In some cases, moderate temperatures may produce outputs that are perceived as more creative because they strike a balance between novelty and coherence. In other cases, very high temperatures may produce outputs that are perceived as chaotic or incoherent, regardless of the novelty introduced. This highlights the need for task-specific evaluation metrics rather than relying solely on the temperature parameter.
Limits for Reproducibility and Evaluation
Although a temperature of zero theoretically produces deterministic output (greedy decoding), in practice non-determinism may persist due to hardware parallelization (GPUs) or model quantization. This means that even with T=0, two identical executions may produce slightly different results in some inference systems.
For operations teams and data scientists, this implies that temperature is a critical variable in inference configuration. Changing this parameter alters the evaluation metric. Results from a model with T=0.5 should not be compared against another with T=0.1 without normalizing this factor, as the difference in output is not necessarily due to model capability, but to the sampling configuration.
The persistence of non-determinism even at T=0 is a critical consideration for systems that require strict reproducibility. This non-determinism arises from the parallel nature of modern hardware, where the order of operations in floating-point arithmetic can vary slightly depending on the hardware configuration and the specific implementation of the inference engine. These minor variations in the calculation of logits can lead to different tokens being selected, even when the temperature is set to zero. This issue is particularly relevant in distributed systems where the same model may be run on different hardware configurations, leading to inconsistent results across nodes.
For operations teams, the implication is that temperature must be treated as a first-class variable in the configuration management of inference pipelines. Changes to this parameter should be versioned and documented alongside model updates and hardware changes. This ensures that any observed differences in output can be attributed to specific configuration changes rather than to uncontrolled variables. Furthermore, the use of fixed seeds for sampling, where supported, can help mitigate the effects of hardware non-determinism, providing a higher degree of reproducibility for evaluation and debugging purposes.
Process to Ensure Reproducibility
Recommended steps to minimize unwanted variability in production pipelines.
- 01Set temperature to 0.0 for deterministic tasks.
- 02Verify if the inference provider supports setting a seed for sampling.
- 03Document the exact model version and hardware configuration (GPU/CPU) used.
- 04Perform A/B tests with the same seed to validate output consistency.