One-sentence definition
Use of a few examples within the request to show the model the task, criterion, or expected format.
Definition: Few-shot prompting as a context engineering technique
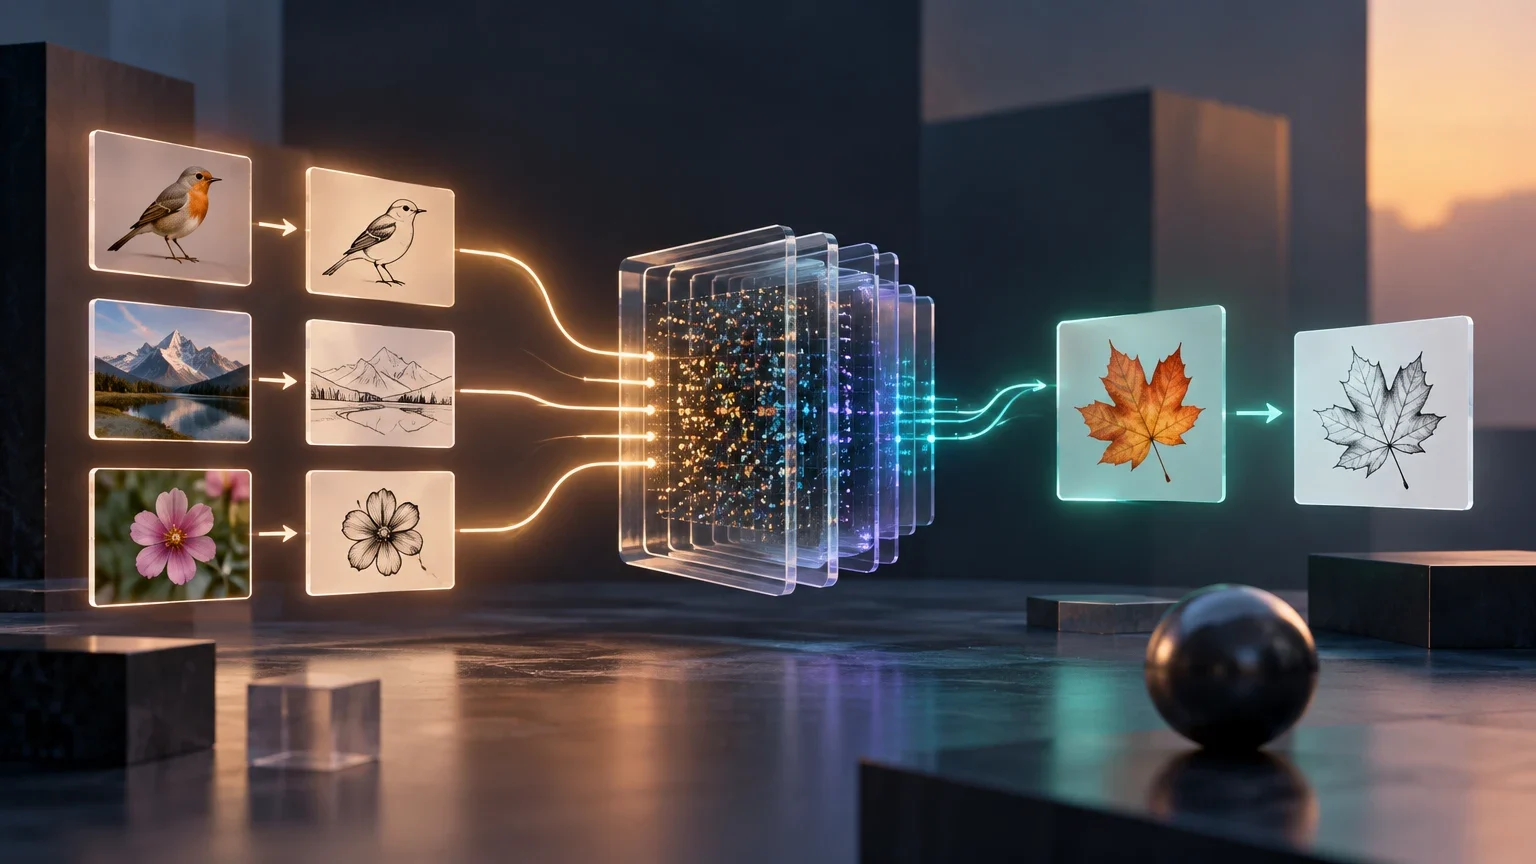
Few-shot prompting is a prompt engineering technique that involves providing a large language model (LLM) with several solved examples of a task within the same instruction. The goal is to guide the model's performance toward a specific output format, tone, or structure without the need for additional training or updating the model's internal parameters.
Unlike traditional supervised learning, where the model is adjusted using a training dataset, few-shot prompting operates exclusively during the inference phase. The information from the examples is processed temporarily within the context window. This distinction is fundamental: the model does not 'memorize' the examples permanently, but uses them as conditioning to generate the response to the new input.
The operational distinction between inference-time conditioning and permanent weight modification is critical for understanding the ephemeral nature of few-shot prompting. Because the model does not update its internal parameters, the 'knowledge' derived from the examples is strictly bound to the specific context window of the current request. This means that the model's ability to perform the task is not a result of long-term memory consolidation, but rather a dynamic alignment of its attention mechanisms with the provided patterns. Consequently, the effectiveness of the technique relies entirely on the model's capacity to process and interpret the examples within the limited scope of the active session, without any residual impact on subsequent independent interactions.
This transient nature also implies that the model's performance is highly dependent on the immediate availability and clarity of the examples within the prompt. If the context window is reset or if the examples are removed, the model reverts to its baseline behavior, which may not align with the specific format or tone required by the task. Therefore, the technique is best understood as a form of real-time instruction tuning that leverages the model's pre-trained capabilities to adapt to new tasks on the fly, rather than a method of permanent skill acquisition. This distinction is essential for developers who need to manage the state of their applications, as it ensures that no persistent data leakage or bias is introduced into the model's core architecture through the use of few-shot examples.
Technical Mechanism: In-Context Learning (ICL)
The underlying mechanism is known as in-context learning (ICL). When the model receives a prompt with examples, the transformer architecture uses the attention mechanism to relate the new input with the provided input-output pairs. The model identifies structural, semantic, and formatting patterns in the examples and applies them to the final query.
Research, such as that by Min et al. (2022), suggests that the model is sensitive to the format and the distribution of labels more than to the individual correctness of each example. This implies that the structural coherence of the examples is as important as their semantic content. The model 'learns' the task by demonstration, mapping the structure of the examples to the new input without performing a gradient calculation.
The reliance on the attention mechanism for in-context learning highlights the importance of structural coherence in the provided examples. Since the model maps the structure of the examples to the new input without performing gradient calculations, the alignment between the input and output pairs must be consistent and unambiguous. This structural mapping allows the model to identify the underlying task logic, such as classification rules or formatting constraints, and apply them to the new query. The sensitivity to the distribution of labels, as noted in research, suggests that the model is not merely memorizing specific instances but is instead learning a generalized pattern that can be applied to similar inputs. This pattern recognition is facilitated by the attention layers, which weigh the relevance of different parts of the context to determine the most appropriate response.
Furthermore, the process of in-context learning is inherently probabilistic, meaning that the model's output is influenced by the statistical likelihood of the patterns observed in the examples. This probabilistic nature implies that the model may occasionally deviate from the expected output if the new input does not perfectly match the distribution of the examples. To mitigate this, it is crucial to ensure that the examples provided are representative of the task's complexity and variability. By doing so, the model can better generalize from the examples to the new input, reducing the risk of errors or inconsistencies in the generated response. This approach underscores the importance of careful prompt design in leveraging the full potential of in-context learning.
In-Context Learning Flow
Process by which the model integrates examples into the context window to generate the output.
- 01The user provides a base instruction and a series of input-output pairs (shots).
- 02The model processes the complete sequence, including the examples, through attention layers.
- 03The attention mechanism identifies correlations between the example inputs and their corresponding outputs.
- 04The model generates the output for the new input, mimicking the pattern established by the examples.
Applied Examples in Three Different Domains
The versatility of few-shot prompting allows its application in classification, data extraction, and code generation tasks. Below are three specific use cases that illustrate how the prompt is constructed and what is expected from the output.
In sentiment classification for technical support, the examples define the categories (positive, negative, neutral) and the response format. In structured data extraction from invoices, the examples show how to map unstructured text to specific JSON fields. In code generation, the examples establish the desired programming style, nomenclature, and error handling practices.
The application of few-shot prompting in sentiment classification for technical support demonstrates the technique's ability to handle nuanced emotional cues within text. By providing examples that clearly define the boundaries between positive, negative, and neutral sentiments, the model can accurately classify new customer messages based on the patterns established in the examples. This is particularly useful in scenarios where the volume of customer feedback is high, and manual classification is impractical. The examples serve as a guide for the model to understand the specific context of technical support, where certain phrases may have different connotations than in other domains. This contextual understanding allows the model to provide more accurate and relevant classifications, improving the overall efficiency of the support process.
In the domain of structured data extraction from invoices, few-shot prompting enables the model to map unstructured text to specific JSON fields with high precision. The examples provided in the prompt illustrate the exact format and structure required for the output, ensuring that the model can consistently extract the relevant data points. This is crucial for automated data processing pipelines, where accuracy and consistency are paramount. By using few-shot prompting, developers can reduce the need for complex rule-based systems or extensive training datasets, making the extraction process more flexible and adaptable to changes in invoice formats. This flexibility is particularly beneficial in environments where invoice structures may vary across different vendors or regions.
Common Confusions: Differences with Related Techniques
It is common to confuse few-shot prompting with other model adaptation techniques. The main difference lies in whether the model's weights are updated and the number of examples used. Zero-shot prompting includes no examples, one-shot includes one, and few-shot includes several (generally between 2 and 10).
Fine-tuning, on the other hand, involves a training process where the model's weights are adjusted using a dataset. Few-shot prompting is faster and cheaper, but less precise for very specific or complex tasks. Chain of Thought (CoT) is a complementary technique that can be combined with few-shot to improve logical reasoning, not a direct alternative.
The distinction between few-shot prompting and fine-tuning is further clarified by the computational resources required for each technique. While fine-tuning involves a significant investment in computational power and time to adjust the model's weights, few-shot prompting operates within the constraints of the inference phase, requiring only the processing of the prompt and examples. This makes few-shot prompting a more accessible and cost-effective solution for tasks that do not require extreme precision or high-volume processing. However, for tasks that demand a high degree of accuracy and consistency, such as those involving complex reasoning or specialized domain knowledge, fine-tuning may still be the preferred approach. The choice between the two techniques should be guided by the specific requirements of the task, the available resources, and the desired level of performance.
Chain of Thought (CoT) serves as a complementary technique to few-shot prompting, enhancing the model's ability to perform logical reasoning by breaking down complex tasks into intermediate steps. When combined with few-shot examples, CoT can guide the model through a structured reasoning process, improving the accuracy of the final output. This combination is particularly useful for tasks that require multi-step reasoning, such as mathematical problems or logical puzzles. By providing examples that include the intermediate reasoning steps, the model can learn to follow a similar logical path when processing new inputs. This synergy between few-shot prompting and CoT allows for a more robust and versatile approach to task adaptation, leveraging the strengths of both techniques to achieve superior performance.
Comparison of Adaptation Techniques
Decision table for choosing the appropriate technique based on resources and task complexity.
| Technique | Examples in prompt | Weight update | Computational cost | Recommended use |
|---|---|---|---|---|
| Zero-shot | 0 | No | Low | Simple and generic tasks |
| One-shot | 1 | No | Low | Basic format clarification |
| Few-shot | 2-10 | No | Medium (tokens) | Specific formats, tone, extraction |
| Fine-tuning | N/A (Dataset) | Yes | High (GPU) | Complex tasks, high volume, extreme precision |
Operational Limits and Practical Considerations
Few-shot prompting is not exempt from limitations. The model's context window limits the number of examples that can be included; if the examples are too long, the token limit may be exceeded, preventing the complete query from being processed. Additionally, the token cost increases linearly with the number of examples, which can impact latency and API costs.
Sensitivity to the order and quality of examples is a critical factor. Studies have shown that the order of examples can influence the model's output, and contradictory or low-quality examples can degrade performance. There is no guarantee of generalization: the model may fail on inputs that differ significantly from the provided examples. For complex reasoning tasks, few-shot alone may be insufficient, requiring advanced techniques like Chain of Thought.
The operational limits of few-shot prompting are further exacerbated by the sensitivity of the model to the order and quality of the examples provided. The phenomenon of recency bias, where the model may favor the last example, and primacy bias, where it may favor the first, can lead to inconsistent outputs if the examples are not carefully curated. To address this, it is recommended to test different orders of examples and to ensure that the examples are representative of the task's variability. This iterative process of testing and refinement helps to identify the most effective configuration of examples, reducing the risk of bias and improving the robustness of the model's output. Additionally, the quality of the examples is crucial; contradictory or low-quality examples can degrade the model's performance, leading to errors or inconsistencies in the generated response.
The lack of a guarantee of generalization is another significant limitation of few-shot prompting. The model may fail on inputs that differ significantly from the provided examples, as it relies on the patterns observed in the examples to generate the output. This limitation is particularly relevant for tasks that involve a wide range of input variations, where the examples may not cover all possible scenarios. To mitigate this, it is important to provide a diverse set of examples that capture the full spectrum of the task's complexity. For complex reasoning tasks, few-shot prompting alone may be insufficient, and advanced techniques such as Chain of Thought may be required to enhance the model's ability to handle novel and complex inputs. This highlights the need for a careful and strategic approach to prompt design, taking into account the specific limitations and capabilities of the model.